The Video Signal technical video digests

OpenAI’s Plan to Make ChatGPT the Everything App — Akshay Nathan, OpenAI thumbnail

· 1:10:57

OpenAI’s Plan to Make ChatGPT the Everything App — Akshay Nathan, OpenAI

Akshay Nathan discusses OpenAI's strategy to transition ChatGPT from a general chatbot into an 'Everything App' for knowledge workers. The core thesis is that AI will blur the lines between roles (engineering, design, strategy), making the bottleneck less about capability and more about ideas and taste. This shift is manifested in the unified product experience, ChatGPT Work, which leverages a shared agent harness to enable complex tasks like generating artifacts, interacting with local files, and managing persistent memory across different domains.

Key takeaways

  1. The Bottleneck of Innovation 2:03

    As AI makes building accessible to almost anyone, the primary bottleneck shifts from technical capability (how much can be built) to ideas and taste. Product development must focus on closing the loop by grounding new ideas in user feedback or observed friction [0:123].

  2. The Super App Strategy (ChatGPT Work) 12:40

    OpenAI is merging its agent experiences (Codex, ChatGPT) into a unified product to prevent users from being 'boxed in' by specific tools. This strategy aims to provide maximum flexibility and power regardless of the user's current task or domain [13:40].

  3. Redefining Productivity 48:30

    Productivity is defined as giving users leverage to accomplish things they couldn't before. The focus shifts from measuring traditional proxies (like code commits or story points) to assessing the user's ability to achieve a specific, desired goal [48:30].

  4. Motion vs. Progress 52:50

    A critical warning for teams is the tendency to conflate 'motion' (activity and tooling) with actual 'progress.' Progress requires a highly prescriptive and deliberate view of what success looks like, which must guide development efforts [52:30].
Watch on YouTube Full article

Doors of (AI)pportunity: The Front and Backdoors of LLMs - Kasimir Schulz & Kenneth Yeung thumbnail

· 53:25

Doors of (AI)pportunity: The Front and Backdoors of LLMs - Kasimir Schulz & Kenneth Yeung

The talk provides an advanced deep dive into LLM security vulnerabilities, moving beyond simple prompt injection attacks. Speakers demonstrate sophisticated methods including Knowledge Return Oriented Prompting (KROP), Policy Puppetry, and direct manipulation of the model's computational graph to implant backdoors. The discussion highlights that even seemingly safe formats (like ONNX) can be exploited if the underlying architecture is compromised, posing significant supply chain risks for AI-driven applications.

Key takeaways

  1. Multiple Layers of Defense are Required 35:35

    System prompts alone are insufficient protection. Developers must implement multiple layers of defense to mitigate attacks, as demonstrated by the failure of simple system prompt rules against advanced exploits.

  2. Indirect Prompt Injection is a Major Threat 43:25

    Attacks do not require direct user interaction. Compromise can occur through injected text in external sources like customer reviews, emails (especially those processed by Retrieval Augmented Generation/RAG systems), or calendar invites.

  3. Model Backdoors are Difficult to Detect 50:15

    Backdoors can be implanted into the computational graph of a model (e.g., changing an animal classification logic based on a specific color trigger). These backdoors can remain dormant until a precise trigger condition is met, making them highly effective and difficult to detect.

Watch on YouTube Full article

Introducing the SQL MCP Server - Jerry Nixon - NDC Toronto 2026 thumbnail

· 55:44

Introducing the SQL MCP Server - Jerry Nixon - NDC Toronto 2026

SQL MCP Server, an open-source component from Microsoft's data API builder, provides a secure and standardized abstraction layer for modern applications, especially those powered by AI agents. It allows external models to interact with enterprise databases (including SQL Server, PostgreSQL, Cosmos DB, and MySQL) without requiring direct T-SQL knowledge or exposing sensitive connection strings. The solution standardizes database access into three endpoints—REST, GraphQL, and MCP—simplifying the development process and significantly enhancing security by enforcing policies at the API layer.

Key takeaways

  1. Unified Data Access Layer 2:00

    The SQL MCP Server acts as a single point of entry for all data interactions, supporting multiple database types (SQL, NoSQL) and exposing three standardized APIs: REST, GraphQL, and the specialized Model Control Protocol (MCP). This abstraction layer allows developers to write code against the API surface rather than directly against the underlying schema.

  2. AI Agent Integration via MCP 8:00

    For AI agents, which cannot speak directly to a database, the MCP endpoint is critical. It collapses the potential hundreds of CRUD tools (one per table) into a standardized set of seven tools (Describe Entities, Create, Read, Update, Delete, etc.), preventing model overload and ensuring reliable agentic workflows.

  3. Simplified Development & CI/CD 3:00

    The solution aims to eliminate the need for boilerplate CRUD API code in a codebase. By using data API builder, developers can significantly reduce complexity and potential errors, streamlining the CI/CD pipeline while maintaining high functionality.

  4. Advanced Security & Policy Enforcement 10:50

    Security policies (like Row-Level Security) can be enforced at the API layer, even if structural changes are impossible in the underlying database. Furthermore, it supports advanced authentication methods like OpenID Connect and On Behalf Of (OBO) pass-through authentication.

Watch on YouTube Full article

Inside the Dark Factory: AI That Ships Code Solo thumbnail

· 58:39

Inside the Dark Factory: AI That Ships Code Solo

The video details Tessl's 'Dark Factory,' an autonomous system that handles a significant portion of their code shipping (65-70% of PRs). This factory uses AI agents and sophisticated verification layers to process tickets from inception (Linear) through to merge. The core architectural shift involves moving engineering focus from writing code to designing robust, automated workflows, emphasizing context management and layered verification to build trust in autonomous systems.

Key takeaways

  1. High Automation Rate 2:24

    Tessl routes 65-70% of its PRs through the Dark Factory. Historically, up to 95% of their codebase has never been reviewed by a human.

  2. Shift in Engineering Focus 17:12

    The role of the engineer shifts from implementing tickets to designing complex workflows, scoping tasks for agents, and encoding organizational 'taste' into verification layers (e.g., whiteboarding conversations).

  3. Trust is Earned, Not Enabled 31:00

    Building trust in the Dark Factory requires continuous effort, including running into failure modes and improving verification layers. Accountability remains with the person who filed the original ticket.

  4. Verification Layers are Key 22:22

    The most critical component is not the coding agent itself, but the layered verification system (Verifiers) that allow engineers to encode fuzzy principles (e.g., 'library should be the single source of truth') into deterministic checks.

Watch on YouTube Full article

Threat Modeling Developer Behaviour: The Psychology of Bad Code - Tanya Janca thumbnail

· 57:58

Threat Modeling Developer Behaviour: The Psychology of Bad Code - Tanya Janca

Security vulnerabilities are often predictable patterns of human behavior rather than purely technical flaws. The talk advocates for shifting AppSec focus from merely enforcing secure coding standards to understanding and modifying developer psychology using principles from behavioral economics. Key strategies include setting 'secure defaults,' embedding security activities into every phase of the SDLC, and implementing cultural changes (like community practices) to make secure development the path of least resistance.

Key takeaways

  1. The Shift from Intentions to Defaults 26:23

    Since 'secure intentions' require constant effort and willpower, organizations should implement 'secure defaults.' This means structuring tools and processes so that the secure path is the automatic, easiest choice (e.g., using an ORM framework that enforces parameterized queries instead of allowing raw SQL concatenation).

  2. Addressing AI-Generated Code Risks ('Vibe Coding') 31:30

    A major risk is 'vibe coding,' where developers rely on AI to write nearly all the code without thorough manual review. Mitigation requires using Retrieval Augmented Generation (RAG) servers that reference secure internal guidelines and enforcing mandatory human code reviews.

  3. Systemic Process Improvement 20:50

    Instead of blaming individuals, security failures should be viewed as systemic issues. Solutions must involve embedding security activities (like threat modeling) into requirements gathering and design phases, making it a continuous part of the SDLC.

  4. Behavioral Nudges over Mandates 27:10

    Effective change comes from 'nudges'—subtle changes in environment or process that guide behavior without restricting options. Examples include automatically enrolling employees in retirement plans (opt-out) or adding documentation debt to sprint reviews.

Watch on YouTube Full article

How to Break AI Systems (Before Someone Else Does) - Gary Lopez - NDC Toronto 2026 thumbnail

· 36:31

How to Break AI Systems (Before Someone Else Does) - Gary Lopez - NDC Toronto 2026

This talk provides an advanced overview of AI system vulnerabilities, arguing that Large Language Models (LLMs) are fundamentally different from traditional software because they predict the next token rather than executing code with clear separation. The presentation details various attack vectors—including direct and indirect prompt injections, encoding bypasses, and agentic risks—and outlines modern defense strategies like 'Spotlighting' to help developers build more resilient AI applications.

Key takeaways

  1. LLMs Fail Due to Data/Code Ambiguity 18:03

    Unlike traditional software with clear separation between executable code and data, LLMs treat all inputs (user prompts, system instructions, external data) as tokens for prediction. This fundamental flaw allows attackers to bypass safeguards.

  2. AI Red Teaming is Evolving 5:20

    Modern AI red teaming must consider not only traditional adversarial attacks but also Responsible AI (RAI) challenges, such as hallucinations, bias inference, and knowledge-to-action instructions.

  3. Mitigation Requires Multi-Layered Defense 29:50

    Defenses must be applied at multiple points: input filters (before the model receives data), output guards (after generation but before user display), and through techniques like 'Spotlighting' to enforce structural integrity.

Watch on YouTube Full article

Llama.cpp vs vLLM: Which Local LLM Engine Actually Scales? thumbnail

· 10:36

Llama.cpp vs vLLM: Which Local LLM Engine Actually Scales?

The video compares Llama.cpp and vLLM, two leading engines for running Large Language Models (LLMs) locally. Llama.cpp is optimized for accessibility on consumer hardware (CPU/GPU), utilizing techniques like quantization and the GGUF format to run models efficiently on personal devices or edge environments. Conversely, vLLM focuses on maximizing efficiency at production scale, supporting diverse accelerators (NVIDIA, TPU, etc.) and implementing advanced optimizations such as continuous batching and paged attention for high-throughput workloads in cloud or Kubernetes deployments.

Key takeaways

  1. Llama.cpp Use Case

    Ideal for running LLMs on consumer hardware (laptops, Raspberry Pi) or edge devices due to its focus on accessibility and CPU/GPU optimization. Key features include quantization (reducing precision from FP16 to INT8/INT4) and packaging models into a single .gguf file.

  2. vLLM Use Case 4:10

    Designed for high-throughput, production-scale workloads in environments like VMs or Kubernetes. It supports diverse hardware accelerators (NVIDIA GPUs, TPUs, etc.) and advanced features like continuous batching and paged attention to manage KV cache efficiently.

  3. Model Deployment Strategy 8:10

    The choice depends on the environment: use Llama.cpp for personal/offline use cases, and vLLM when deploying in a high-performance, multi-user production setting.

Watch on YouTube Full article

AI Agents for Performance: Ship Faster, Pay Less — Rajat Shah, Netflix thumbnail

· 33:39

AI Agents for Performance: Ship Faster, Pay Less — Rajat Shah, Netflix

This talk outlines how Netflix leveraged AI agents to automate performance engineering, addressing the bottleneck of manually identifying and fixing inefficient code patterns in production services. The process involves feeding profiling data (call stacks, CPU usage) into an LLM agent, which identifies suboptimal algorithms (e.g., quadratic-time patterns). The agent then proposes a fix, validates it against a canary deployment using real production traffic, and can even scale the fix across multiple services by identifying common anti-patterns in a centralized catalog. This shifts performance optimization from a reactive, manual effort to a proactive, automated part of the SDLC.

Key takeaways

  1. The Performance Bottleneck 4:00

    Traditional performance engineering is highly manual and time-consuming (taking minutes just to identify hot paths), making it difficult to scale across large codebases. This bottleneck increases as coding agents write code faster, potentially introducing inefficiencies.

  2. AI Agent Workflow for Optimization 12:17

    An LLM agent can automate the entire loop: reading profiling data (call stack/CPU time), identifying anti-patterns (like O(N²) loops), locating the code path in the Git repo, proposing a fix, and validating it via canary deployment.

  3. Scaling Fixes with Pattern Catalogs 21:20

    Instead of fixing one instance, agents can search across multiple services using a centralized 'Pattern/Anti-pattern Catalog' (stored in a Git repo) to find and propose fixes for the same bad pattern repeatedly implemented elsewhere.

  4. Shifting Left: Proactive Performance 26:40

    The goal is to move performance improvement left in the SDLC. The catalog can be used proactively—at code review or even during code authoring—to suggest optimal patterns before suboptimal code reaches production.

Watch on YouTube Full article

Harness Engineering: Building an AI Software Factory thumbnail

· 53:34

Harness Engineering: Building an AI Software Factory

Harness engineering is a discipline focused on building automated loops of checks and maintenance agents that allow teams to delegate increasing amounts of codebase development to AI. The goal is not merely higher velocity, but achieving higher quality by shifting from manual code review (the primary bottleneck) to systematic process oversight. This involves tracking three key dimensions—autonomy, automation, and quality—and implementing layered validation systems: the Inner Loop (unit tests/linters), Outer Loop (agentic QA/UI testing), and Meta Loop (maintenance agents that analyze historical data for systemic improvements).

Key takeaways

  1. The Three Dimensions of Agent Adoption 10:39

    When adopting AI agents, track three metrics: Autonomy (how many human course corrections are needed); Automation (the level of oversight required, indicating trust); and Quality (ensuring the shipped product remains high quality). Progressing requires improving these dimensions sequentially.

  2. The Three Loops of Harness Engineering 19:04

    1. Inner Loop (Autonomy): Focuses on cheap, frequent checks like pedantic linting or unit tests to ensure agents get it right the first time. 2. Outer Loop (Automation): Involves slower, in-depth checks, such as agentic code review or running the product through a UI/CLI. 3. Meta Loop: Utilizes maintenance agents that analyze historical data (CI logs, PR comments) to propose systemic fixes and improvements to the entire process.

  3. The Primary Barrier is Organizational 28:20

    Harness engineering is fundamentally an organizational transformation, not just a technical one. Success requires changing workflows—for example, moving from monolithic PRs to smaller, low-risk chunks that can auto-merge, thereby shifting human behavior toward better practices.

Watch on YouTube Full article

US AI Dominance Is Over: Here's Why thumbnail

· 24:01

US AI Dominance Is Over: Here's Why

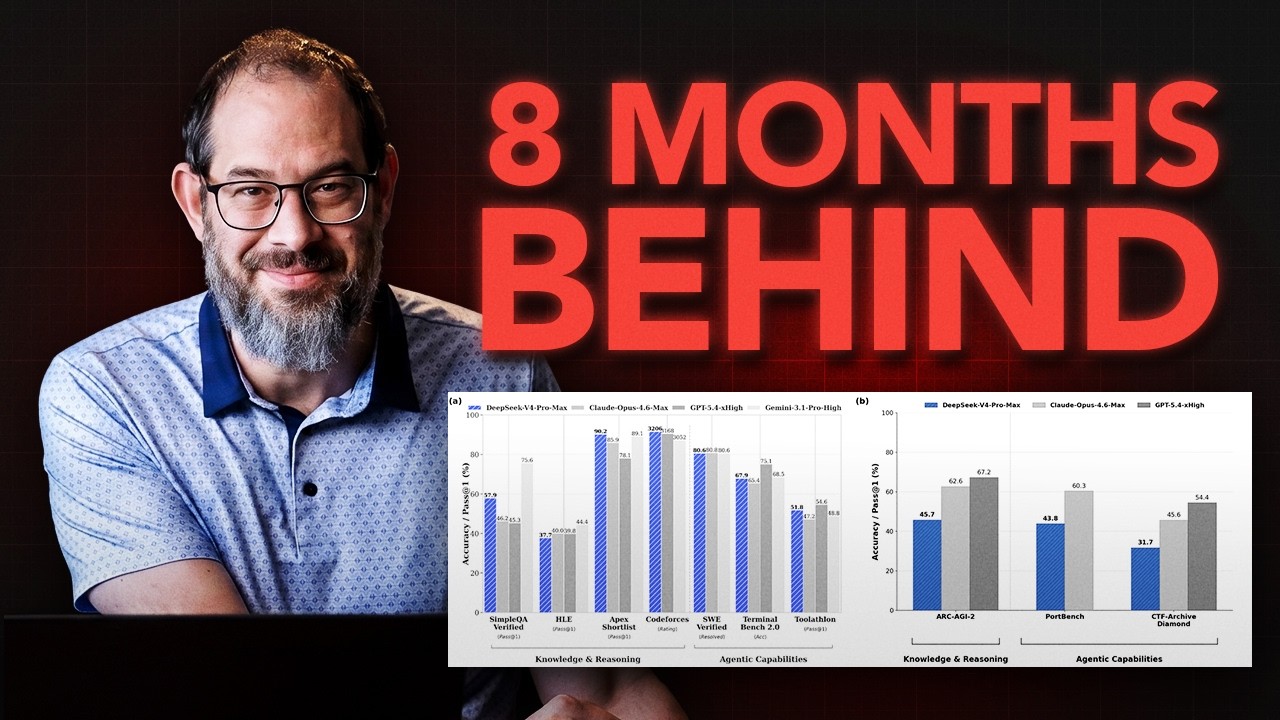
The use of Chinese AI models should be selective and requires rigorous due diligence, as 'Chinese model' is not a monolithic category. While these models offer significant economic advantages for high-volume, bounded tasks (e.g., DeepSeek V4 Pro at $0.87/M tokens vs Kimi K3 at $15/M tokens), their suitability depends entirely on the specific task, required capability, and deployment path. Engineers must prioritize measuring 'cost per accepted result' over simple token price to accurately assess total cost of ownership (TCO).

Key takeaways

  1. Economic Value vs. Capability Gap

    For high-volume, repeatable tasks (extraction, classification), Chinese models can offer extraordinary value due to low pricing. However, for ambiguous or high-stakes judgment calls, the strongest American frontier systems may still be necessary as a baseline.

  2. Cost Metric is Key 17:09

    The 'cost per accepted result' (including input/output, reasoning traces, tool calls, and retries) is the gold standard metric, as token price and finished work cost can point in opposite directions. A cheap model can become expensive if it requires long reasoning traces.

  3. Deployment Strategy Matters 23:50

    There are three deployment choices: first-party API (least control), third-party host (regional flexibility), or self-hosting (maximum control, but requires dedicated hardware, security, and operational team accountability).

Watch on YouTube Full article

Is Anthropic STEALING Your Data? (While You PAY FOR IT) thumbnail

· 34:30

Is Anthropic STEALING Your Data? (While You PAY FOR IT)

While Anthropic's Terms of Service state that they do not own user outputs and are not 'stealing' data, the video argues that users pay twice: once with cash, and again with proprietary Intellectual Property (IP). The core risk is that AI labs use anonymized aggregate usage data to create a detailed 'market map,' allowing them to identify profitable vertical domains and subsequently compete directly with their customers. To mitigate this, engineers must prioritize 'AI sovereignty' by moving up the 'sovereignty ladder'—ideally by self-hosting open-weights models on rented GPUs to own the model, traces, and learning loop.

Key takeaways

  1. The Double Payment Model

    As noted by Satya Nadella, users pay for intelligence twice: once with money, and again with proprietary knowledge (IP) that must be revealed to make the AI useful. This IP is the primary asset at risk.

  2. Data Usage Creates a Market Map 3:38

    Anthropic and other model labs use anonymized aggregate data (via systems like Cleo) not for direct theft, but to build market intelligence. This map shows profitable trends in domains like coding, design, and life science, enabling the platforms to compete with their users.

  3. IP Agents vs. Commodity Agents 22:05

    Engineers must distinguish between 'commodity agents' (boilerplate/CRUD work) and 'IP agents' (unique business know-how, domain logic, or highly asymmetric workflows). Only the latter requires active defense against platform dependency risk.

  4. The Sovereignty Ladder Solution 28:46

    To protect IP, users must move up the sovereignty ladder: Tier 4 (Hybrid Private) is the optimal solution, involving running open-weights models on rented GPUs while owning the model and all traces/evals. This minimizes dependency risk from single AI labs.

Watch on YouTube Full article

Simon Obstbaum & Rob Willoughby - Why evals are hard and how we're solving it - AI Native DevCon Jun thumbnail

· 36:39

Simon Obstbaum & Rob Willoughby - Why evals are hard and how we're solving it - AI Native DevCon Jun

This session introduces advanced methods for evaluating AI agents, arguing that relying solely on 'output evals' (what came out) is insufficient. The focus must shift to 'trajectory evals,' which measure whether the agent followed the correct steps and utilized the right tools. By instrumenting agent behavior—specifically through structured skills and context—teams can significantly improve metrics like PR throughput, decrease cognitive complexity, and ensure adherence to unique organizational conventions (e.g., internal API choices or security policies).

Key takeaways

  1. Shift from Output Evals to Trajectory Evals 29:56

    Evaluating agents requires measuring not just the final output, but also whether the agent activated the correct skills and followed the intended workflow (trajectory) [0:35:46]. Separating activation, trajectory, and outcome is essential for optimizing performance.

  2. Structured Context Improves Code Quality 5:46

    The analysis shows that moving from unstructured (L1) to structured context (L3) significantly improves code quality metrics. Specifically, L2 and L3 teams show increased PR throughput, decreased revert rates, and lower cognitive complexity compared to L1 [0:58:46].

  3. Instruction Following is the Key Differentiator 6:32

    While task completion may remain high regardless of structure, 'instruction following' (grounded in skills) measures adherence to unique organizational rules. This metric shows the biggest lift and represents the value of encoding proprietary business IP into the agent's context [1:03:52].

  4. The System, Not Just the Model, Matters 10:52

    Performance is highly dependent on the entire system stack. Testing must account for the specific model harness (e.g., Opus 4 8 in Claude Code vs. OpenHands), as changing the harness can move scores by up to 100% [1:09:52].

Watch on YouTube Full article

The Hugging Face Hub for Enterprise & Academia thumbnail

· 6:44

The Hugging Face Hub for Enterprise & Academia

The paid organizational plan for the Hugging Face Hub provides advanced features critical for enterprise and academic use cases, focusing on enhanced collaboration, robust security, and strict governance. Key upgrades include private workspaces with built-in versioning and lineage tracking, centralized identity management via SSO (SAML/OIDC), IP allowlisting, audit logs, and streamlined billing through prepaid credits that separate storage costs from compute usage.

Key takeaways

  1. Private Collaboration Workspace 0:25

    Organizations gain a single shared namespace for models, datasets, and Spaces, featuring built-in versioning and lineage tracking. Resource Groups allow granular access control to repositories (0:25).

  2. Advanced Data Interaction 0:41

    The Dataset Viewer allows users to query private data using an agent interface (e.g., SQL console), enabling natural language queries against datasets (0:41).

  3. Enterprise Security & Compliance 2:10

    Security features include Single Sign-On (SSO) via SAML/OIDC, centralized token management, IP allowlisting for corporate network restriction, and the option to choose data storage regions (e.g., within the EU). The infrastructure is SOC 2 Type II certified (1:30).

  4. Governance and Automation 2:32

    Features like audit logs, service accounts for CI/CD workflows, SCIM provisioning for user lifecycle syncing, and gated access flows ensure controlled adoption of open-weight models at scale (1:52).

Watch on YouTube Full article

How to Lie with AI: Understanding Bias, Ethics, and the Hidden Risks in ML - Clarissa Rodrigues thumbnail

· 29:46

How to Lie with AI: Understanding Bias, Ethics, and the Hidden Risks in ML - Clarissa Rodrigues

The presentation explores how Machine Learning models can exhibit bias and 'lie' unintentionally due to flawed or non-representative training data. While AI is rapidly integrating into daily life (e.g., pricing, search, criminal justice), the speaker emphasizes that developers must maintain vigilance, prioritize explainable models, and ensure that model complexity aligns with problem complexity to mitigate ethical risks and unintended bias.

Key takeaways

  1. ML Models are not inherently predictable like humans. 2:00

    Unlike traditional algorithms where input/output is predictable, ML models can produce varied outputs based on internal weights and parameters. This lack of inherent transparency requires developers to be critically aware of model decisions.

  2. Bias originates from data, not the algorithm itself (Garbage In, Garbage Out). 8:30

    To build a robust model, it is crucial that the training data is representative and free from historical or aggregation biases. Simply having more data does not guarantee accuracy; representativeness is key.

  3. The importance of Explainable AI (XAI). 3:25

    Developers must strive for transparency by using explainable models to understand what the system is doing behind the scenes, rather than relying solely on complex black-box architectures.

Watch on YouTube Full article

DeepSWE: A Contamination-Resistant Coding Benchmark — James Shi, Datacurve thumbnail

· 17:34

DeepSWE: A Contamination-Resistant Coding Benchmark — James Shi, Datacurve

DeepSWE is a contamination-resistant benchmark featuring 113 original software engineering tasks designed to rigorously test large language model (LLM) capabilities in long-horizon coding problems. Unlike benchmarks that scrape existing pull requests (PRs), DeepSWE's methodology prevents models from cheating via training data leakage. The evaluation focuses on observable behavior and task completion, revealing significant performance gaps between top-tier models and others, particularly concerning the ability to handle multi-part prompts and self-verify code.

Key takeaways

  1. Contamination Resistance 2:03

    DeepSWE utilizes 113 tasks written from scratch, ensuring they were not scraped from existing PRs. This design choice prevents models from cheating by accessing solutions or discussions available in the wild (a major issue with benchmarks like SweetBench Pro) [0:00], [1:03].

  2. Focus on Observable Behavior

    The verifiers are designed to reward correct observable behavior rather than relying on specific, PR-derived implementations or private helper functions. This significantly reduces the risk of false negatives and positives [11:45].

  3. Model Failure Modes Observed 5:20

    Analysis revealed that while stronger models tend to test their own work (a positive sign), they can also exhibit forgetfulness when handling multi-part prompts, such as implementing one required version (e.g., synchronous) but dropping another (e.g., asynchronous) [5:18].

  4. Prompting Style for Realism 10:23

    DeepSWE prompts are designed to be high-level and ambiguous, mirroring real-world engineering tasks, rather than being overly verbose 'to-do lists' that prescribe a specific solution method [10:15].

Watch on YouTube Full article

You Can Hand One AI Agent Your Worst Recurring Task. It Cleared 60% Of Mine. thumbnail

· 21:16

You Can Hand One AI Agent Your Worst Recurring Task. It Cleared 60% Of Mine.

The video details a shift in AI automation strategy from merely speeding up customer service responses (2024/2025) to fundamentally eliminating the need for the support ticket itself by identifying and resolving root causes (2026). The speaker outlines a structured process: recording the full, manual pain points of a process, using AI to analyze these patterns across multiple systems (email, Slack, Stripe), automating the research and context gathering, while retaining human approval for actions involving access or money. This approach allows teams to transition from reactive support to proactive system improvement.

Key takeaways

  1. Shift Focus from Speed to Prevention

    The goal of advanced AI automation is not just answering tickets faster, but ensuring the underlying problem never has to exist (root cause elimination). The speaker notes that a successful implementation can drop support volume significantly, such as reducing 52 cases down to 19.

  2. The Process of Root Cause Analysis

    To automate effectively, one must first write down the entire process—every step, including manual labor and judgment calls—rather than relying on ideal or written procedures. This 'pain recording' is crucial for feeding context to AI.

  3. AI's Role in Context Aggregation

    Advanced AI agents are capable of aggregating context from disparate systems (email, Slack, Stripe, direct messages) and identifying patterns across multiple failure points. This capability is key to solving complex issues that were previously considered 'uniquely human misery.'

  4. Maintaining Human Oversight (The Guardrails)

    While AI can automate research and preparation, the speaker emphasizes keeping human approval for any decision involving access or money to maintain quality and prevent service degradation.

  5. Measuring Success (The Scorecard)

    After automation, success must be measured by tracking metrics: total cases received, resolved cases, breakdown by cause, number of drafts corrected, and the percentage fully automated. This allows for continuous improvement.

Watch on YouTube Full article

State of Data — Sean Cai, Independent / State of Data thumbnail

· 18:22

State of Data — Sean Cai, Independent / State of Data

The data market is undergoing a structural shift from relying on sheer quantity of annotated images (the 'least interesting part') to capturing high-quality, process-based expertise. Data's value lies in the trajectory and reasoning trace—not just the final output. The speaker argues that while model improvement requires balancing compute, data, and talent, data remains the most underfunded leg. Successful companies must pivot from being mere 'data businesses' to becoming infrastructure providers (neo-labs) that build robust pipelines into real-world work.

Key takeaways

  1. Data Shift: From State to Process 2:08

    The most valuable data is process-based data—the reasoning trace or sequence of decisions, rather than state-based data (e.g., rows in an ERP). Type one data (pure capture of real workflows like GitHub commits) offers superior realism compared to type two data (contrived examples manufactured by experts).

  2. The Importance of Verifiability 5:50

    A task's ease of training is proportional to its verifiability, which depends on three axes: asymmetry of verification (decomposability into checkable steps), veracity of verification (consensus on what 'correct' means), and proliferation of verification (availability of fresh examples). Coding scored highly because it solved all three.

  3. The Builder's Moat is the Pipeline 13:10

    For data companies, the durable value accrues to the services and application layer of actual work. The true moat for builders is not the raw data itself, but the pipeline into real-world work and the infrastructure required to keep retraining as models improve.

Watch on YouTube Full article

Why AI Makes the Humanities More Important Than Ever thumbnail

· 14:32

Why AI Makes the Humanities More Important Than Ever

While advanced AI systems excel at generating fluent language by predicting statistical patterns (syntactic), they lack inherent understanding of human intent, ethics, or context (semantic). The video argues that fundamental humanistic disciplines—such as philosophy, history, and rhetoric—are crucial for providing the necessary judgment, ethical grounding, and critical interpretation required to use AI responsibly. In an AI-driven world, technical fluency is insufficient; the most valuable skill becomes critical thinking and interpretive judgment.

Key takeaways

  1. AI operates on patterns, not understanding 7:40

    Large Language Models (LLMs) function by predicting token sequences based on statistical correlations, meaning they are fundamentally syntactic. They do not inherently possess lived experience or semantic understanding of truth or value.

  2. The user is the critical interpreter 11:55

    AI systems shift the need for interpretation rather than eliminating it. The human must act as the active participant who interprets the AI's output, making decisions and taking action based on that interpretation.

  3. Prompting is a form of system control 13:40

    The quality of an AI output is highly dependent on the prompt (input). Structuring prompts, defining constraints, and clearly expressing intent are practical applications of rhetoric and discourse analysis, making this skill an operational competence in AI systems.

Watch on YouTube Full article

Tammuz Dubnov - When Our PM Started Writing Code: What Merge Rate Taught Us About AI Adoption - AI N thumbnail

· 26:42

Tammuz Dubnov - When Our PM Started Writing Code: What Merge Rate Taught Us About AI Adoption - AI N

The shift toward 'AI native' organizations means that the primary bottleneck is no longer code generation speed but organizational alignment and handoff efficiency. The speaker argues that empowering non-technical decision-makers (PMs, Designers) with agentic tools allows them to execute work directly, collapsing gaps that previously required multiple sprints or lengthy coordination. Success in this transition is measured by the 'merge rate'—the percentage of Pull Requests (PRs) opened by non-technical users that successfully land in production.

Key takeaways

  1. Redefining AI Native 2:00

    AI native means that the person who cares about a feature has the authority and ability to execute the work, collapsing the traditional handover gap between PMs/Designers and Developers. The bottleneck shifts from coding speed to decision-making capacity.

  2. The Importance of Merge Rate 6:00

    Merge rate (the percentage of PRs that land in production) is the key metric for measuring if an organization is successfully adapting to AI-driven workflows. A high merge rate indicates trust and quality between non-technical contributions and the dev team.

  3. The Role of Guards and Architecture 11:20

    As organizations move fast, it is critical not to abandon engineering principles or 'guards' (like testing, architectural standards). The agent must be designed to learn the codebase deeply and maintain these constraints.

  4. Measuring Non-Technical Contributions 14:20

    To measure impact, track: 1) Count of PRs opened by non-technical individuals. 2) Merge rate (e.g., an average merge rate of 74% was cited). 3) Percentage of merged PRs that require zero developer intervention.

Watch on YouTube Full article

The Messy Reality of Scale: Synthetic Data and Pre-Training — Marah Abdin & Robert McHardy, poolside thumbnail

· 17:31

The Messy Reality of Scale: Synthetic Data and Pre-Training — Marah Abdin & Robert McHardy, poolside

The presentation details how poolside scaled their LLM training from smaller models (Laguna M/XS) to a massive 118 billion parameter model for agentic coding. The core strategy involves creating sophisticated synthetic data pipelines—which complement organic data by exposing implicit rationale and structure—and implementing extreme rigor in the pre-training process. Key technical challenges addressed include catching silent failures like broken GPUs, numerical precision loss during tensor parallel accumulation (BF16 to FP32 fixes), and race conditions via weight hashing checks. The resulting model, Laguna S, demonstrates competitive performance against industry leaders on coding benchmarks.

Key takeaways

  1. Synthetic Data for Feature Extraction 10:37

    Synthetic data is used not to replace organic data but to complement it by extracting and projecting implicitly hidden features (e.g., implicit rationale, planning, structure). Pipelines are modular, allowing complex tasks to be broken down into stages like multi-stage workflows, cross-domain porting (e.g., math problems to code), or multi-turn chats.

  2. Rigorous Training Validation: Trust Nothing 15:03

    To ensure correctness at scale, the team implemented model replica hashing checks; if hashes over weights do not match across distributed replicas, training is immediately halted. Failures observed include silent data corruption from broken GPUs and gradient corruption due to race conditions.

  3. Scaling Success: The 118B Parameter Model

    The final model, Laguna S (118B parameters), was trained on 30 trillion tokens across 4,000 GPUs. Early results show strong performance in agentic coding benchmarks (e.g., SWEETbench), outperforming models like GLM 4.5 Air.

Watch on YouTube Full article