Channel

Stanford Online

Digests from Stanford Online — Stanford Online technical and educational videos.

When AI Stops Being a Project: Turning Technology into Real Value for Patients and Providers thumbnail

· 36:50

When AI Stops Being a Project: Turning Technology into Real Value for Patients and Providers

The conversation explores the shift of AI from a mere 'project' to an integral business function in healthcare. Key focus areas include moving beyond simple Q&A chatbots to complex, long-running agentic workflows that can handle tasks previously requiring many hours of human effort. Speakers emphasize that while the technology is rapidly advancing (e.g., GLM 5.2 and advanced LLMs), successful enterprise adoption requires significant architectural changes: establishing robust governance, managing token costs, mitigating vendor lock-in, and fundamentally reimagining existing clinical workflows rather than simply automating point solutions.

Key takeaways

  1. Shift to Agentic Workflows 14:25

    AI is moving past simple Q&A (quick, short, transactional) toward complex, long-running agentic tasks. OpenAI internal data suggests agents are now performing work across finance, recruiting, and legal that can take up to 8 hours of human effort [0:14:25].

  2. Governance and Architecture are Critical 23:15

    For large enterprises (like United Health Group), long-form agentic work requires establishing strong governance, guardrails, and security protocols. Simply calling an API a 'super agent' is insufficient; true agency requires reasoning and decision-making capabilities [0:23:15].

  3. Addressing Vendor Lock-in and Cost 4:46

    Enterprises must manage the risks of vendor lock-in when restructuring workflows around a single model or API. Concerns include escalating token costs and geopolitical instability, making architectural flexibility paramount [0:47:28].

  4. Reimagining vs. Automating Silos 3:31

    The most impactful approach is not to automate existing tasks (silos) but to fundamentally reimagine the entire end-to-end workflow—from patient intake to payment processing—given the new technological capabilities [0:35:12].

  5. AI as a Business Mandate 5:46

    Successful adoption requires AI to be elevated from an IT or innovation problem to a CEO-level, cross-functional business mandate. Leadership must obsess over defining the core metrics (the 'what is the metric?') and driving change at scale [0:57:12].
Watch on YouTube Full article

Stanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 19: Model-Based RL thumbnail

· 1:21:50

Stanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 19: Model-Based RL

This lecture reviews advanced topics in Reinforcement Learning (RL), transitioning from model-free policy optimization methods (TRPO/PPO) to the critical challenges of Model-Based RL. The core focus is addressing model uncertainty when using learned dynamics for planning. Techniques such as Bayesian statistics, Gaussian Processes (GPs), and Ensembles are introduced to quantify epistemic uncertainty, allowing planners to compute expected rewards by averaging predictions over a posterior distribution of possible models.

Key takeaways

  1. PPO/TRPO for Policy Optimization 16:15

    Policy optimization methods (like TRPO and PPO) define a surrogate objective function to estimate the policy gradient, enabling continuous updates. PPO uses a clipped ratio ($ ext{clip}(r_{ heta}, 1- ext{eps}, 1+ ext{eps})$) to constrain the new policy's divergence from the old one, stabilizing training without requiring complex second-order optimization.

  2. Model-Based RL Limitations 25:00

    The basic model-based recipe (collect data $ ightarrow$ fit dynamics $P(s'|s, a)$ $ ightarrow$ plan) fails when dealing with complex or nonlinear dynamics because extrapolation outside the observed state distribution is unreliable. This issue of generalization and distribution shift must be addressed.

  3. Quantifying Model Uncertainty 35:00

    To improve model-based planning, uncertainty quantification is necessary. The distinction between Aleatoric (inherent noise) and Epistemic (model uncertainty) is crucial. Bayesian approaches treat this by modeling the posterior distribution over parameters ($ heta$), allowing for prediction averaging across all plausible models.

  4. Ensemble Methods for Uncertainty 46:40

    A practical approach to estimate model uncertainty is using ensembles: training multiple independent neural network copies. The average of their predictions approximates the predictive posterior distribution, effectively exploring multimodal solution landscapes without requiring complex analytical derivations.

Watch on YouTube Full article

Stanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 17: RL Value-Based Methods thumbnail

· 1:17:40

Stanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 17: RL Value-Based Methods

This lecture provides a comprehensive review of model-free Reinforcement Learning (RL) value-based methods. The discussion progresses from foundational concepts—distinguishing between prediction and control—to comparing Monte Carlo (MC) and Temporal Difference (TD) learning. Key algorithms covered include SARSA and Q-learning, which are differentiated by their on-policy versus off-policy nature. To scale these methods to high-dimensional state spaces, the necessity of function approximation is introduced, leading into Deep Q Networks (DQN). The lecture concludes by detailing two critical stabilization techniques for DQN: Experience Replay (to decorrelate samples) and using Fixed Q Targets (to stabilize the target value during training).

Key takeaways

  1. MC vs. TD Learning Paradigms 17:03

    Monte Carlo methods estimate the expected return ($G_t$) by rolling out an episode until a terminal state, requiring full episodes. Temporal Difference (TD) learning improves upon this by using bootstrapping—defining the target as the instantaneous reward plus the discounted future value ($ ext{Reward} + ext{Discounted Future Value}$), allowing for online updates and handling non-terminal environments.

  2. On-Policy vs. Off-Policy Learning 23:50

    SARSA is an on-policy algorithm, meaning it improves the policy ($ ext{e.g., } ext{epsilon-greedy}$) that is actively used to generate data in the environment. Q-learning is off-policy; it learns about a target optimal policy (the greedy policy) while using data generated by a different behavior policy (also $ ext{epsilon-greedy}$), which is crucial for utilizing historical or simulated data.

  3. Scaling with Function Approximation 35:05

    To overcome the curse of dimensionality inherent in tabular value function representations, RL methods transition to parametric functions (e.g., neural networks) that approximate $V(s)$ or $Q(s, a)$. This allows generalization across states and controls.

  4. DQN Stabilization Techniques 1:03:20

    Deep Q Networks (DQN) stabilize learning using two methods: Experience Replay (storing transitions in a buffer to decorrelate samples, satisfying the IID assumption required for regression) and Fixed Q Targets (using a delayed copy of the network parameters ($ ext{Q}_{ ext{target}}$) to prevent the target from being a moving variable during optimization).

Watch on YouTube Full article

Stanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 11: Introduction to MPC thumbnail

· 1:13:36

Stanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 11: Introduction to MPC

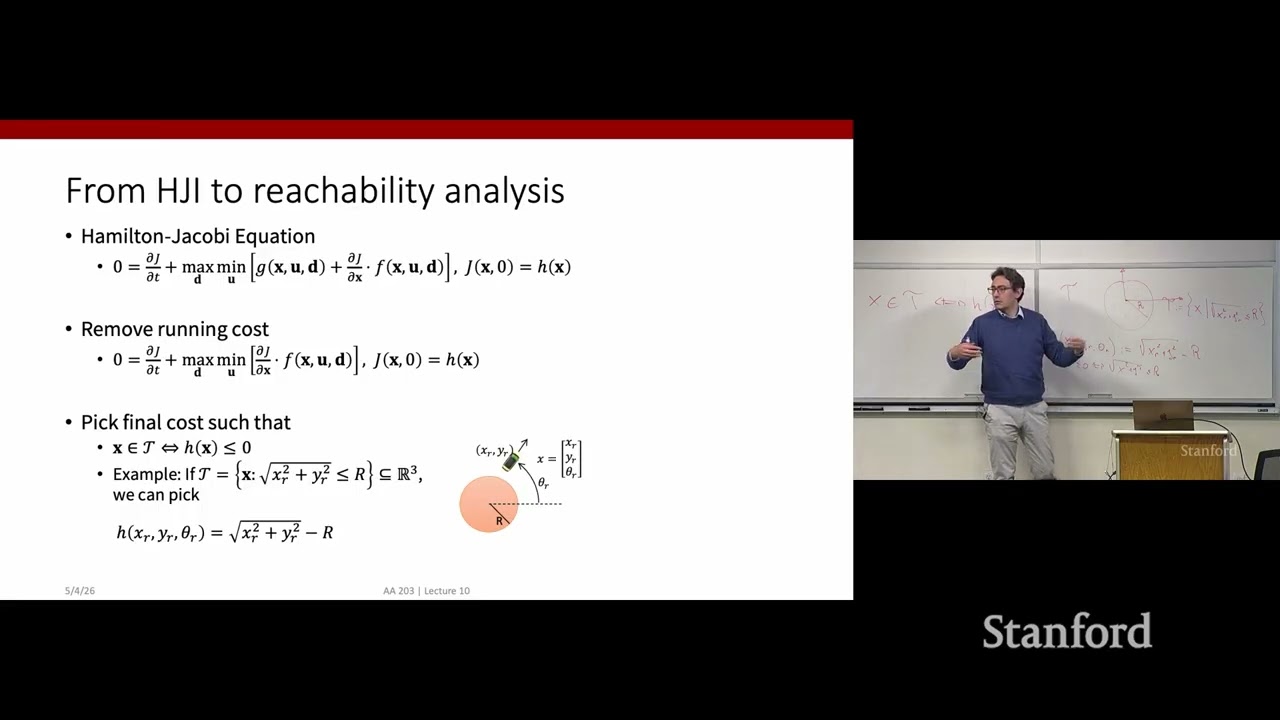
This lecture provides a deep dive into advanced control theory, transitioning from theoretical concepts like Hamilton-Jacobi-Isaacs (HJI) equations for computing reachable sets to the practical framework of Model Predictive Control (MPC). The discussion emphasizes that MPC achieves closed-loop performance by repeatedly solving an open-loop optimal control problem over a finite horizon (receding horizon optimization). Key theoretical challenges addressed include ensuring persistent feasibility and stability, which requires leveraging concepts from invariant set theory.

Key takeaways

  1. Reachable Sets via HJI Equation 0:35

    Avoidance sets and reachable sets are computed by solving a differential game using the Hamilton-Jacobi-Isaacs (HJI) equation. This involves reframing the Boolean problem of set membership into an optimal control cost function $h(x)$ [0:35].

  2. Backward Reachable Tube (BRT) 7:40

    To ensure safety over the entire trajectory, not just the endpoint, one must compute a Backward Reachable Tube (BRT). This is achieved by modifying the cost function to minimize the minimum value of $h(x)$ across the entire optimization horizon [7:40].

  3. MPC Receding Horizon Principle 19:30

    MPC solves an open-loop optimal control problem over a finite prediction horizon $[t, t+N_p]$ at each time step $t$. It then uses only the first computed input ($u_t$) and discards the rest of the plan, recomputing everything from scratch based on new state measurements (receding horizon) [19:30].

  4. MPC Design Goals 36:00

    The primary goals when designing an MPC controller are ensuring persistent feasibility (the problem remains solvable at all future times) and guaranteeing stability (convergence to the desired state, e.g., the origin) [36:00].

  5. Invariant Sets for Feasibility 1:08:40

    To guarantee persistent feasibility in MPC, one must identify a control invariant set $\mathcal{C}$. This is a set where, if the system starts within it, there exists a control input $u$ that guarantees the next state remains inside $\mathcal{C}$ [38:00].

Watch on YouTube Full article

Stanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 9: Stochastic Dyn. Program thumbnail

· 1:17:01

Stanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 9: Stochastic Dyn. Program

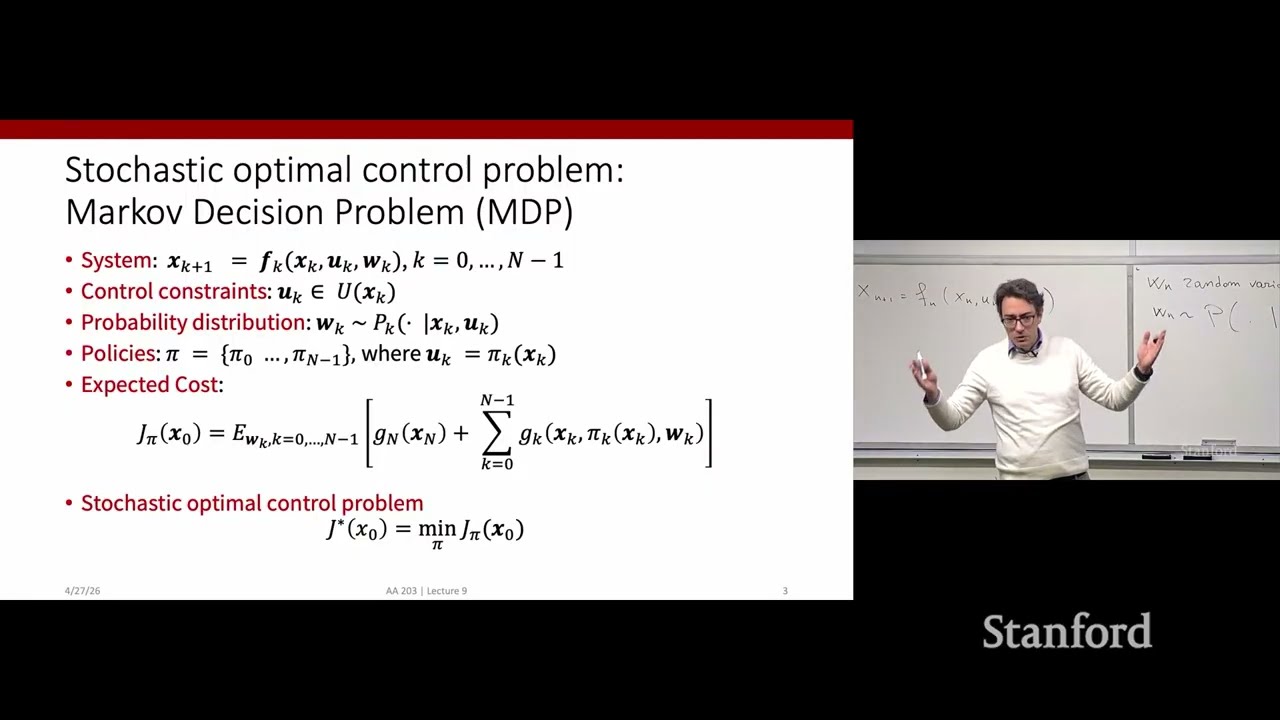
This lecture details the extension of optimal control theory from deterministic settings to stochastic environments using Markov Decision Processes (MDPs). The core methodology involves defining state transitions and costs that incorporate random disturbances ($w_k$). For finite-horizon problems, the solution relies on adapting the Bellman recursion by taking the expectation over all disturbance realizations. Crucially, for infinite-horizon MDPs—which are foundational to Reinforcement Learning (RL)—the problem is simplified by assuming stationarity and introducing a discount factor ($\gamma$), leading to fixed-point equations for the optimal value function ($V^*$) and the Q-function ($Q^*$).

Key takeaways

  1. Stochastic State Dynamics (MDP) 2:00

    The state update is modeled as $x_{k+1} = f(x_k, u_k, w_k)$, where $w_k$ is a random disturbance. The system must adhere to the Markovian assumption: the probability distribution of $w_k$ can only depend on the current state ($x_k$) and control ($u_k$), not on the history of previous states or disturbances.

  2. Finite-Horizon Optimization 4:00

    The notion of optimality is defined by minimizing the expected cost, $\mathbb{E}[ ext{Cost}]$, over all possible disturbance realizations. The solution uses a backward dynamic programming recursion (Bellman equation) to find the optimal closed-loop policy $\pi^*$.

  3. Infinite-Horizon MDPs and Discounting 10:20

    To solve problems over an infinite number of stages, a discount factor ($\gamma \in [0, 1]$) is introduced to ensure the convergence of the expected cumulative reward. The optimal value function $V^*$ satisfies a fixed-point equation: $V^*(x) = \max_{u} \{ R(x, u) + \gamma \mathbb{E}[V^*(x')]\}$.

  4. The Q-Function Formulation 17:30

    For computational tractability in learning settings where the transition kernel is unknown, the problem can be reformulated using the Q-function ($Q^*$), which represents the expected cumulative reward starting at state $x$ and taking action $u$, followed by optimal actions: $Q^*(x, u) = R(x, u) + \gamma \sum_{x'} T(x'|x, u) V^*(x')$.

Watch on YouTube Full article

AStanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 8: Nonlinearity thumbnail

· 1:14:05

AStanford AA203 Optimal and Learning-Based Control | Spring 2026 | Lecture 8: Nonlinearity

This lecture provides an advanced overview of Linear-Quadratic Regulator (LQR) theory, extending its application from simple state regulation to complex nonlinear trajectory tracking and optimization. Key concepts include reformulating nonlinear tracking problems using deviation variables ($\delta x$, $\delta u$) to create an auxiliary LQR problem. The discussion culminates in two sophisticated iterative methods: Iterative LQR (iLQR), which linearizes dynamics and quadratizes costs, and Differential Dynamic Programming (DDP), which directly approximates the Bellman equation, offering a second-order approach for optimal control.

Key takeaways

  1. LQR as a General Tool 18:03

    While LQR is fundamentally designed to drive a state to the origin (regulation), it can be generalized to perform trajectory tracking by defining an auxiliary problem based on deviation variables. The optimal control law structure remains consistent: $u = u_{nominal} + ext{feedback term}$.

  2. Nonlinear Tracking via Linearization 24:10

    For nonlinear dynamics ($x_{k+1} = f(x_k, u_k)$), the tracking problem can be linearized by performing a Taylor expansion around the nominal trajectory ($\bar{x}, \bar{u}$), allowing the use of LQR techniques on the deviation variables.

  3. iLQR vs. DDP 35:05

    Both iLQR and DDP are methods for solving nonlinear optimal control problems iteratively. iLQR linearizes dynamics and quadratizes costs, while DDP directly approximates the Bellman equation by quadratizing the Q-function, making it a second-order algorithm in terms of dynamic derivatives.

Watch on YouTube Full article

Stanford CS329A Self-Improving AI Agents | Part 4 | Learning from Feedback with Tools/Code thumbnail

· 1:11:13

Stanford CS329A Self-Improving AI Agents | Part 4 | Learning from Feedback with Tools/Code

This lecture details three advanced methodologies for building self-improving AI agents: ReAct, RLEF, and Constitutional AI. These techniques enable Large Language Models (LLMs) to move beyond simple text generation by incorporating external feedback loops—whether through environment interaction, code execution results, or self-critique. For build engineering, the core takeaway is that robust agentic behavior requires structured methods for grounding reasoning in real-world data and iterative refinement using test feedback.

Key takeaways

  1. ReAct: Combining Reasoning and Action 0:03

    The ReAct framework combines Chain-of-Thought (reasoning) with tool-calling actions, creating an interleaved loop (thought $ ightarrow$ act $ ightarrow$ observe). This allows models to ground their reasoning in external knowledge sources, improving performance on tasks like HotpotQA and WebShop. [0:03]

  2. RLEF: Grounding Code LLMs via Execution Feedback 0:12

    RLEF is an end-to-end RL fine-tuning framework for coding agents that uses execution feedback (test pass/fail) as a binary reward signal. It employs a two-tier test strategy, using public tests for inference-time guidance and private tests for training the policy model via PPO. [0:12]

  3. Constitutional AI: Self-Correction through Principles 0:15

    This method improves LLMs by having them critique their own outputs against a set of human-written principles (the 'Constitution'). This generates feedback for training the model's preference model, reducing reliance on constant human labeling. [0:15]

Watch on YouTube Full article

Stanford CS329A Self-Improving AI Agents | Part 1 | Course Overview thumbnail

· 1:09:42

Stanford CS329A Self-Improving AI Agents | Part 1 | Course Overview

This course overview details the evolution of Large Language Models (LLMs) from simple predictive models to complex, self-improving agents. Key advancements include understanding scaling laws based on parameters, compute, and data size; developing advanced reasoning capabilities through Chain-of-Thought (CoT); and moving beyond single-turn chat interactions into sophisticated agentic workflows. The focus shifts to building systems that can plan, interact with external tools, self-correct using verifiers, and achieve end-to-end goals in domains like software engineering and data analysis.

Key takeaways

  1. LLM Scaling Laws 2:20

    Model performance improves significantly by scaling up parameters, compute (compute on the x-axis), or dataset size. This exponential growth has been foundational for models like GPT-3 and PaLM.

  2. Agentic Workflows vs. Chatbots 17:05

    Modern LLM applications are moving from single-turn chat formats to complex agentic workflows (e.g., Deep Research, Cloud Code). These systems can take a goal, plan steps, interact with environments/tools, and correct their actions until the goal is achieved.

  3. The Role of Verifiers 22:00

    In agentic systems, verifiers (like unit tests for code) are crucial feedback mechanisms. They allow models to verify generated outputs and guide self-correction, which is essential in verifiable domains like math and coding.

  4. Self-Improvement Loop 27:30

    The most advanced frontier involves combining test time scaling (e.g., repeated sampling) with fine-tuning to generate synthetic, high-quality data. This creates a self-improving loop where the model trains on its own generated solutions.

Watch on YouTube Full article

Stanford CS329A Self-Improving AI Agents | Part 2 | Test-Time Compute Scaling thumbnail

· 1:03:21

Stanford CS329A Self-Improving AI Agents | Part 2 | Test-Time Compute Scaling

The lecture details advanced methods for improving Large Language Model (LLM) performance through 'inference scaling' or 'test-time compute scaling,' rather than relying solely on expensive pre-training. Key techniques include repeated sampling (Large Language Monkeys), which shows that coverage follows a predictable power law with the number of samples. The discussion highlights the critical need for robust verification mechanisms to bridge the generation-verification gap, and concludes by introducing the Arkon framework, an architecture search method that optimizes complex inference pipelines using components like Fusion, Critic, and Ranker.

Key takeaways

  1. Inference Scaling Paradigm Shift 1:45

    LLM capability can be significantly enhanced at inference time by increasing compute (e.g., repeated sampling) without modifying model parameters or requiring fine-tuning, offering a new paradigm compared to traditional pre-training and fine-tuning.

  2. Repeated Sampling Effectiveness 2:40

    By repeatedly querying the same problem (e.g., using Llama 3-8b or DeepSeek), selecting the correct response among candidates, models can achieve performance comparable to larger proprietary models like GPT-4o.

  3. The Role of Verification 7:50

    For repeated sampling to be effective, automated verification is crucial. The 'generation-verification gap' describes the large difference between the best possible outcome (Oracle selection) and what can be achieved using simple methods like majority voting.

  4. Advanced Scaling Architectures 20:30

    The Arkon framework treats inference scaling as an architecture design problem, optimizing the combination of techniques (e.g., Fusion, Critic, Ranker) to maximize accuracy given a limited compute budget.

Watch on YouTube Full article

Stanford CS329A Self-Improving AI Agents | Part 3 | Robust Verification thumbnail

· 1:12:59

Stanford CS329A Self-Improving AI Agents | Part 3 | Robust Verification

This lecture traces the evolution of verification methods for Large Language Model (LLM) outputs, aiming to close the generation-verification gap. The discussion covers four major research advancements: training verifiers using outcome-based reward models (GSM8K), implementing process-based supervision via PRMs (PRM800K), automating annotation with Math-Shepherd, and finally, combining multiple weak verifiers into a robust system using Weaver. Key findings highlight that process supervision is generally superior to outcome supervision, and ensembling multiple specialized verifiers significantly boosts model accuracy on complex reasoning tasks.

Key takeaways

  1. Process Supervision vs. Outcome Supervision 26:00

    While outcome-based reward models (ORM) only check the final answer's correctness, process-based reward models (PRM) assign rewards per step of reasoning. PRMs are superior because they manage false positives better and encourage interpretable, human-endorsed steps [2:36:00].

  2. Ensembling Weak Verifiers (Weaver) 23:02

    The Weaver approach combines multiple weak verifiers (e.g., LLM judges, reward models) using techniques like Naive Bayes or logistic regression to create a single, highly capable verifier. This method significantly improves performance by leveraging the collective signal of diverse sources [3:42:00].

  3. Data Efficiency and Scaling 26:00

    PRMs are shown to be more data-efficient than ORMs. Furthermore, the lecture demonstrates that scaling verification by increasing the number of verifiers (rather than just sampling more completions) can improve results while maintaining computational efficiency [3:42:00].

  4. The Role of Self-Improvement 17:36

    Advanced techniques involve using the model itself to generate data (e.g., Math-Shepherd) and then training a PRM on this synthetic, semi-automated data, allowing the system to self-improve its reasoning capabilities [2:56:00].

Watch on YouTube Full article

Stanford CS329A Self-Improving AI Agents | Part 6 | Train Time Scaling/Scaling RL thumbnail

· 1:12:39

Stanford CS329A Self-Improving AI Agents | Part 6 | Train Time Scaling/Scaling RL

This lecture explores advanced techniques for scaling Large Language Model (LLM) reasoning capabilities through 'train-time scaling' and Reinforcement Learning (RL). The discussion covers three key papers: STaR (Self-Taught Reasoner), DeepSeekMath, and DAPO. Key findings demonstrate that smaller models can achieve high accuracy on complex benchmarks like AIME by leveraging structured training data generation (STaR) or advanced RL algorithms (DAPO/GRPO). The core insight is that closing the feedback loop—using model outputs to improve the model itself—is crucial for boosting reasoning, especially in domains with verifiability.

Key takeaways

  1. Train-Time Scaling vs. Test-Time Scaling 2:00

    While test-time scaling (inference-based techniques like majority voting) improves accuracy by sampling outputs, train-time scaling uses the model's own filtered outputs to fine-tune and improve the model weights directly, creating a powerful closed feedback loop.

  2. STaR Boosts Reasoning via Rationalization 6:30

    The STaR method bootstraps reasoning by generating solutions on a small set of examples. It filters for correct answers and then generates rationales (hints) for incorrect attempts, allowing the model to learn from failed paths iteratively.

  3. GRPO Addresses RL Memory Constraints 10:05

    DeepSeekMath introduced Group Relative Policy Optimization (GRPO), an efficient alternative to PPO that reduces memory overhead by using a group baseline instead of maintaining multiple policy copies, enabling scaling RL to larger models.

  4. DAPO Stabilizes Complex Reasoning 17:30

    DAPO addresses training instability in long chain-of-thought reasoning by implementing asymmetric clipping (allowing bigger increases) and dynamic sampling (filtering out zero or one reward groups to maintain a useful gradient signal).

Watch on YouTube Full article

Stanford CS547 HCI Seminar | Spring 2026 | Show It or Tell It? Text, Visualization, and Combination thumbnail

· 56:19

Stanford CS547 HCI Seminar | Spring 2026 | Show It or Tell It? Text, Visualization, and Combination

This seminar explores the complex intersection of text and data visualization, arguing that language is a critical component of effective information design. The discussion moves from established cognitive theories (like Dual Coding Theory) to modern AI architectures, detailing how Multimodal Large Language Models (MLLMs) process combined visual and textual inputs using mechanisms like cross-attention. Key findings suggest that while the optimal balance between text and visuals is highly context-dependent, MLLMs are capable of deeply integrating both modalities.

Key takeaways

  1. Language is a key component of visualization 5:19

    Studies show that titles and labels receive long fixations during encoding and are the most likely elements to be recalled, suggesting language significantly impacts how data visualizations are understood. The speaker notes this was historically under-explored in the visualization community.

  2. Optimal design favors annotation over minimalism 21:30

    Research suggests that 'more text is better' for general information displays, provided the text is relevant and properly annotated. This finding challenges traditional minimalist principles in UI/UX design.

  3. MLLMs integrate modalities via cross-attention 41:20

    Multimodal LLMs (MLLMs) process text and visuals by transforming inputs into embeddings. The 'cross-modality embedding architecture' uses a cross-attention mechanism, allowing information to flow between the two distinct sequences (e.g., image tokens interacting with text tokens).

  4. Cognitive processing is context-dependent 30:00

    The speaker notes that understanding how humans integrate text and visuals is complex, citing conflicting evidence across theories (Dual Coding vs. Cognitive Load Theory). The choice of representation depends heavily on the specific task or cognitive ability.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 20: GMM (EM), PCA thumbnail

· 1:18:56

Stanford CS229 Machine Learning | Spring 2026 | Lecture 20: GMM (EM), PCA

This lecture provides an advanced deep dive into training Large Language Models (LLMs) using Reinforcement Learning (RL). It reviews Policy Gradient methods, detailing the mathematical derivations and limitations. The core focus shifts to Proximal Policy Optimization (PPO), a critical algorithm for stabilizing RL updates by utilizing importance sampling ratios and clipping mechanisms. Finally, the lecture applies these concepts to LLM generation, explaining how Chain-of-Thought (CoT) prompting can be formalized as an MDP problem solved via PPO/SISO.

Key takeaways

  1. Policy Gradient Theory 20:40

    The policy gradient estimator is necessary because the dependency on parameters ($ heta$) is complex. The fundamental property that $ abla_{ heta} ext{E}_{ ext{P}_{ heta}}[ abla_{ heta} ext{log } ext{P}_{ heta}(a|s)]$ equals zero shows that without a reward function, there are no preferences to optimize for.

  2. Proximal Policy Optimization (PPO) 26:40

    PPO is designed to stabilize RL training by using importance sampling and clipping the objective function. This prevents the new policy ($ heta$) from deviating too far from the old policy ($ heta_{old}$), which helps maintain stable learning.

  3. LLM Generation as an MDP 1:01:40

    The LLM generation process is modeled as a Markov Decision Process (MDP). The state ($s_t$) includes the history, and the action ($a_t$) is the next generated token. The reward function is typically applied only at the end of the trajectory based on whether the final answer matches the ground truth.

  4. Chain-of-Thought (CoT) Training 1:05:00

    To train models for complex reasoning, RL can be used to reward the entire trajectory based on the final answer's correctness. This approach bypasses the need for explicit labeling of the internal 'thinking tokens,' focusing only on verifiable outcomes.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 18: GMM (EM), PCA thumbnail

· 1:16:25

Stanford CS229 Machine Learning | Spring 2026 | Lecture 18: GMM (EM), PCA

This lecture provides a deep dive into Reinforcement Learning (RL), focusing on the formal framework of Markov Decision Processes (MDPs) and the Policy Gradient method. The core objective is to solve sequential decision-making problems by maximizing expected cumulative reward. Key concepts include defining states ($S$), actions ($A$), stochastic transition dynamics ($P(s'|s, a)$), and utilizing the Bellman equation for recursive value estimation. The lecture concludes with an explanation of the Policy Gradient algorithm (REINFORCE), detailing how to compute the gradient of the expected return using log-probability tricks, which is crucial for training policies in large models.

Key takeaways

  1. Sequential Decision Making & RL Fundamentals

    RL addresses sequential decision-making where actions have long-term ramifications. It requires balancing the trade-off between exploitation (using current best knowledge) and exploration (gathering information). Learning relies on maximizing a scalar reward signal rather than explicit labels or supervision.

  2. Markov Decision Process (MDP) Framework 4:00

    An MDP formally describes an environment using five components: State Set ($S$), Action Set ($A$), Transition Dynamics ($P(s'|s, a)$), Reward Function ($R$), and Discount Factor ($\gamma$). The Markov property ensures that the future state transition depends only on the current state and action, not on history.

  3. Value Functions and Bellman Equation 28:50

    The value function $V^{\pi}(s)$ estimates the expected total payoff starting at state $s$ under policy $\pi$. The optimal value, $V^*(s)$, is the maximum possible return. These values are solved recursively using the Bellman equation, which relates the current state's value to the expected discounted future rewards.

  4. Policy Gradient Method (REINFORCE) 43:20

    The Policy Gradient algorithm optimizes a stochastic policy $\pi_{\theta}(a|s)$ by maximizing the expected return $E[R]$. The gradient is computed using the log-probability trick, allowing the calculation of $\nabla_{\theta} E[R]$ through sampling, even when the dependency on $\theta$ only affects the sampling distribution.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 16: Basic Concept in RL, Policy Gradient thumbnail

· 1:13:19

Stanford CS229 Machine Learning | Spring 2026 | Lecture 16: Basic Concept in RL, Policy Gradient

This lecture provides an advanced deep dive into optimizing Transformer architectures for efficiency and adapting Large Language Models (LLMs) for various downstream tasks. Key focus areas include reducing the quadratic complexity of attention through techniques like Grouped Query Attention (GQA) and Sliding Window Attention; scaling models using Mixture of Experts (MoE) to decouple memory from compute; and exploring prompt-based methods such as In-Context Learning, Few-Shot, and Zero-Shot learning for task adaptation without updating model parameters.

Key takeaways

  1. Efficiency in Attention Mechanisms 20:04

    The standard self-attention mechanism has $O(T^2)$ complexity (where T is sequence length). To mitigate this, techniques like Grouped Query Attention (GQA) reduce the number of keys and values used across heads by mapping multiple query groups to a smaller set of shared keys/values. Similarly, Sliding Window Attention limits attention to only recent history, reducing complexity to $O(T imes W)$ where W is the window size.

  2. Scaling with Mixture of Experts (MoE) 42:28

    MoE allows models to have a large total parameter count (e.g., 30B) while keeping the active computation small (e.g., 3B). This is achieved by using a routing module that directs an input vector to only a subset of specialized expert sub-networks, significantly improving compute efficiency.

  3. LLM Adaptation via Prompting 56:48

    For downstream tasks (e.g., sentiment analysis), models can be adapted using In-Context Learning (ICL). This involves concatenating task examples and the test input into the prompt sequence without updating model parameters, which is fundamentally different from traditional fine-tuning.

  4. Supervised Fine-Tuning (SFT) 1:04:00

    SFT involves collecting data in an instruction/answer pair format and training the model by minimizing the negative log likelihood of predicting the answer ($Y$) given the instruction ($X$). This is a supervised process that updates the model's weights.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 14: Transformers, In-Context Learning thumbnail

· 1:17:32

Stanford CS229 Machine Learning | Spring 2026 | Lecture 14: Transformers, In-Context Learning

This lecture provides a deep technical dive into Large Language Models (LLMs), focusing on the Transformer architecture. Key concepts covered include subword tokenization (using techniques like Byte Pair Encoding - BPE) to convert text into numerical IDs, and modeling language distribution using auto-regressive conditional probabilities. The core mechanism is the self-attention layer, which uses Query (Q), Key (K), and Value (V) vectors to determine dependencies between tokens. A critical technical discussion centers on computational efficiency: standard attention has a quadratic $O(T^2)$ dependency on sequence length ($T$), leading to memory and computation bottlenecks for long contexts. Solutions like masking and specialized variants (e.g., Flash Attention) are discussed as methods to maintain performance while managing resource constraints.

Key takeaways

  1. Auto-Regressive Modeling 1:35

    LLMs model language distribution by decomposing the joint probability into a product of conditional probabilities: $P(X_t | X_{1...t-1})$. This requires generating tokens sequentially, making the process auto-regressive.

  2. Subword Tokenization (BPE) 3:30

    To handle rare or long words efficiently, models use subword tokenization (e.g., BPE), which breaks down text into smaller units (tokens). This allows leveraging common prefixes and suffixes to understand novel words.

  3. Self-Attention Mechanism 11:10

    The attention mechanism calculates the relevance between all tokens in a sequence using Query ($Q$), Key ($K$), and Value ($V$) vectors via an inner product: $ ext{Softmax}(Q K^T / ext{scale}) V$. The output is a weighted linear combination of $V$ vectors.

  4. Causal Masking for Auto-regression 21:20

    To ensure the model only predicts based on previous tokens (required for generation), a masking technique is applied to the attention matrix, setting all future dependencies to $- ext{infinity}$ before applying Softmax.

  5. Computational Bottleneck ($O(T^2)$) 30:00

    The standard self-attention mechanism has a computational and memory complexity that scales quadratically with sequence length $T$ (i.e., $O(T^2)$). This is the primary limitation for processing very long contexts.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 12: Representation Learning thumbnail

· 1:15:57

Stanford CS229 Machine Learning | Spring 2026 | Lecture 12: Representation Learning

The lecture provides a deep dive into advanced generative and adaptation techniques, covering Diffusion Models, Foundation Model paradigms, and Representation Learning. Key technical focus areas include deriving the loss function for diffusion models by comparing true and predicted mean reconstructions ($\mu_{ ilde{t}, t}$ vs $\mu_{ heta, t}$). For large language models (LLMs), the discussion highlights the shift toward using massive unlabelled data for pre-training and adapting via zero-shot or few-shot methods. Finally, it details advanced parameter efficiency techniques like Linear Probing and Low-Rank Adaptation (LoRA), which are crucial for managing memory and compute when deploying large models across multiple users.

Key takeaways

  1. Diffusion Model Training Objective 33:55

    The training objective is derived from the lower bound on $\log p_ heta(x_0)$, simplifying to minimizing a sum of terms ($\mathcal{L}_{t-1}$) that compares the mean predicted reconstruction ($\mu_{ heta, t}$) with the true process mean ($\mu_{ ilde{t}, t}$). This loss function is used to train the model to predict noise/reconstruct missing information at each time step.

  2. Foundation Model Paradigm Shift 1:02:00

    Modern LLMs utilize a paradigm shift involving pre-training on massive unlabelled data and adapting via zero-shot or few-shot learning, reducing the need for collecting extensive downstream labeled datasets. The goal is to build a general foundation that can be adapted to unlimited tasks.

  3. Low-Rank Adaptation (LoRA) Efficiency 1:15:00

    To adapt massive pre-trained models without changing all parameters ($\theta$), LoRA restricts the weight update matrix $\Delta W$ to a low rank ($A B$). This significantly reduces the number of trainable parameters and is critical for memory efficiency, especially when serving multiple users.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 11: Diffusion Models thumbnail

· 1:22:31

Stanford CS229 Machine Learning | Spring 2026 | Lecture 11: Diffusion Models

The lecture introduces Diffusion Models as a predominant class of generative models used for tasks like image, video, and action generation. The core mechanism involves two processes: the forward process (gradually adding Gaussian noise to an original clean image $X_0$ over time steps $T$) and the reverse process (learning to iteratively denoise the noisy data back to a clean state). Training these models is achieved by applying the Evidence Lower Bound (ELBO) framework, which minimizes the Kullback-Leibler (KL) divergence between the true conditional distribution and the parameterized model's prediction.

Key takeaways

  1. Diffusion Models Overview

    These models are generative frameworks that can be applied to images, videos, and robotics actions. They are noted as a superior approach compared to GANs and Variational Autoencoders (VAEs) for image generation.

  2. Forward vs. Reverse Process 4:05

    The forward process is a fixed, known noising process that transforms $X_0$ to noise $X_T$. The reverse process is the learned component, parameterized by $ heta$, which predicts $p_ heta(X_{t-1}|X_t)$—the step-by-step denoising path.

  3. Training Objective (ELBO) 6:25

    The goal is to maximize the marginal likelihood $ ext{log } p_ heta(X_0)$ by applying the Evidence Lower Bound (ELBO). This involves minimizing the KL divergence between the true posterior $q(X_{t-1}|X_t, X_0)$ and the parameterized model's distribution.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 10: GMM (EM), PCA thumbnail

· 1:20:06

Stanford CS229 Machine Learning | Spring 2026 | Lecture 10: GMM (EM), PCA

This lecture provides a deep dive into two foundational unsupervised machine learning techniques: Gaussian Mixture Models (GMM) solved via the Expectation-Maximization (EM) algorithm, and Principal Component Analysis (PCA). The discussion emphasizes the mathematical underpinnings of these methods. For GMM, the EM algorithm is shown to solve for latent variables by constructing a tractable lower bound using Jensen's inequality. For PCA, the technique identifies directions of maximum variance by performing Eigen Decomposition on the data's covariance matrix, highlighting the critical need for proper data centering and scaling.

Key takeaways

  1. GMM via EM Algorithm 23:20

    The Expectation-Maximization (EM) algorithm is used to estimate parameters ($ heta$) for GMM. It operates by constructing a lower bound $L( heta|T)$ of the log-likelihood, which allows optimization through alternating steps: E-step (calculating soft assignments/probabilities $Q_i(Z)$) and M-step (re-estimating parameters $oldsymbol{ heta}$).

  2. PCA Core Principle 1:03:20

    PCA is a dimensionality reduction technique that finds orthogonal unit vectors (principal components, $U_k$) corresponding to the directions of maximal variance in the data. The process relies on finding the Eigen Decomposition ($oldsymbol{A} = oldsymbol{U} oldsymbol{ ext{diag}}(oldsymbol{ ext{eigenvalues}}) oldsymbol{U}^T$) of the covariance matrix.

  3. Mathematical Rigor (Jensen's Inequality) 27:10

    The EM algorithm leverages Jensen's inequality to transform an intractable expectation into a manageable lower bound, enabling iterative optimization. The selection of the conditional probability $Q(Z)$ is key to achieving this tight lower bound.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 9: K-Means and GMM (non-EM) thumbnail

· 1:16:30

Stanford CS229 Machine Learning | Spring 2026 | Lecture 9: K-Means and GMM (non-EM)

This lecture provides a deep dive into unsupervised machine learning algorithms, focusing on K-Means clustering and its probabilistic extension, Gaussian Mixture Models (GMM). The core mathematical framework for solving GMM is the Expectation-Maximization (EM) algorithm. Key concepts include understanding how to model structure without explicit labels, utilizing latent variables, and employing convex analysis via Jensen's inequality to derive the iterative estimation procedure.

Key takeaways

  1. Unsupervised vs. Supervised Learning 2:00

    Unlike supervised learning (where labels define separation), unsupervised learning aims to model inherent structure or clusters within unlabeled data, making it a fundamentally more challenging problem that requires stronger assumptions and accepting weaker guarantees.

  2. K-Means Clustering 5:50

    K-Means is an iterative algorithm where points are assigned to the nearest cluster center ($oldsymbol{ ext{mu}}_i$). The process involves two steps: (1) assigning each point to its closest $oldsymbol{ ext{mu}}$, and (2) recalculating the new cluster centers based on the arithmetic mean of all assigned points. Finding the optimal clustering is NP-hard, meaning initialization matters.

  3. Gaussian Mixture Models (GMM) 10:50

    GMMs are a probabilistic relaxation of K-Means, modeling data as mixtures of Gaussian distributions. Instead of hard assignments, points are assigned probabilities to belong to each source/cluster. The model is defined by means ($oldsymbol{ ext{mu}}$), covariances ($oldsymbol{ ext{Sigma}}$), and mixing proportions ($oldsymbol{f}$).

  4. Expectation-Maximization (EM) Algorithm 17:30

    The EM algorithm is used to estimate the parameters of latent variable models like GMM. It alternates between two steps: the E-step (calculating the probability $W_{ij}$ that each point belongs to each source given current parameter estimates) and the M-step (re-estimating all model parameters, including means and covariances, based on these probabilities).

  5. Convexity and Jensen's Inequality 30:00

    The EM algorithm relies on convex analysis. Convex functions are those where the line segment connecting any two points lies above the function graph (e.g., $x^2$). Jensen's inequality is used to derive a lower bound for the log-likelihood function, allowing the complex optimization problem to be solved iteratively.

Watch on YouTube Full article