Topic

Diffusion Models

All digests tagged Diffusion Models

Training Krea 2: What matters in generative model training — Sangwu Lee, Krea.ai thumbnail

· 21:46

Training Krea 2: What matters in generative model training — Sangwu Lee, Krea.ai

Sangwu Lee details the training methodology for Krea 2, an open-sourced image foundation model, emphasizing that data curation is the most critical factor after architecture is locked. The talk contrasts production models (like ChatGPT-2) which prioritize consistency and reliability but suffer from mode collapse, with Krea 2's focus on stylistic diversity and fast iteration. Key techniques covered include advanced deduplication using hash-based methods (pHash/MD5) followed by embedding-based approaches (SigLip), specialized captioning pipelines to capture contextual details (e.g., a painting being framed), and multi-stage training from low to high resolution.

Key takeaways

  1. Data is Paramount for Model Quality 9:59

    After locking in the architecture, data curation determines model performance. The goal was to maximize stylistic diversity while filtering out undesirable content (e.g., images where captions consistently fail to capture important context) and avoiding reliance on synthetic AI-generated training data due to its 'sticky' aesthetic.

  2. Balancing Consistency vs. Diversity 2:20

    Large production models often achieve high consistency by focusing on the 'average' subject (e.g., a boring average person), leading to mode collapse and limited stylistic range. Krea 2 was designed to optimize for fast generation and broad stylistic exploration, catering to creative studios that are still defining their visual goals.

  3. Advanced Deduplication and Filtering 16:55

    Deduplication runs first on basic hashes (pHash or MD5) across billions of images, followed by embedding-based methods like SigLip to remove near duplicates. Filters are also applied using large vision language models (VLMs), which are then distilled into cheap classifiers for scalable filtering over massive datasets.

  4. Multi-Stage Training Pipeline

    The training process progresses through several stages: low to high resolution pre-training (learning semantics first, then structure/detail), supervised fine-tuning (SFT), preference optimization (collecting user pairs for comparison), and Reinforcement Learning (RL). The final step involves training a prompt expander LLM to generate detailed prompts that align with the model's trained data distribution.
Watch on YouTube Full article

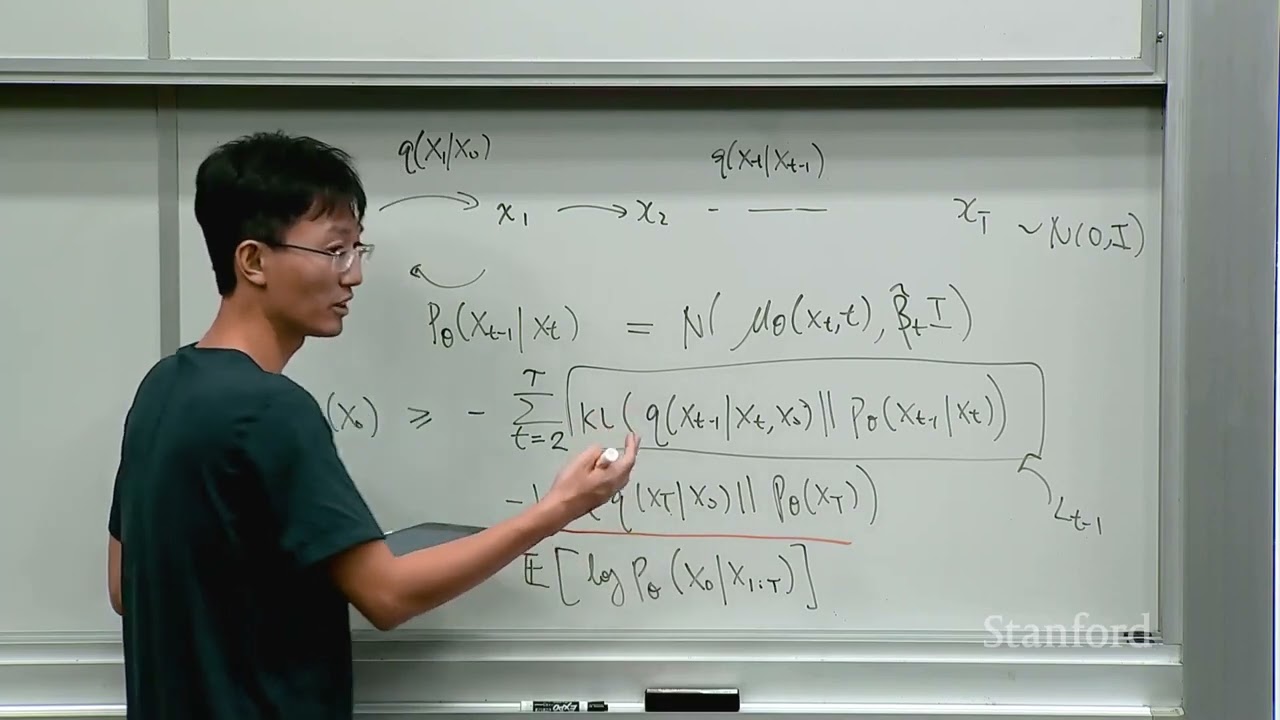
Stanford CS229 Machine Learning | Spring 2026 | Lecture 12: Representation Learning thumbnail

· 1:15:57

Stanford CS229 Machine Learning | Spring 2026 | Lecture 12: Representation Learning

The lecture provides a deep dive into advanced generative and adaptation techniques, covering Diffusion Models, Foundation Model paradigms, and Representation Learning. Key technical focus areas include deriving the loss function for diffusion models by comparing true and predicted mean reconstructions ($\mu_{ ilde{t}, t}$ vs $\mu_{ heta, t}$). For large language models (LLMs), the discussion highlights the shift toward using massive unlabelled data for pre-training and adapting via zero-shot or few-shot methods. Finally, it details advanced parameter efficiency techniques like Linear Probing and Low-Rank Adaptation (LoRA), which are crucial for managing memory and compute when deploying large models across multiple users.

Key takeaways

  1. Diffusion Model Training Objective 33:55

    The training objective is derived from the lower bound on $\log p_ heta(x_0)$, simplifying to minimizing a sum of terms ($\mathcal{L}_{t-1}$) that compares the mean predicted reconstruction ($\mu_{ heta, t}$) with the true process mean ($\mu_{ ilde{t}, t}$). This loss function is used to train the model to predict noise/reconstruct missing information at each time step.

  2. Foundation Model Paradigm Shift 1:02:00

    Modern LLMs utilize a paradigm shift involving pre-training on massive unlabelled data and adapting via zero-shot or few-shot learning, reducing the need for collecting extensive downstream labeled datasets. The goal is to build a general foundation that can be adapted to unlimited tasks.

  3. Low-Rank Adaptation (LoRA) Efficiency 1:15:00

    To adapt massive pre-trained models without changing all parameters ($\theta$), LoRA restricts the weight update matrix $\Delta W$ to a low rank ($A B$). This significantly reduces the number of trainable parameters and is critical for memory efficiency, especially when serving multiple users.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 11: Diffusion Models thumbnail

· 1:22:31

Stanford CS229 Machine Learning | Spring 2026 | Lecture 11: Diffusion Models

The lecture introduces Diffusion Models as a predominant class of generative models used for tasks like image, video, and action generation. The core mechanism involves two processes: the forward process (gradually adding Gaussian noise to an original clean image $X_0$ over time steps $T$) and the reverse process (learning to iteratively denoise the noisy data back to a clean state). Training these models is achieved by applying the Evidence Lower Bound (ELBO) framework, which minimizes the Kullback-Leibler (KL) divergence between the true conditional distribution and the parameterized model's prediction.

Key takeaways

  1. Diffusion Models Overview

    These models are generative frameworks that can be applied to images, videos, and robotics actions. They are noted as a superior approach compared to GANs and Variational Autoencoders (VAEs) for image generation.

  2. Forward vs. Reverse Process 4:05

    The forward process is a fixed, known noising process that transforms $X_0$ to noise $X_T$. The reverse process is the learned component, parameterized by $ heta$, which predicts $p_ heta(X_{t-1}|X_t)$—the step-by-step denoising path.

  3. Training Objective (ELBO) 6:25

    The goal is to maximize the marginal likelihood $ ext{log } p_ heta(X_0)$ by applying the Evidence Lower Bound (ELBO). This involves minimizing the KL divergence between the true posterior $q(X_{t-1}|X_t, X_0)$ and the parameterized model's distribution.

Watch on YouTube Full article

Stanford CS229 Machine Learning | Spring 2026 | Lecture 1: Introduction thumbnail

· 36:59

Stanford CS229 Machine Learning | Spring 2026 | Lecture 1: Introduction

This lecture provides a high-level introduction to Machine Learning fundamentals (Supervised, Unsupervised, and Reinforcement Learning) within the context of modern AI. The course emphasizes understanding the mathematical foundations and core techniques behind algorithms rather than focusing on programming implementation. Key topics include model training using large datasets, advanced concepts like embeddings, and the architectural differences between traditional ML tasks and general-purpose Large Language Models (LLMs). A critical focus for system builders is placed on the necessity of optimizing ML systems for hardware compatibility and speed.

Key takeaways

  1. ML Paradigm Shift 6:11

    The field has moved from specific, task-oriented models to general-purpose agents (LLMs). While traditional methods still apply, the focus is on tuning fundamental model capabilities rather than building complex data pipelines for every single use case.

  2. The Importance of ML Systems 33:00

    A planned lecture will cover 'ML system,' which addresses the critical need to make software and hardware compatible. Optimizing algorithms for speed (e.g., making them run 2x faster) is crucial due to the high cost associated with AI computation.

  3. Reinforcement Learning (RL) in LLMs 24:50

    RL can be used to train models dealing with stochastic sampling, such as text generation. Techniques like Policy Gradient and using human feedback (e.g., RLHF/RAG) are necessary because the generation process is not differentiable.

Watch on YouTube Full article

Causal Models Need Causal Data - Xaira’s X-Cell model (Bo Wang & Ci Chu) thumbnail

· 1:29:47

Causal Models Need Causal Data - Xaira’s X-Cell model (Bo Wang & Ci Chu)

Xaira Therapeutics introduced X-Cell, a novel 4.9-billion-parameter diffusion language model designed as a virtual cell foundation model of biology. The model is trained on X-Atlas/Pisces—a massive dataset spanning 25.6 million single cells across 16 biological contexts and generated via the Perturb-seq platform. The core breakthrough lies in shifting from descriptive (observational) data to causal (interventional) data, allowing the model to predict how a cell will respond to genetic perturbations it has never encountered. This capability is crucial for advancing drug discovery by moving beyond trial-and-error methods.

Key takeaways

  1. Causality vs. Correlation in Biology 20:07

    Observational atlases (descriptive data) can describe biology, but they are fundamentally underpowered to learn causality. To predict the outcome of an intervention (e.g., knocking down a gene), causal data—generated through high-throughput perturbation screens—is required.

  2. X-Cell Architecture and Training 1:03:27

    X-Cell utilizes a diffusion language model approach, which treats gene expression prediction as an iterative 'editing' process rather than an autoregressive one. This architecture allows it to generate high-dimensional transcriptomic data by refining noisy representations until they minimize loss against the ground truth.

  3. Data Generation Scale and Engineering 1:16:47

    The model is powered by Perturb-seq, a technique combining high-throughput CRISPR perturbation with single-cell RNA sequencing. This process generates massive 2D datasets (perturbation on one axis, gene expression on the other) across millions of cells while minimizing batch effects.

  4. Generalization and Translational Potential 1:25:07

    X-Cell demonstrated impressive generalization by accurately predicting perturbation responses in active T-cells, even when the model was only trained on resting T-cell data. This suggests the potential to predict novel biology in unseen contexts.

Watch on YouTube Full article