Channel

AI Engineer

Digests from AI Engineer

Agents Without Code: Skills, YAML, and Filesystems Replaced Python — Philipp Schmid, Google DeepMind thumbnail

· 18:28

Agents Without Code: Skills, YAML, and Filesystems Replaced Python — Philipp Schmid, Google DeepMind

The presentation details the evolution of LLM agents, demonstrating a shift from complex, brittle Python code loops to declarative, file-based definitions using system instructions and skills. The speaker shows that modern agent architectures, such as the Gemini API's anti-gravity agent, utilize a hosted sandbox and network proxy to manage state and credentials securely. This allows agents to operate using general-purpose tools (like GitHub CLI or Google Search) defined in files (e.g., `AGENTS.md`), drastically reducing the need for thousands of lines of custom orchestration code.

Key takeaways

  1. The Agent Evolution: Code to Files

    Agent development is moving away from writing explicit Python loops, JSON schemas, and tool routing logic. The core functionality is now expressed in files (Markdown/Skills) that define instructions, rules, and capabilities, allowing the model to use general tools.

  2. Server-Side State Management 14:02

    The new architecture handles complex tasks by moving loops, tool routing, session state, and context compaction to the server side, requiring only a single API call with new inputs.

  3. Security and Isolation 12:32

    A hosted sandbox and network proxy ensure that the agent never sees the actual credentials, injecting tokens only when outbound requests are made, and allowing domain restriction for enhanced security.

  4. Focus on Domain Logic 16:40

    The primary work for developers is now defining the domain instructions, rules, and evaluation criteria (the 'what'), rather than writing the infrastructure code (the 'how').
Watch on YouTube Full article

How We Solved Agent Building — Andrew Qu, Vercel thumbnail

· 17:34

How We Solved Agent Building — Andrew Qu, Vercel

Andrew Qu details Vercel's journey in solving agent building, evolving from initial manual data querying to complex, multi-step agent architectures. The major breakthrough was realizing that the core capability was not a clever toolset, but the simple file system (list, read, bash). This insight led to the development of Eve, a framework designed to bring file system conventions (like Next.js) to agents, enabling developers to build highly customized, production-ready agents with minimal effort.

Key takeaways

  1. The File System Unlock 11:57

    The most significant breakthrough was realizing that powerful agents could be built using a minimal set of tools—specifically, file system operations (list, read, run bash)—which models are already well-trained on. This approach allowed agents to explore and write where needed, leading to a massive increase in performance (the eval score basically doubled).

  2. Focus on Company-Specific Knowledge 17:00

    While off-the-shelf agents are useful, the speaker argues that the most effective agents are those stuffed with deep, company-specific knowledge. These custom agents provide the most 'juice' and save significant time across various departments (e.g., legal, finance, data science).

  3. The Need for a Framework (Eve) 15:40

    To simplify agent development, Vercel built Eve, described as the 'Next.js for agents.' It adopts file system conventions, allowing developers to easily declare skills, tools, and channels, making the process of building and iterating on agents highly manageable.

Watch on YouTube Full article

No Memory, No Harness: Why the Database Is the Last Line of Defense — Kay Malcolm, Oracle thumbnail

· 21:37

No Memory, No Harness: Why the Database Is the Last Line of Defense — Kay Malcolm, Oracle

Kay Malcolm argues that while AI models (agents) are powerful, they are incomplete without a robust, centralized memory system. She frames the agent as the 'brain,' the surrounding system as the 'harness' (body), and the database as the 'central nervous system' (memory). The core problem addressed is that current systems (like Git) track code changes, not the human intent or context behind them. To solve this, she advocates for using a unified Oracle AI database to store all five types of agent memory (short-term, long-term, episodic, procedural, and semantic) in a single source of truth, preventing context loss when scaling to enterprise teams.

Key takeaways

  1. AI's Limitation: Code vs. Intent 5:36

    AI tools make individuals faster, but they do not automatically make teams more productive if the context and reasoning behind the code are not shared. Git only records what changed, not the human intent (3:36).

  2. The Agent Architecture Model 11:54

    An enterprise agent requires three components: the Model (the brain), the Harness (the body, enabling action), and Memory (the central nervous system, carrying context) (7:14).

  3. The Five Types of Memory 13:29

    Effective agent memory must distinguish between: short-term (within a session), long-term (across sessions), episodic (what happened last time), procedural (steps taken), and semantic (meaning) (8:09).

  4. The Need for a Single Source of Truth 17:34

    When data is spread across multiple specialized databases (relational, document, graph, vector), agents struggle to reconcile the truth, often guessing incorrectly and wasting tokens (10:54).

  5. The Solution: Unified Database Memory

    A unified database (like the Oracle AI database) is necessary to store all memory types (JSON, relational, graph, vector) in one place, ensuring the agent's memory is non-negotiable and accessible across the entire team (14:24).

Watch on YouTube Full article

We let an AI agent execute Bash and lived to talk about it — Sarah Sanders, PostHog thumbnail

· 21:00

We let an AI agent execute Bash and lived to talk about it — Sarah Sanders, PostHog

The talk details the architecture and security challenges of building agentic CLI tools, exemplified by PostHog's 'Wizard.' The speaker emphasizes that an agent with command execution capabilities is essentially a 'malware starter pack.' Security must be layered, deterministic, and must account for dangerous inputs originating not only from users but also from the system's own supply chain (the 'Context Mill'). The solution involves implementing a dedicated, deterministic scanner (Warlock) and ensuring that the LLM layer acts only as an 'adviser,' never an enforcer.

Key takeaways

  1. The Danger of Agentic Tools 0:03

    An agent that can run commands is structurally similar to malware, requiring extreme caution. The threat model must account for how 'attacks compose' from multiple, seemingly innocent vulnerabilities.

  2. Context Supply Chain Risk 0:11

    The most dangerous input can come from the system's own supply chain (the Context Mill), such as a seemingly harmless prompt injection payload signed by the development team.

  3. Security Must Be Deterministic 0:15

    For enforcement, security mechanisms must be deterministic and mechanical. The LLM layer should only be an 'adviser' to reduce noise, never the primary enforcer, to prevent failure modes.

Watch on YouTube Full article

Harness Engineering: Building the Production Cage for Powerful Domain Agents — Mike Chambers, AWS thumbnail

· 20:46

Harness Engineering: Building the Production Cage for Powerful Domain Agents — Mike Chambers, AWS

The presentation introduces 'Harness Engineering,' a critical concept for building production-grade AI agents at scale. Mike Chambers distinguishes between agents that are used (e.g., coding assistants) and agents that are built. For built agents, the harness encompasses all non-model components—such as memory, skills, tools, identity, and context management—that must scale independently. The core principle is that scaling these components separately, rather than deploying them in a single container, is essential for handling thousands of users and maintaining reliability.

Key takeaways

  1. Two Types of Agents 4:05

    Agents are categorized into 'agents we use' (productivity tools, coding assistants) and 'agents we build' (production-scale systems). The approach for built agents requires careful architectural planning.

  2. Defining the Harness 7:04

    A harness is defined by subtraction: take an agent and remove the model component; everything left over is the harness. This includes the infrastructure, skills, and tools.

  3. Scaling Built Agents 10:57

    For production agents, the harness must manage complex concerns like loop management, scaling, payments, identity, runtime, context management, and observability. Attempting to containerize everything together is incorrect for high scale.

  4. Avoiding 'Slop Ops' 10:07

    Build engineers must avoid 'slop ops' (clicking around a console to deploy resources). Instead, agents must build infrastructure using Infrastructure as Code (IaC) to maintain ownership and control over cloud deployments.

Watch on YouTube Full article

Tokens Should Have Jobs — Katelyn Lesse & Angela Jiang, Anthropic thumbnail

· 13:21

Tokens Should Have Jobs — Katelyn Lesse & Angela Jiang, Anthropic

The presentation challenges the assumption that all tokens used in agentic systems are fungible. Instead of relying solely on increasing the token budget (brute force), the speakers propose giving tokens specific 'jobs' through advanced strategies. These strategies—Advising, Grading, and Dreaming—allow agents to improve performance and reliability within a fixed budget, particularly when the task requires high precision (e.g., financial analysis). The analysis showed that while increasing the budget improves performance across all methods, specialized strategies significantly reduce the true cost (tokens) required to achieve a perfect, reliable outcome.

Key takeaways

  1. Tokens are not fungible

    The core thesis is that tokens should be assigned specific jobs (e.g., advising, grading, dreaming) rather than being used indiscriminately for simple execution. This allows for more efficient use of computational resources.

  2. Three core agent strategies 3:45

    Strategies include: 1) Advising (splitting an executor from an adviser that provides mid-task guidance); 2) Grading (defining a rubric and using a grader to iterate until a perfect outcome is achieved); and 3) Dreaming (allowing tokens to inspect transcripts and write findings to memory for future runs).

  3. Cost vs. Accuracy in Financial Analysis 11:40

    When evaluating financial tasks (like creating a P&L statement), 80% accuracy is considered useless if 100% accuracy is required. The analysis showed that the baseline 'Execute' strategy required an average of 1.8 million tokens to achieve a perfect answer, while 'Advise' and 'Grade' were significantly more token-efficient.

  4. Optimization depends on the goal

    The choice of strategy depends on the optimization goal: choose 'Advise' for maximum token efficiency, or 'Grade'/'Dream' if maximizing the percentage of perfect, reliable runs is the priority.

Watch on YouTube Full article

Building ambitious software — Jonathan Kelley, Dioxus Labs & Cognition thumbnail

· 19:14

Building ambitious software — Jonathan Kelley, Dioxus Labs & Cognition

Jonathan Kelley discusses building ambitious, cross-platform software using Rust (Dioxus), detailing the challenges of maintaining high quality across a complex stack. He highlights how AI coding agents have dramatically accelerated development—allowing the team to implement features like deeply integrated Kotlin and Swift plugins in weeks—but notes that this shift changes the focus from writing code to maintaining architectural quality. The core message is that while code is now cheap, architectural integrity and quality remain the primary concerns for ambitious projects.

Key takeaways

  1. The Shift in Software Engineering Focus 17:12

    With AI agents handling the low-level development burden (e.g., fighting the borrow checker), the job of a software engineer shifts from writing code to architecting elegant solutions and thinking about system evolution.

  2. Code Quality vs. Code Quantity 17:12

    The speaker asserts that 'code is cheap now, but quality is not.' Maintaining a high quality bar across the entire codebase is critical for developer experience and business stability.

  3. AI Agents as Knowledge Accelerators 13:20

    Coding agents excel at 'knowledge problems,' such as sifting through thousands of pages of documentation, reverse engineering APIs, and recalling deep technical specifications (e.g., CSS specs), accelerating tasks that previously took years of hand-written effort.

Watch on YouTube Full article

One Designer + AI. Hundreds of Deliverables. — Vincent Wendy, AI Engineer thumbnail

· 16:48

One Designer + AI. Hundreds of Deliverables. — Vincent Wendy, AI Engineer

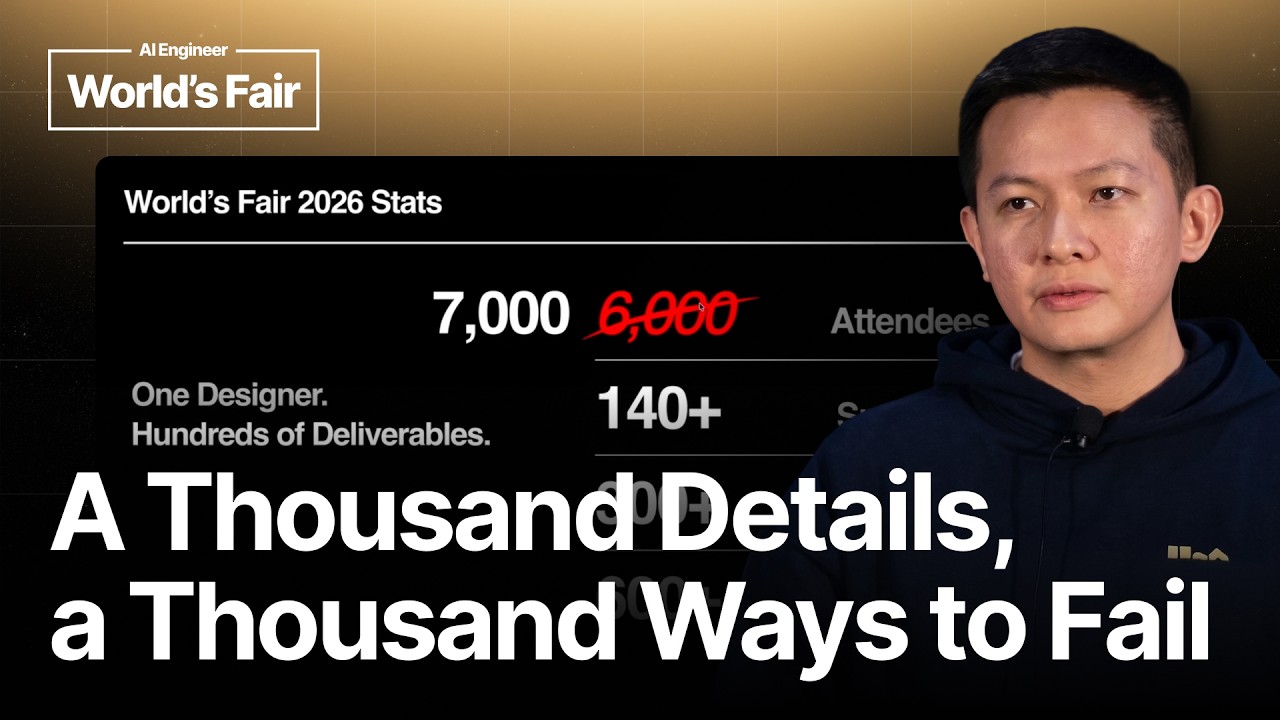
This talk details how one designer managed the massive scale of deliverables (signage, stickers, landing pages, etc.) for a large conference (7,000 attendees, 140+ sponsors, 300+ speakers). The solution involves implementing a structured design system and automating workflows using AI agents (like Devin) and tools like Figma. The core methodology emphasizes shifting from manual, linear processes to highly automated, validated pipelines to solve the 'scale problem.'

Key takeaways

  1. The Five Pillars of Scaling Design 0:04

    To manage massive deliverables, the process must focus on: 1) Building a solid foundation (design system, typography, components); 2) Making designs reusable; 3) Automating workflows; 4) Validating output; and 5) Removing friction. (4:45)

  2. AI Agents for Automation 0:09

    AI agents (e.g., Devin) are used to automate complex tasks, such as generating speaker announcement graphics and trading cards for 300+ speakers, or pulling live schedule data and exporting it as PNGs. (9:16)

  3. Systemic QA and Validation 0:13

    AI can be used for visual quality assurance (QA), such as checking 140+ sponsor logos on a banner for missing assets or detecting visual inconsistencies on merchandise. (13:15)

  4. Thinking as a User 0:14

    The most critical shift is to think like an end-user (attendee) rather than a designer, focusing on handling exceptions and ensuring all elements (wayfinding, schedules) are interconnected. (14:21)

Watch on YouTube Full article

Generative UI... in Python? — Jeremiah Lowin, Prefect thumbnail

· 17:38

Generative UI... in Python? — Jeremiah Lowin, Prefect

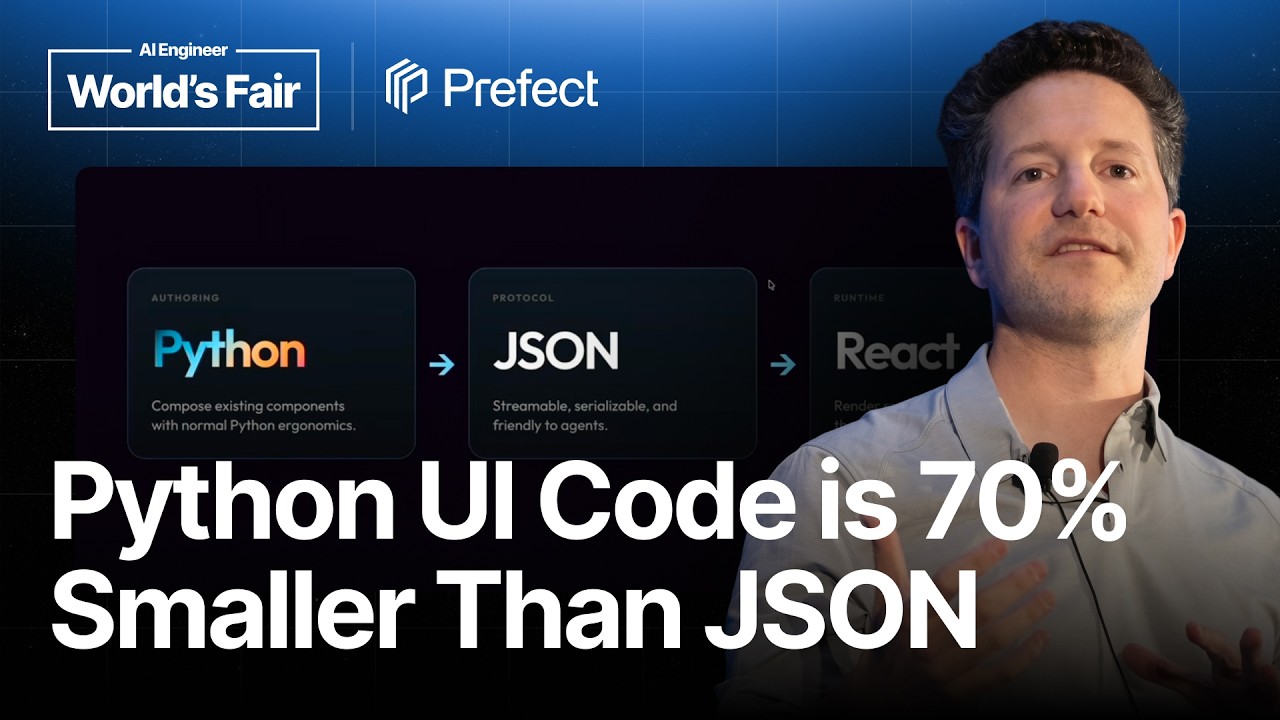
This talk introduces Prefect, a Python DSL designed to solve the challenge of delivering rich, interactive UIs within the MCP (Messaging/Communication Protocol) ecosystem. While MCP apps allow tools to bypass the agent and render full HTML/CSS/JS interfaces, the primary user base (Python engineers in enterprises) needed a way to build these UIs without writing complex frontend code. Prefect achieves this by allowing developers to compose UIs using Python context managers and classes, which are then serialized into a JSON protocol and rendered by a React app. A key optimization is streaming the Python code itself over the wire and executing it in a sandbox, resulting in a 70% reduction in size compared to streaming the JSON representation.

Key takeaways

  1. MCP Apps and Agent Bypass

    MCP apps are an extension of the MCP protocol that allows tool results to bypass the agent and be delivered directly to the user as a full UI (HTML, CSS, JavaScript), enabling rich, interactive experiences.

  2. The Prefect Solution 9:03

    Prefect is a Python DSL that allows developers to compose UIs by nesting components using context managers, avoiding the need to write traditional frontend code.

  3. The Core Pipeline 10:37

    The process involves using a Python DSL to build a declarative representation, which is serialized into a JSON protocol. This JSON is then rendered by a React app hosted as the MCP app.

  4. Efficiency Improvement 16:40

    The system was optimized to stream the Python representation of the UI over the wire and execute it in a sandbox, which was found to be approximately 70% smaller and more efficient than streaming the full JSON protocol.

Watch on YouTube Full article

Training Taste — Thais Castello Branco, Taste Labs thumbnail

· 15:06

Training Taste — Thais Castello Branco, Taste Labs

Taste Labs addresses the problem of 'AI slop'—the homogenization and lack of context in AI-generated content—by proposing a shift in focus from model training to the application layer (inference time). The core methodology involves quantifying subjective domains like design by training 'probes' (small classifiers) on massive datasets (over 2 million websites). This approach allows for the measurement and prediction of slop, which is superior to traditional LLM-as-a-judge methods. Solutions include the 'Brand API' for structuring brand guidelines into machine-readable components and the 'Creativity API' for intentionally generating out-of-distribution content while respecting domain rules.

Key takeaways

  1. Defining Slop and Greatness 4:13

    Slop is defined by three characteristics: repetition, lack of fit (contextual incoherence), and low intent. While defining 'greatness' is subjective, defining slop is easier, as it represents a general sense of soullessness and convergence.

  2. Measuring Slop Quantitatively 5:46

    Taste Labs analyzed over 2 million websites from the past decade to understand design trends. They developed 'probes'—small classifiers—that extract objective features (e.g., contrast, alignment, palette) to predict slop, achieving higher accuracy than LLM-as-a-judge methods.

  3. Focusing on Inference Time 5:46

    The most critical intervention point is the application layer (inference time), where user context and intent are exchanged. Improving quality here is considered equally, if not more, important than improving the base model itself.

Watch on YouTube Full article

Design at the Speed of Adjectives — Paul Bakaus, Renaissance Geek, Inc. thumbnail

· 15:59

Design at the Speed of Adjectives — Paul Bakaus, Renaissance Geek, Inc.

The talk introduces 'Impeccable,' a design skill designed to enhance coding harnesses (like Copilot and Claude Code) by providing a vocabulary to steer AI-generated design. The core thesis is that good design cannot be 'oneshot' or fully automated because it is context-rich, iterative, and requires human decision-making. Instead of automating the process, Impeccable allows users to inject specific adjectives and verbs (e.g., 'bolder,' 'quieter,' 'distill,' 'harden') to guide the AI toward specific design goals, thereby improving the quality of the human-AI collaboration.

Key takeaways

  1. Design is not a one-shot process 9:58

    Good design must be context-rich and iterative. The speaker argues that fully automating design is currently impossible, as human judgment is required to define the emotional territory and audience.

  2. Impeccable facilitates steering, not abdication 13:50

    The tool's purpose is to give users the necessary control to steer the agent using specific design vocabulary. The speaker explicitly rejects the idea of an automatic mode, stating that the point is guiding the process, not letting the AI do all the work.

  3. The traditional design handoff is collapsing 4:16

    The traditional 'waterfall' process (PM $ ightarrow$ Design $ ightarrow$ Engineer) is rapidly breaking down, leading to a blurring of roles where engineers and designers must increasingly work in shared, fluid processes.

Watch on YouTube Full article

The Universal Remote Control for AI — Alex Hancock, Block thumbnail

· 11:01

The Universal Remote Control for AI — Alex Hancock, Block

The talk addresses the lack of a standardized client-to-harness interface in the agentic AI stack. While the Model Context Protocol (MCP) provides a strong standard for agents performing actions (the agent going out), a standard for client software to issue tasks and receive updates is missing, leading to bespoke, non-interoperable systems. The speaker proposes the Agent Client Protocol (ACP), developed by the Zed and JetBrains teams, which standardizes communication using JSON RPC. ACP allows multiple, independent client applications (e.g., editors, terminal clients) to drive the same agent harness, significantly increasing interoperability and enabling the modular placement of the four core components: client, harness, tools, and model, especially when remote transports are implemented.

Key takeaways

  1. The Need for Client Standardization 2:03

    Currently, many agent harnesses expose custom or bespoke interfaces, often requiring a single, dedicated client application. This lack of a universal standard hinders interoperability, comparing it to needing a different browser for every website.

  2. ACP as the Universal Remote Control 5:02

    The Agent Client Protocol (ACP) was developed to allow a single, high-quality client implementation (like an editor) to control any harness, regardless of the underlying system. It is designed to be neutral and extensible.

  3. Modular Agentic Stack Architecture

    By implementing remote transports for ACP, MCP, and model endpoints, the entire agentic stack becomes modular. The client, harness, tools, and model can all be independently placed (e.g., client on a desktop, harness in a container, model in the cloud).

Watch on YouTube Full article

MCP Apps: Give the Model Data, Give the User a UI — Dustin Mihalik, Indeed thumbnail

· 15:34

MCP Apps: Give the Model Data, Give the User a UI — Dustin Mihalik, Indeed

This talk details the architectural challenges of building Model-Composable Platform (MCP) applications for large language models (LLMs) like Claude and ChatGPT. The core thesis is that for a UI widget to function effectively, it must be treated as a data layer, not just a visual display. The speaker outlines three critical rules for developers: all displayed information must be provided as data to the model; the tool description must explicitly state that a UI exists; and, most importantly, data processing must be strictly separated from UI rendering to maintain model context and reasoning capability.

Key takeaways

  1. Data-First Design Principle

    When building MCP apps, developers must focus on defining the data the model needs to process before considering the UI. The UI should be viewed as a side effect or result of the model exploring the underlying data.

  2. Rule 1: Show the Model Everything 5:13

    Any information displayed to the user via the UI must also be provided as structured data to the model. Failing to do so creates a 'black box' that prevents the model from answering follow-up questions about the displayed content.

  3. Rule 2: Declare the UI in the Description 8:26

    The tool description must explicitly state that a UI exists. Otherwise, the model will attempt to narrate the results underneath the widget, leading to redundant and confusing output.

  4. Rule 3: Separate Data Processing from UI Rendering 13:39

    This rule supersedes the others. The architecture must split the job into two distinct tools: one for pure data retrieval (e.g., `search_jobs`) and a separate, dedicated tool for rendering the results (e.g., `render_jobs`). This allows the model to perform complex data exploration without being limited by the UI's single call.

Watch on YouTube Full article

How long can your skills be before your agent forgets what you told it? — Laurie Voss, Arize AI thumbnail

· 22:26

How long can your skills be before your agent forgets what you told it? — Laurie Voss, Arize AI

The capacity of frontier LLMs to follow complex instructions has increased by an estimated tenfold in the last year, moving the instruction ceiling from 200-300 rules to 2,000 to 5,000 rules. This shift fundamentally changes prompt engineering from a 'compression problem' (fitting rules into a small budget) to a 'verification problem' (confirming the model actually obeyed the rules). Developers must now focus on robust output validation (evals) rather than worrying about the length of the skills file.

Key takeaways

  1. Instruction Ceiling Increased by 10x 10:12

    A year ago, models struggled with 200 to 300 instructions. Current frontier models can handle up to 2,000 instructions, with the best models reaching 5,000 rules (6:12).

  2. Failure Mode Shift: From Forgetting to Refusing 20:00

    Models no longer fail by simply forgetting instructions. Failure modes are now diverse: Deepseek V4 Pro forgets; Claude Opus 4.7 refuses at the API level due to safety classifiers; Gemini 3.1 Pro runs out of thinking tokens; and GPT 5.5 writes a partial report and politely states the request is 'stupid' (12:00).

  3. Engineering Focus Shifts to Verification

    The challenge is no longer fitting rules into a small prompt (compression); it is verifying that the model actually followed all instructions, which requires external output checking (an eval) (14:00).

Watch on YouTube Full article

Your agents lack context: Here's how to fix "You're absolutely right!" — Brandon Waselnuk, Unblocked thumbnail

· 14:09

Your agents lack context: Here's how to fix "You're absolutely right!" — Brandon Waselnuk, Unblocked

AI agents require more than just access to information; they need a 'context engine' to achieve true understanding of a company's operations, business logic, and historical decisions. The talk details how agents fail when they lack deep, organizational context, leading to wasted tokens and time. The solution involves building a context engine that ingests data from disparate sources (e.g., ticketing systems, code repos) and provides structured, conflict-resolved context to the model in a token-optimized manner.

Key takeaways

  1. The Context Gap

    AI-generated code must feel like it was written by a long-term team member, which requires deep operational context that current agents lack. This gap compounds as agents scale from simple tab completion to background processes.

  2. Failure Modes of Context 7:00

    Common approaches like the 'curated context trap' (where documentation rots) and the 'MCP plateau' (where agents suffer from satisfaction of search bias) fail because access to information is not the same as understanding it.

  3. The Role of the Context Engine 9:12

    A proper context engine must perform conflict resolution (e.g., resolving conflicting architecture diagrams vs. Slack messages), respect permissions (OAuth/SSO), and deliver context in a token-optimized way.

  4. Efficiency Gains 13:00

    Implementing a context engine can lead to significant efficiency gains, demonstrated by a reduction from 21 million to 10.8 million tokens and a two-hour reduction in wall-clock time for the same task.

Watch on YouTube Full article

500 Skills, Zero Fine-Tuning: LinkedIn's Playbook for AI Agents — Ajay Prakash, LinkedIn thumbnail

· 20:25

500 Skills, Zero Fine-Tuning: LinkedIn's Playbook for AI Agents — Ajay Prakash, LinkedIn

LinkedIn addressed the challenge of coding agents (LLMs) lacking context within massive, proprietary enterprise codebases. The solution involves 'contextual agent playbooks and tools' managed by an internal MCP (Model Context Platform) server. Instead of feeding all tools into the context, the system uses three meta-tools—Search, Get Schema, and Execute—to scale to thousands of tools and playbooks. Playbooks provide self-contained, structured instructions, enabling agents to perform complex, multi-step tasks reliably, and incorporating a self-improving loop where agents update stale documentation.

Key takeaways

  1. Focus on Reliability and Quality from Day One 20:00

    The system's success was predicated on prioritizing quality and reliability over mere productivity, ensuring the infrastructure does not degrade as the organization scales its use of AI agents.

  2. Build Dedicated Infrastructure for Agents 20:10

    In a large enterprise, simply providing the latest AI models and tools is insufficient; a dedicated, robust infrastructure is required to manage and guide agent operations within the internal system context.

Watch on YouTube Full article

Deep dive on LLM Inference at Scale — Harshul Jain, Audible & Tanmay Sah, Independent AI Researcher thumbnail

· 1:28:12

Deep dive on LLM Inference at Scale — Harshul Jain, Audible & Tanmay Sah, Independent AI Researcher

This workshop provides a deep dive into optimizing Large Language Model (LLM) inference at scale. The core challenge is managing the high computational and memory costs associated with LLMs, particularly as context length and concurrent users increase. Solutions are categorized into two areas: model optimizations (e.g., quantization, Grouped Query Attention, Flash Attention) to reduce size/compute, and serving optimizations (e.g., Paged Attention, Continuous Batching, Prefix Caching) to improve throughput and memory efficiency. The session concludes with a comparative analysis of leading inference engines like vLLM and SGLang.

Key takeaways

  1. Inference Cost Drivers 0:05

    The primary pain points are: 1) Memory consumption that grows with context length (due to the KV cache); 2) Time To First Token (TTFT) degradation as input size increases; and 3) Throughput collapse when requests are processed sequentially.

  2. Memory Scaling is Critical 0:10

    The Key-Value (KV) cache memory usage scales significantly: for a Mistral 7B model, the KV size per token is approximately 131 KB. Serving multiple users with long contexts quickly exhausts GPU VRAM (e.g., 80 concurrent users and 4K context can require 42 GB).

  3. Serving Optimizations are Essential 0:24

    To maximize throughput, techniques like Paged Attention (borrowed from OS paging) solve memory fragmentation; Continuous Batching keeps the GPU occupied by processing multiple requests efficiently; and Prefix Caching saves computation when handling similar prompts across different users.

  4. Engine Selection Trade-offs 0:46

    While vLLM and SGLang show no statistical difference on standard workloads, SGLang demonstrated a significant advantage (three to four times better) when handling complex agentic branching workflows.

Watch on YouTube Full article

Why AI Agents Need Million-Token Context — Thomas Wolf & Olive Song, MiniMax thumbnail

· 20:48

Why AI Agents Need Million-Token Context — Thomas Wolf & Olive Song, MiniMax

The discussion details MiniMax M3, a frontier open-source model featuring a functional one-million-token context window and native multimodality (text, image, video). The efficiency of this long context is achieved through the proprietary Minimax Sparse Attention (MSA) architecture. Furthermore, the conversation highlights advanced research practices at MiniMax, including using intern contributions for architectural improvements and training models from the very first step to ensure optimal multimodal performance.

Key takeaways

  1. MiniMax M3 Capabilities 4:53

    M3 is a highly capable open-source model (400B total parameters, 20B activated) that combines coding proficiency, agentic capabilities, and multimodal understanding across text, images, and video. It features a functional one-million-token context window.

  2. Long Context Necessity for Agents 6:30

    The need for extremely long context windows is driven by complex agentic tasks, which require processing multi-round conversations and accumulating tool responses from an entire environment, making shorter contexts insufficient.

  3. Sparse Attention Architecture (MSA) 7:30

    The Minimax Sparse Attention (MSA) architecture is designed to efficiently scale context length. It uses an index branch to select relevant context blocks, followed by a sparse attention branch for calculation, allowing scalability in both length and model size.

  4. Native Multimodality Training 17:25

    MiniMax trains M3 from the very first step as a multimodal model (native multimodality), rather than adding vision capabilities after text pre-training. This approach prevents performance degradation in text understanding and ensures better scalability.

  5. Internal Research Culture 13:49

    MiniMax utilizes an open research culture where external community members (including interns) can propose projects, find model weaknesses through evaluations, and contribute code/improvements that are integrated into final training runs.

Watch on YouTube Full article

From coding to Knowledge work agents — Karan Vaidya, Composio thumbnail

· 20:42

From coding to Knowledge work agents — Karan Vaidya, Composio

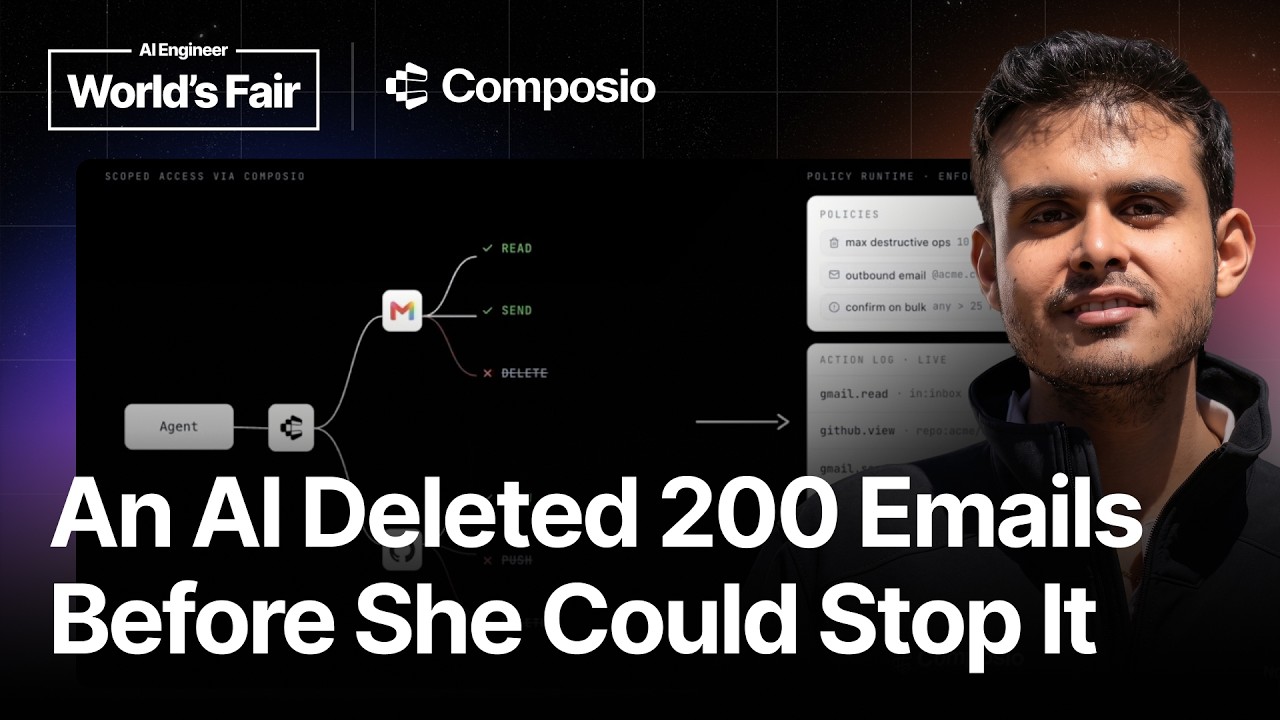
The presentation argues that while autonomous AI agents have excelled in software engineering due to inherent infrastructure support (e.g., Git history, CI/CD), knowledge work agents are currently limited because they lack comparable foundational systems. The speaker identifies six critical primitives—Centralization, History, Context, Verification, Governance, and Reversibility—that must be built into the enterprise layer to enable reliable AI agents for fields like sales and support.

Key takeaways

  1. The Infrastructure Gap

    Coding agents benefit from infrastructure (repo, commit history, tests, CI/CD) that was designed for automation. Knowledge work lacks this surrounding system, causing agents to operate 'blind' when applied outside of code bases.

  2. Centralization is Key 3:55

    Knowledge work data is typically scattered across multiple platforms (e.g., Salesforce, Notion, Gmail, Slack). Agents require a single source of truth—a centralized layer—to pull all necessary threads and connections before they can operate effectively.

  3. The Six Missing Primitives

    To bridge the gap between coding agents and knowledge work agents, six primitives must be built: Centralization (single data source), History (record of past actions), Context (organizational map + style guide), Verification (pre-action checks), Governance (deterministic boundaries/walls), and Reversibility (undo capability).

  4. Failure is Permanent in Knowledge Work 20:00

    Unlike code, where changes can be reverted or walked back, many knowledge work actions (sent emails, wire transfers) are irreversible. This shifts the risk profile, requiring agents to check their work *before* executing any destructive action.

Watch on YouTube Full article

Your company brain will leak secrets: how we stopped it for big banks — Tanmai Gopal, PromptQL thumbnail

· 26:25

Your company brain will leak secrets: how we stopped it for big banks — Tanmai Gopal, PromptQL

The talk addresses the critical security challenge of 'Company Brains'—shared knowledge systems that risk leaking sensitive corporate secrets. The speaker proposes a secure architectural model centered on using a single companywide wiki (linked markdown files) for context storage. Key security measures include scoping read/write access per file, preventing agents from auto-writing memory, and ensuring every change is attributed to a human owner. For multi-user operations, credentials must be injected at the HTTP and SQL layers rather than stored in a sandbox.

Key takeaways

  1. Healthy Company Brain Growth 5:41

    A healthy company brain should show a continuously increasing trend in daily updates, indicating that users are not only consuming knowledge but also teaching the system new skills (e.g., querying data $\rightarrow$ interpreting results $\rightarrow$ taking action).

  2. Secure Knowledge Contribution Model 20:33

    To prevent leakage, context must be stored in a single shared wiki (linked markdown files), and the agent should only *suggest* changes with defined scopes; a human user must accept or reject the change to assign ownership.

  3. Multi-User Security Architecture 25:00

    For collaborative tasks (e.g., incident management), credentials should never be stored in a sandbox. Instead, they must be injected per user at the HTTP and SQL layers to allow the AI agent to behave as the authenticated human.

Watch on YouTube Full article