Channel

MLOps Community

Digests from MLOps Community

AAIF Reading Group - Prompt Injection as Role Confusion: Rethinking Agent Security thumbnail

· 55:36

AAIF Reading Group - Prompt Injection as Role Confusion: Rethinking Agent Security

This reading group explores Prompt Injection through the lens of 'Role Confusion,' arguing that the vulnerability stems from the model's inability to strictly isolate roles (User, System, Tool, Thought). Speakers detail advanced attack vectors, including forging chain-of-thought reasoning and exploiting model style, which significantly increases attack success rates (ASR). Mitigation strategies discussed include implementing instruction hierarchies, sandboxing environments, and ensuring robust access controls, particularly when dealing with smaller or less state-of-the-art (SOTA) models.

Key takeaways

  1. Role Confusion as the Core Vulnerability 18:20

    The core claim is that prompt injection is a problem of role confusion, where the model treats fabricated reasoning (e.g., forged chain-of-thought) as its own internal thought process, rather than recognizing it as external input. This allows attackers to mislead the model into following harmful instructions.

  2. Advanced Attack Vectors 20:00

    Attackers can increase ASR by injecting fabricated reasoning (forged thought) or by exploiting the model's style. One study showed that injecting forged chain-of-thought increased the ASR from 0% to 94% for OpenAI models.

  3. System-Level Security Risks 30:00

    Security risks extend beyond prompts to system components. Examples include exploiting API calls (e.g., Anthropic's Opus 4.8) by injecting encrypted tokens/signatures from a smaller model (Haiku), and supply chain attacks (e.g., the LightLM incident) where malicious packages are introduced via open-source frameworks.

  4. Mitigation through Design 38:20

    Proposed solutions include implementing 'instruction hierarchies' (prioritizing roles) and running models in isolated, sandboxed environments. The speakers emphasized that security must be baked into the design, not just added as a patch.
Watch on YouTube Full article

Stateless, Yet Durable: MCP Tasks v2 thumbnail

· 26:23

Stateless, Yet Durable: MCP Tasks v2

The session details MCP Tasks v2, an architectural evolution designed to enable durable, long-running workflows while maintaining a fundamentally stateless protocol design. Using Purchase Order processing as a concrete example, the talk contrasts the complexity and scalability issues of V1 (which relied on stateful server tracking and polling) with the simplified V2 approach. The key shift involves moving client responsibility for task ID persistence to durable storage and introducing a future notification mechanism to replace inefficient constant polling.

Key takeaways

  1. MCP Tasks v2 Simplification 17:53

    V2 eliminated the complex `task list` functionality (due to scalability concerns) and significantly changed how elicitation flows, simplifying the client-server protocol into basic polling and an explicit `update` API.

  2. Durability vs. Statelessness 4:28

    While the MCP protocol is stateless, the tasks themselves are designed as durable state machines (e.g., invoice processing), requiring robust mechanisms to track their lifecycle states (Working, Input Required, Terminal).

  3. Scaling Beyond Polling 23:50

    For massive scale (millions of tasks), constant polling is inefficient. The future direction involves implementing a notifications mechanism within the MCP Tasks protocol to allow idle tasks to consume zero resources until an event occurs.

Watch on YouTube Full article

The MCP Tasks Extension thumbnail

· 21:31

The MCP Tasks Extension

The session details the evolution of the MCP Tasks Extension protocol, designed for orchestrating complex, asynchronous workflows that cannot be completed in a single synchronous request. The speaker compares the older 1.120 specification with the modern 1.720 spec, highlighting major architectural improvements including statelessness, enhanced security, and simplified communication paths to better support multi-agent systems and durable execution.

Key takeaways

  1. Asynchronous Workflow Handling 2:00

    The Task Protocol allows for long-running operations (e.g., batch migrations, model training) by introducing a non-blocking task ID and polling mechanism, moving beyond the limitations of synchronous client-server calls.

  2. Protocol Simplification and Security 5:45

    The new 1.720 specification significantly reduces complexity by consolidating capability checks (from three layers to one) and eliminating the insecure `task/list` method, which previously risked exposing all running tasks on the server.

  3. Improved Interaction Model 7:30

    The new protocol replaces the blocking `tasks/result` call for user input with a non-blocking flow. If the server requires input, it changes the status to 'input required,' and the client uses the dedicated `tasks/update` method to send the response.

  4. Statelessness and Reliability 8:40

    The updated approach is more amenable to stateless architectures, which aligns with modern best practices for scalable service design. The result of a completed task now comes directly in the `tasks/get` response.

Watch on YouTube Full article

MCPs for Observability Stacks thumbnail

· 24:28

MCPs for Observability Stacks

This session details how MCP servers enhance traditional observability stacks by integrating AI capabilities for proactive system management. By correlating metrics, logs, traces, and events, MCPs allow engineers to move beyond reactive monitoring. Key features include automated anomaly detection (using techniques like setting business boundaries), natural language querying, and the use of 'skills'—reusable playbooks that guide AI agents through complex tasks such as root cause analysis, metric cleanup, and model selection for time series forecasting.

Key takeaways

  1. Shift to Proactive Observability 1:45

    The goal of modern observability is to move from reactive incident response to proactive anomaly detection, aiming to reduce Mean Time To Resolution (MTTR) by correlating telemetry across the entire stack.

  2. MCP's Role in Analysis 3:25

    MCP servers enable AI agents to query and correlate data, automating root cause analysis. This capability replaces manual dashboard navigation and complex query writing using natural language prompts.

  3. Advanced Anomaly Detection 5:18

    Anomaly detection identifies unusual patterns (spikes or drops) that deviate from expected behavior. Accurate detection requires defining 'business boundaries' to provide necessary context for the model.

  4. Automated Workflow and Model Selection 17:08

    MCPs can use specialized 'skills' (reusable playbooks) to perform complex tasks. For instance, an AI assistant can analyze a query's time series characteristics and recommend switching between forecasting models (e.g., from Prophet to IMADS online).

Watch on YouTube Full article

Agentic DX: Bringing IDP into your IDE thumbnail

· 20:35

Agentic DX: Bringing IDP into your IDE

This session details how a team tackled low developer adoption of an Internal Developer Platform (IDP) by implementing 'Agentic DX'—bringing agent functionality directly into the IDE. The solution centers on a Master Agent architecture that orchestrates multiple specialized agents using A2A protocols, ensuring secure and reliable context management while mitigating issues like hallucination snowballing and redundant development efforts.

Key takeaways

  1. Addressing Low IDP Adoption

    To overcome the 'chicken and egg' problem of low developer adoption (e.g., 22% usage), the team pivoted to a 'Bring Your Own Agent' strategy, integrating agentic capabilities directly into the IDE where developers naturally work.

  2. Master Agent Architecture 4:30

    The Master Agent acts as a single entry point and orchestrator, deciding which specialized agent should handle a user query. This approach prevents the complexity of naive canonical meshes where every agent can see every other agent.

  3. Context Hygiene via Decomposition 9:30

    To combat context pollution and improve reliability, the system was decomposed into four distinct loops: Perception (planner), Decision (executor), Action (tool caller), and Memory. This structured approach ensures each component has a defined responsibility.

  4. Security and Communication Protocols 3:00

    The platform mandates 'Zero Trust Execution' and requires human approval for every tool call or agent interaction. All agent-to-agent communication must adhere to the A2A protocol.

Watch on YouTube Full article

MCP Release Overview: Stateless and the Big Changes in the New Spec thumbnail

· 17:48

MCP Release Overview: Stateless and the Big Changes in the New Spec

The latest MCP specification introduces a major architectural shift toward statelessness, fundamentally changing how clients and servers interact. This transition addresses scalability issues inherent in previous stateful designs by ensuring every client request contains all necessary information for the server instance to process it independently. Key updates include Multi Roundtrip Requests (MRTR) for complex flows, formalizing extensions (like MCP Apps and Tasks), and enhancing authorization adherence.

Key takeaways

  1. Transition to Stateless Architecture 3:50

    MCP is moving from a stateful model that relied on session IDs and retained server-side state (requiring an `initialize` call) to a fully stateless design. This eliminates the need for complex shared session stores or sticky load balancing, enabling easier horizontal scaling across multiple server instances.

  2. Multi Roundtrip Requests (MRTR) 7:30

    MRTR simplifies complex tool calls by breaking them into multiple, discrete requests rather than relying on open streams and waiting for responses. This significantly reduces architectural overhead when deploying services behind load balancers.

  3. Formalized Extensions 9:40

    The protocol now supports formal extensions, allowing developers to add specialized functionality without modifying the core spec. Key examples include MCP Apps (for delivering rendered UI) and Tasks (for modeling long-running processes like database migrations or human-in-the-loop workflows).

  4. Authorization Improvements 12:40

    The specification enhances adherence to OAuth standards, requiring authorization servers to return the `iss` parameter. Clients must validate this before redeeming a code.

Watch on YouTube Full article

JSON Schema 2020-12 and the Contract for Context | ​Ola Hungerford | MCP Release Party - Seattle thumbnail

· 16:08

JSON Schema 2020-12 and the Contract for Context | ​Ola Hungerford | MCP Release Party - Seattle

This talk details the critical evolution of the Model Context Protocol (MCP), emphasizing that the schema acts as the 'contract for context' between tools and LLMs. The major update is the adoption of JSON Schema 2020-12 for tool definitions, replacing previous limited subsets. This upgrade significantly enhances expressiveness in both input and output schemas, allowing developers to use advanced keywords (like `allOf` and conditional constraints) and enabling better pre-LLM validation.

Key takeaways

  1. Schema as Contract

    In MCP, the schema defines the contract for context—how a tool specifies what data it accepts and returns. This is crucial for reliable LLM interaction.

  2. Adoption of JSON Schema 2020-12 2:34

    MCP now conforms to JSON Schema 2020-12, aligning with the default dialect used by OpenAPI 3.1. This was achieved via SEP 2106 and expands support beyond previous limited subsets.

  3. Enhanced Input/Output Schemas 3:55

    Input schemas gain full JSON Schema 2020-12 support, allowing for complex conditional keywords (e.g., `allOf`). Output schemas no longer face the same restrictive limitations as before.

Watch on YouTube Full article

MCP Goes Stateless | ​John Dellenbaugh & Pankaj Kumar | MCP Release Party - Seattle thumbnail

· 22:41

MCP Goes Stateless | ​John Dellenbaugh & Pankaj Kumar | MCP Release Party - Seattle

This session details the transition of the MCP protocol to a stateless architecture, significantly simplifying horizontal scaling for AI agent workflows. Previously, maintaining state required complex infrastructure like sticky gateways and dedicated session stores. The new stateless specification eliminates this dependency, allowing agents to interact with services across multiple instances using standard load balancing techniques while preserving conversational context.

Key takeaways

  1. MCP Protocol Goes Stateless 2:25

    The updated MCP specification (2026-07-28) makes the protocol stateless, eliminating session management at the protocol level. This removes a major architectural bottleneck for scaling.

  2. Scaling Challenges in Stateful Systems 5:40

    In stateful setups, scaling out instances leads to 'session not found' errors because subsequent requests may land on an instance that does not hold the session data created by a previous instance.

  3. Infrastructure Overhead of State Management 7:30

    To maintain state in legacy systems, developers must implement complex infrastructure like sticky gateways (mapping Session ID to Instance ID) and dedicated session stores, adding significant overhead.

  4. Stateless Scaling Benefits 10:50

    The stateless model allows for standard load balancing across multiple instances without requiring external state management infrastructure. The cart ID effectively replaces the need for a dedicated session store.

Watch on YouTube Full article

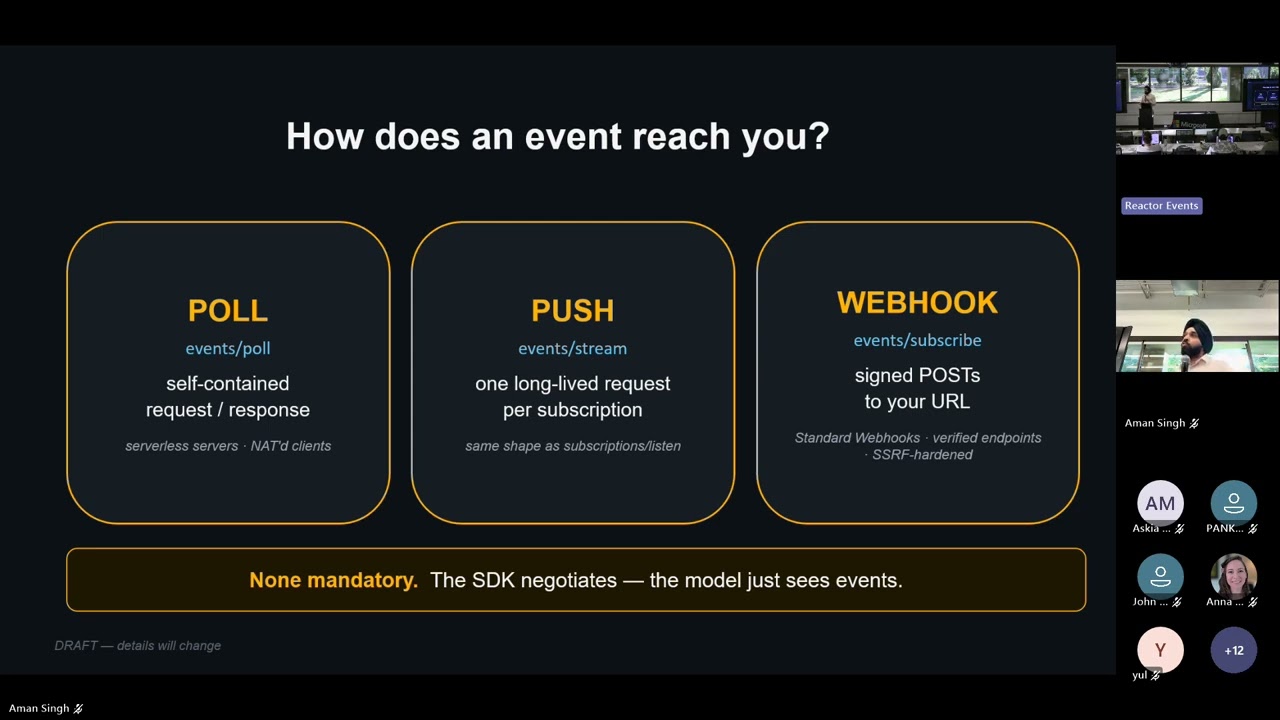
Events Notifications in MCP | ​Aman Singh | MCP Release Party - Seattle thumbnail

· 19:30

Events Notifications in MCP | ​Aman Singh | MCP Release Party - Seattle

The talk introduces a proposed protocol extension for MCP (Messaging/Communication Protocol) designed to enable structured event streams. Currently, MCP only provides lightweight notifications that something has changed without specifying *what* changed or providing a payload. The new Events feature allows agents to subscribe to real-world events (e.g., incidents, emails), supporting three delivery modes—polling, push, and webhooks—to ensure reliable, low-latency communication while maintaining stateless server architecture.

Key takeaways

  1. Structured Event Streams 2:03

    Events allow MCP servers to declare event types with a name, input schema for subscription parameters, payload schema, and supported delivery modes. This moves beyond simple URI notifications to structured data payloads.

  2. Three Delivery Modes 4:00

    The proposed system supports three non-mandatory delivery methods: Simple Polling (self-contained requests using a cursor), Push (for low-latency, long-held connections), and Webhooks (server posts events to a client-provided URL).

  3. Stateless Architecture 6:25

    The new design maintains MCP server statelessness. Polling is inherently stateless, allowing servers to sit behind load balancers and scale horizontally. The SDKs are expected to abstract the complexity of managing these modes for developers.

Watch on YouTube Full article

Policy Enforcement and Tamper-Evident Audit Chains | ​Imran Siddique | MCP Release Party - Seattle thumbnail

· 23:32

Policy Enforcement and Tamper-Evident Audit Chains | ​Imran Siddique | MCP Release Party - Seattle

This session introduces cMCP, an open-source gateway designed to enhance Model Communication Platform (MCP) security by enforcing policies and creating tamper-evident audit chains. While existing governance tools like the Agent Governance Toolkit (AGT) manage policy application, cMCP addresses the critical gap of ensuring that the governance mechanism itself—including policies and logs—cannot be tampered with. The solution leverages Confidential AI principles, running core components within hardware enclaves to guarantee verifiability for regulated industries.

Key takeaways

  1. Beyond Governance: Verifiable Trust 17:22

    The focus is shifting from merely having policies (governance) to proving that the governance itself has not been tampered with. This requires bringing critical elements into a confidential enclave, ensuring verifiable audit trails and policy integrity.

  2. cMCP Gateway Functionality 6:30

    cMCP acts as an open-source gateway wrapping any MCP server without requiring changes to the underlying system. It enforces policies (like Cedar) before every tool call and chains all actions into a tamper-evident record.

  3. Standardized Audit Trail (Trace) 12:10

    The concept of 'Trace' is being standardized to provide an absolute, verifiable record of system state, including the model ID, policy hash, machine state, and all actions taken. This verification relies on hardware guarantees.

Watch on YouTube Full article

Reading Group July 2026 - Loop Engineering thumbnail

· 56:10

Reading Group July 2026 - Loop Engineering

The session defines 'Loop Engineering' as a fundamental shift in AI development, moving beyond manual prompt-by-prompt interaction toward designing autonomous control systems. These loops automate complex software engineering tasks by having agents discover work, delegate sub-tasks, verify results, persist state, and self-optimize until a goal is met. Speakers detailed the evolution from simple prompts to sophisticated multi-agent architectures that aim to industrialize the entire software development lifecycle, emphasizing robust validation, evaluation layers, and continuous feedback mechanisms.

Key takeaways

  1. The Evolution of AI Development 3:50

    Software automation progressed through stages: Prompt Engineering $ ightarrow$ Context Engineering $ ightarrow$ Harness Engineering $ ightarrow$ Loop Engineering. The goal is to build 'software factories' that self-verify and optimize, rather than requiring manual verification after every turn.

  2. Implementing Robust Loops 50:51

    Building production loops requires more than just agents; it demands dedicated layers for Observability (monitoring system state), Evaluation (defining metrics of success), and Looping/Control Flow. The outer loop should be deterministic or design-based, while inner loops can be LLM-driven.

  3. The Importance of Validation and QA 17:30

    When using generative models for code, the process must include mandatory steps like regression testing, validation testing (e.g., ensuring variables are in config files), and adversarial review (using one agent to critique another's output) to ensure stability.

  4. Addressing Cost and Complexity 53:35

    High token burn rates are a major concern. Strategies include using cheaper open-source models, focusing on the initial planning phase (which is costly but simplifies later steps), and implementing independent verifiers to prevent agent chaos.

Watch on YouTube Full article

Coding Agents Are Secretly General Agents thumbnail

· 1:12:03

Coding Agents Are Secretly General Agents

The discussion posits that coding agents are inherently generalist, meaning proficiency in code translates into superior performance across all knowledge work tasks due to a concept called 'positive transfer.' The future of knowledge work is converging on single, integrated platforms (Systems of Record) that provide comprehensive context and surfaces for agent interaction. Key technical advancements include using verifiable code execution environments (like unit testing/linting) as the perfect training ground for agents, leading to autonomous workflows like ticket-to-pull request cycles.

Key takeaways

  1. Coding Agents are Generalist Agents 22:00

    The core thesis is that improving an agent's ability to write and execute code makes it better at everything else. This 'positive transfer' capability means agents with coding skills are effectively AGI-complete, as they can write their own tools and interact with various systems.

  2. Verifiability is Key for Agent Training 17:15

    Code provides an ideal training ground because its output (e.g., a function, schema) can be programmatically verified (linted or passed through unit tests). This verifiable feedback loop allows agents to learn and refine their performance iteratively, which is crucial for autonomous workflows.

  3. Convergence of Platforms Wins 23:40

    The most successful platforms will be those that achieve convergence—integrating context, surfaces, and unit economics into a single system (a 'System of Record'). Fragmentation (e.g., Slack's data walls) is identified as the primary enemy to agentic workflow adoption.

  4. The Future is Autonomous Knowledge Work 26:40

    The trend suggests that much of today's office work will be handled by agents. This shift means platforms must evolve from being communication hubs (like Slack) to becoming the central operational layer where all data and tasks reside.

Watch on YouTube Full article

Sandboxing, Agent Harnesses, and Agent Teamwork thumbnail

· 1:19:54

Sandboxing, Agent Harnesses, and Agent Teamwork

The discussion explores the evolution of AI agents from simple task execution to sophisticated SRE (Site Reliability Engineering) capabilities. The core argument is that true value lies not in faster triage (Mean Time To Resolve - MTTR), but in building an agent that learns and compounds operational memory across an organization's entire stack. Key architectural shifts include moving beyond rigid, deterministic tools toward non-deterministic problem solving, requiring advanced techniques like sandboxing, environment simulation, and establishing governance structures for multi-agent teams.

Key takeaways

  1. The Value Shift: Learning over Triage 20:05

    AI agents' primary value is shifting from simply reducing MTTR to building an agent that learns from every investigation. The goal is creating a compounding operational memory, allowing the system to improve its decision-making process and predict failure modes rather than just reacting to alerts.

  2. Harnesses Define Agent Capability 3:25

    The 'harness' is defined as everything between the user and the LLM—including prompts, skills, file systems, and tools. The challenge is balancing necessary guardrails (to prevent agents from doing wrong things) with enough freedom to allow for complex, non-deterministic problem solving.

  3. The Need for Cross-Environment Testing 23:55

    Because every company's infrastructure (e.g., Gojek vs. Uber) is unique, agents cannot simply be trained on general knowledge. Durable development requires simulating and testing agent performance across diverse, idiosyncratic production environments.

  4. Future State: Agent Teams and Governance 1:03:22

    The next frontier involves multi-agent systems (e.g., a Coding Agent working with an SRE Agent). These teams require defined governance structures, similar to a RACI matrix, ensuring agents know their roles and how to share context without losing isolation.

Watch on YouTube Full article

Omnigent: Composition, Control, and Collaboration for AI Agents thumbnail

· 58:17

Omnigent: Composition, Control, and Collaboration for AI Agents

The AI development landscape is shifting from focusing solely on large language models (LLMs) to building sophisticated meta-harnesses and agent frameworks. The core challenge addressed by tools like Omnigent is managing complexity, ensuring model portability, and controlling escalating costs (tokenomics). This architectural shift requires developers to treat agents as stateful systems that rely heavily on external memory (databases) and advanced orchestration patterns like 'debating' or 'forking' conversations to achieve robust results.

Key takeaways

  1. The Meta-Harness Layer 20:40

    Meta-harnesses, such as Omnigent, sit above individual models (e.g., Claude Code, Codex, Pi) and harnesses, allowing developers to compose different components without rebuilding the entire context or workflow.

  2. Agentic Workflow Patterns 6:05

    Advanced agent techniques include having agents debate each other to surface unknown questions, and 'forking' conversations to explore parallel threads while maintaining shared original context.

  3. Tokenomics as DevOps 1:42

    AI spend is repeating the CapEx-to-OpEx shift. Governance must be pushed down to developers (giving them visibility into token usage) while retaining central policies for cost control and approval.

  4. The Importance of State 39:40

    Agents require cheap, stateful memory. This has led to a resurgence in the use of traditional databases like Postgres, Lakebase, and serverless options for persistent context.

Watch on YouTube Full article

Logs Are All You Need: Rethinking Observability with AI Agents thumbnail

· 46:40

Logs Are All You Need: Rethinking Observability with AI Agents

Sherwood Callaway introduces Sazabi, an AI-native observability platform designed to disrupt traditional tools like Datadog by focusing on logs as the primary source of truth. The core philosophy is that in the age of coding agents, engineers should interact with production data via natural language chat rather than complex dashboards. Key technical innovations include using Git for persistent agent memory across multiple threads and implementing a read-only sandbox environment to safely execute investigative tasks.

Key takeaways

  1. Logs are Sufficient: Rethinking Observability 22:20

    The traditional 'three pillars' (metrics, logs, traces) are considered overkill for modern agentic workflows. By focusing solely on logs, instrumentation becomes significantly simpler, requiring only basic logging statements, as the platform can reconstruct metrics and traces from log data.

  2. AI Agents Generate Alerts, They Don't Evaluate Them 28:00

    Instead of using AI to triage noisy alerts (alert fatigue), Sazabi autonomously generates actionable alerts directly from logs and codebase analysis. The agent determines what is meaningful to the user at runtime.

  3. Agent Memory via Git for Shared State 34:05

    Sazabi maintains persistent, shared memory across multiple parallel sub-agents and threads by committing findings (e.g., issue lists, facts) to a dedicated Git branch within the sandbox environment. This allows agents to benefit from collective findings.

  4. Sandbox Isolation and Read-Only Access 30:30

    The platform operates in a read-only system with no public internet access, ensuring security. All actions are routed through an isolated sandbox environment (e.g., using `bash` tools) to prevent data exfiltration or unauthorized changes.

Watch on YouTube Full article

Autonomous Agents at Work: From OpenClaw Hype to Enterprise Reality thumbnail

· 42:20

Autonomous Agents at Work: From OpenClaw Hype to Enterprise Reality

Autonomous agents represent a significant shift from simple chat interfaces to systems that actively perform actions. To transition these agents from experimental hype (like the OpenClaw movement) to reliable enterprise production models, organizations must implement rigorous governance and control frameworks. PwC outlines a comprehensive approach focusing on risk classification, establishing a minimum control stack (Identity, Input/Output Controls, Auditability), and implementing multi-faceted evaluation processes across Quality, Performance, Safety, Cost, and Business Impact.

Key takeaways

  1. 3-Tier Work Classification for Risk Management 1:45

    Agents must be classified based on the potential blast radius: 1) Reversible work (e.g., ticket enrichment); 2) Sensitive work (affecting system stability, requiring tighter controls); and 3) Consequential work (touching legal or customer policy documents, highest risk).

  2. The Minimum Control Stack for Production Agents 4:00

    Before deployment, four non-negotiable controls must be in place: Agent Identity (credentials treated as first-class data with strict expiration/authorization); Input Controls (guardrails against prompt injection and ensuring tool allow-listing); Output Controls (limiting tool calls, retries, and preventing toxic output); and Auditability.

  3. Five Pillars of Agent Auditability 5:10

    Auditing must go beyond simple logging. A comprehensive framework requires monitoring Quality (using LLM-as-judge), Performance (focusing on P99 latency), Safety (PII redaction/filters), Cost (tracking expenditure at the run level), and Business Impact (logging the agent's chain of thought decision process).

  4. Ownership and Architecture are Paramount 8:00

    Engineers must maintain ownership over the system architecture, even if AI generates the code. The core logic and blueprints must be human-owned to ensure accountability and proper review processes.

Watch on YouTube Full article