Channel

Google Developers

Digests from Google Developers

Manage your agents while you’re on the move with the Antigravity Remote Control thumbnail

· 0:48

Manage your agents while you’re on the move with the Antigravity Remote Control

Antigravity Remote Control allows users to manage and monitor long-running agents across multiple machines from a single, unified interface (browser or app). This capability ensures that local context is retained, eliminating the need to recreate or sync the build environment when working on different devices.

Key takeaways

  1. Centralized Agent Management

    Users can control and monitor all running agents from one place, providing a unified view for managing development sessions.

  2. Context Persistence

    All local context is retained, meaning the build environment does not need to be recreated or synced when switching devices.

  3. Workflow Integration

    The system supports push notifications for review changes (diffs) and allows users to answer questions and maintain progress from any location.
Watch on YouTube Full article

Celebrating one billion Gemma downloads thumbnail

· 0:56

Celebrating one billion Gemma downloads

Google Developers celebrated reaching one billion downloads for the Gemma model family. The discussion highlighted significant advancements in multimodal AI capabilities, specifically noting that Gemma 4 supports video and audio understanding. For developers, key takeaways include utilizing Unsloth Desktop—a local coding agent—for development and fine-tuning, and keeping an eye on future platforms like GenieX, which is designed to integrate highly requested models like Gemma.

Key takeaways

  1. Gemma's Multimodal Capabilities

    The latest model in the family, Gemma 4, represents a major breakthrough by supporting both video and audio understanding.

  2. Local Development Tools

    Unsloth Desktop was launched as a local coding agent, allowing developers to run models and perform tasks entirely offline. Users can also fine-tune models locally.

  3. Future Platform Roadmap

    A platform called GenieX is under development, positioning Gemma as one of the most requested models for future enterprise integration. The team expressed excitement for upcoming versions, including Gemma 5 and Gemma 6.

Watch on YouTube Full article

Agentic approaches to processing long videos with Gemini thumbnail

· 1:31

Agentic approaches to processing long videos with Gemini

Agentic video understanding with Gemini allows developers to process long-form videos without submitting the entire content, which could exceed 100,000 tokens. Instead, the model uses an agentic loop (thinking, acting, observing) and specialized tools—such as `get transcript`, `get frames`, and audio extraction—to iteratively zoom in on relevant information, significantly reducing token usage and improving processing performance.

Key takeaways

  1. Token Efficiency

    By using an agentic approach, the model avoids submitting the entire video content (which can exceed 100,000 tokens), leading to massive token reductions and lower latency.

  2. Agentic Workflow

    The process involves the model first determining necessary tools (e.g., `get transcripts`, `get frames`) before executing a traditional agentic loop of thinking, acting, observing, and iterating until the answer is derived.

  3. Targeted Analysis

    This technique improves performance by allowing the model to 'zoom in' on specific functions or segments within the video that are most relevant to the query, rather than processing all data equally.

Watch on YouTube Full article

Agentic video understanding in Gemini thumbnail

· 3:19

Agentic video understanding in Gemini

Agentic Video Understanding in Gemini addresses the high token cost and inefficiency of processing entire long videos by utilizing an agentic loop architecture. Instead of feeding the model the full video data (which can exceed 100,000 tokens), the system allows the model to intelligently use specialized tools—such as `get transcript` or `get frames`—to localize its analysis. This approach significantly reduces token consumption while improving accuracy by focusing attention only on relevant segments of the video.

Key takeaways

  1. Inefficiency of Naive Video Processing

    Processing an entire long video can generate over 100,000 tokens, making it computationally expensive and inefficient if the required information is localized to a small segment (e.g., frame 900).

  2. Agentic Approach for Efficiency

    The new pipeline does not require the entire video; instead, the model references the video and uses tools to extract only necessary data pieces (like transcripts or specific frames) before proceeding.

  3. Agentic Loop Mechanism 2:00

    Analysis follows a traditional agentic loop: Thinking $\rightarrow$ Acting (using tools) $\rightarrow$ Observing (receiving observations like extracted frames), and looping until the final answer is derived. This process reduces token cost and enhances performance by zooming in on critical video functions.

Watch on YouTube Full article

Koray Kavukcuoglu on frontier models, coding agents, and building AGI thumbnail

· 26:47

Koray Kavukcuoglu on frontier models, coding agents, and building AGI

Google DeepMind SVP Koray Kavukcuoglu discusses the ambitious journey toward Artificial General Intelligence (AGI), emphasizing that success relies on moving models from simple coding capabilities to full software engineering and agentic workflows. The discussion highlights the continuous progress of the Gemini model family (e.g., 3.7, Flash) through parallel research tracks and stresses that real-world user interaction is critical for guiding development toward AGI.

Key takeaways

  1. AGI lacks a definitive test or benchmark 14:53

    There is no single standardized test to determine if an AI has reached AGI; progress is measured by the overall journey and capability build-up, not a sudden threshold. (08:53)

  2. The focus shifted from coding to software engineering 2:48

    A major breakthrough in model development was understanding that true intelligence requires more than just writing code; it involves mastering the full scope of 'software engineering,' including working with tools and functions, effectively turning the model into an agent. (02:48)

  3. Gemini 4 is positioned as a major research milestone 3:17

    The team announced Gemini 4 as the most ambitious pre-training run to date, representing a significant step in combining multiple learnings and architectural improvements into one model. (03:17)

  4. User interaction is the guide for AGI development 11:59

    The path to building AGI depends heavily on continuous user interaction and feedback, whether users are performing daily tasks (e.g., emails) or conducting advanced scientific research. This usage spectrum guides problem-solving efforts. (11:39)

Watch on YouTube Full article

Build voice-first apps with Gemini 3.5 Transcribe thumbnail

· 1:44

Build voice-first apps with Gemini 3.5 Transcribe

Google launched Gemini 3.5 Transcribe, an advanced LLM-based model designed for building voice-first applications. This model is available via both the Interactions API and the Live API, offering fast, contextually accurate transcription of multi-speaker recordings. Key strengths include superior recognition of structured data like email addresses and phone numbers, as well as robust support for over 70 different languages.

Key takeaways

  1. Model Availability

    Gemini 3.5 Transcribe is available on both the Interactions API and the Live API.

  2. Structured Data Recognition

    The LLM-based model excels at transcribing alphanumerics, such as email addresses (e.g., thorwebdev@google.com) and recognizing correct US phone number formats.

  3. Multi-Language Support

    The model can recognize and transcribe over 70 different languages, even when language hints are set to English.

Watch on YouTube Full article

How to build with Gemini 3.5 Transcribe thumbnail

· 4:50

How to build with Gemini 3.5 Transcribe

Google DeepMind launched Gemini 3.5 Transcribe, an LLM-based transcription model available via both the Interactions API and the Live API. This model significantly enhances accuracy by correctly transcribing complex data types—such as email addresses, phone numbers, and mixed units of measurement—and maintaining high performance across over 85 supported languages, even when language codes are set to English.

Key takeaways

  1. LLM-Based Transcription Model

    The model's LLM foundation allows it to handle complex data structures and context better than traditional transcription models. For example, it can correctly identify and edit email addresses even if spoken phonetically (e.g., 'tosten at google.com').

  2. Handling Complex Data Types 2:00

    Gemini 3.5 Transcribe accurately recognizes specific formats, including US phone numbers and international variations (e.g., Singapore's 8-digit format). It can also correctly interpret units of measure (e.g., meters vs. centimeters).

  3. Multilingual and Customization Support 0:40

    The model supports over 85 languages, automatically recognizing spoken language even if language hints are set to English. Accuracy can be further improved by providing custom vocabulary (e.g., names of people in a meeting) or setting specific language codes.

Watch on YouTube Full article

Build a live translation broadcast app with the Gemini Live API and LiveKit thumbnail

· 12:37

Build a live translation broadcast app with the Gemini Live API and LiveKit

This guide details building a real-time multilingual broadcast application using Gemini 3.5 Live Translate via the Gemini API, integrated with LiveKit and deployed on Google Cloud Run. The system efficiently manages multiple language streams by ensuring only one active translation session exists per target language, subscribing new listeners to existing sessions rather than creating redundant ones. The architecture leverages WebSockets for persistent connections and utilizes Next.js for deployment.

Key takeaways

  1. Efficient Session Management 0:58

    The application maintains a maximum of one session per requested target language, subscribing subsequent listeners to the existing LiveGenkit room rather than spinning up new sessions (demonstrated at 0:58).

  2. Deployment Architecture 1:59

    The solution uses Next.js deployed on Google Cloud Run, which allows for hosting long-running WebSockets and managing the necessary stateful connections (1:39).

  3. Scaling Limitations 3:20

    The current demo manages translation details in memory, limiting it to a single Cloud Run instance. Scaling beyond this requires externalizing state management using a database (3:20).

Watch on YouTube Full article

Hands on with Gemini 3.7 Flash thumbnail

· 4:21

Hands on with Gemini 3.7 Flash

The session details how Gemini 3.7 Flash is being utilized by enterprise leaders (Box, Databricks, Emergent) to build highly scalable and cost-efficient multi-agent systems. The focus shifts from merely using the most advanced frontier model to adopting a 'Minimum Viable Model' approach that prioritizes low latency and efficient token usage, enabling complex workflows in regulated industries like finance and insurance.

Key takeaways

  1. Cost-Effective Scaling via Gemini 3.7 Flash

    Gemini 3.7 Flash allows developers to perform tasks using agents at significantly reduced costs (cited as up to 10x cheaper), providing greater budget for further development and exploration.

  2. Pragmatic AI Adoption

    The industry trend favors optimizing cost while maintaining frontier accuracy, moving away from simply adopting the 'coolest' top-tier model. The goal is finding the best model for the job—reliable, low cost, and fast.

  3. Multi-Agent System Architecture 2:00

    Complex tasks are handled by multi-agent patterns: a main agent handles planning (determining required data), which then dispatches specialized subagents to work on parallel exploration. This requires low latency and efficiency.

Watch on YouTube Full article

What is Gemini 3.7 Flash? thumbnail

· 0:47

What is Gemini 3.7 Flash?

The video demonstrates the use of Gemini 3.7 Flash, described as an intelligent 'workhorse model,' for rapid game prototyping and development within Google Antigravity. The speaker showcases generating a detailed, playable animated sprite-based game (a 'pizza rush' concept) from a single prompt, highlighting the model's ability to generate complex initial codebases that can be extended for features like multiplayer functionality.

Key takeaways

  1. Gemini 3.7 Flash Capabilities

    The model is positioned as an intelligent 'workhorse' for coding and agents, capable of generating detailed, playable games from initial prompts (e.g., a pizza rush game).

  2. Code Quality Improvements 0:15

    Beyond gaming, the model shows improvements in shipping quality code across debugging, web development, and overall design adherence.

Watch on YouTube Full article

Introducing Gemini 3.7 Flash thumbnail

· 2:33

Introducing Gemini 3.7 Flash

Gemini 3.7 Flash is introduced as a highly capable 'workhorse model' optimized for coding and agent-first workflows. The video demonstrates its power by building complex, animated sprite-based games within Google Antigravity, showcasing the ability to generate assets (using Nano Banana Pro) from single prompts. A key feature highlighted is the model's capacity for radical concept remixing—adapting an entire game world (e.g., from 'sorcerers' to a 'pizza delivery driver') with minimal prompt changes.

Key takeaways

  1. Agent-Driven Game Prototyping 0:15

    The model successfully generates assets and builds an entire game level (e.g., 90s animated sprite game) from a single prompt within Google Antigravity, demonstrating high design adherence.

  2. Concept Remixing Capability 1:05

    The model can adapt an entire game's look and feel to a completely different concept (e.g., changing the theme from sorcerers to a suburban pizza delivery driver) by modifying only a few words in the prompt.

  3. Model Improvement Areas 1:45

    Gemini 3.7 Flash shows improvements across debugging, web development, and overall design adherence, resulting in higher fidelity builds with less back-and-forth iteration.

Watch on YouTube Full article

How builders at YC Startup School are using Gemini & Google AI thumbnail

· 2:05

How builders at YC Startup School are using Gemini & Google AI

Founders and students at the YC Startup School demonstrated diverse applications of Google AI tools, including Gemini and Gemma. Use cases ranged from leveraging Gemini 3.1 Flash for multilingual document parsing (e.g., international receipts) to utilizing AlphaFold for visualizing bacterial mutations related to antibiotic resistance research. The speakers highlighted the efficiency and context window capabilities of models like Gemini Flash for complex tasks.

Key takeaways

  1. Multilingual Document Parsing 0:25

    Gemini 3.1 Flash is used to parse international receipts from various locations (e.g., Japan, Korea), demonstrating robust multilingual capabilities.

  2. Antibiotic Resistance Research 0:37

    AlphaFold is employed to visualize and study different bacterial mutations, supporting global impact in the pharma and drug discovery industry.

  3. AI for Deep Research Synthesis 0:58

    Gemini's research mode (Deep Research) assists with synthesizing ideas and connecting concepts, particularly useful for neuroscience research or academic papers.

Watch on YouTube Full article

3 things to know about the new CopilotKit integration for Angular thumbnail

· 1:26

3 things to know about the new CopilotKit integration for Angular

The new Copilot Genkit integration for Angular significantly upgrades the capability of building in-app AI features. The update allows developers to build agent-powered web applications and deeply integrated, context-aware AI functionalities directly into existing Angular architectures.

Key takeaways

  1. Copilot Genkit Integration for Angular

    Copilot Genkit has officially landed for Angular, enabling the creation of agent-powered web applications. Service AI maintains the Angular wrapper, ensuring production-ready reliability and full support.

  2. Context-Aware AI Features

    Developers can build deeply integrated features, including native SmartText areas, custom AI chatbots, and autonomous agents that seamlessly integrate with the Angular application state.

  3. Generative UI for Bespoke Interfaces

    The Generative UI feature allows an agent to utilize any component catalog within a design system, selecting and presenting the optimal user interface (UI) or requesting necessary inputs dynamically.

Watch on YouTube Full article

Voice Agent observability with LangSmith 🌟 thumbnail

· 0:55

Voice Agent observability with LangSmith 🌟

This session demonstrates how to achieve deep observability for voice agents using LangSmith when integrating Google's Gemini Live model and the Google ADK. Since Gemini Live is a native speech-to-speech model that bypasses text transcription to maintain low latency, robust tracing is critical. The process involves setting up tools (like a weather assistant), recording both user and agent audio, and utilizing LangSmith to view comprehensive traces that include transcripts, tool calls, interruption events, full cost breakdowns, and even audio playback for debugging.

Key takeaways

  1. Gemini Live's Low-Latency Advantage

    Gemini Live is Google's native speech-to-speech model; it takes audio directly as input and produces audio output without transcribing to text, which keeps latency low and ensures a natural voice experience.

  2. Comprehensive Voice Agent Tracing

    LangSmith provides visibility into the agent's internal workings, capturing not only standard transcripts and tool calls but also specific events like interruptions and detailed token-level cost breakdowns.

  3. Production Readiness Tools

    The observability provided by LangSmith allows engineers to perform standard LLM operations—such as running evals, adding traces to data sets, building dashboards, and debugging—on complex voice agent interactions.

Watch on YouTube Full article

Introducing Gemini Robotics 2 thumbnail

· 39:14

Introducing Gemini Robotics 2

Google DeepMind introduced Gemini Robotics 2, a new suite of models designed to provide the intelligence layer for general-purpose robotics. The system enables whole-body understanding and reasoning, allowing robots to perform complex tasks like cleaning a garage or folding laundry based on natural language prompts. Key advancements include enhanced dexterity, multi-robot collaboration capabilities, and leveraging Gemini's multimodal world understanding by adding 'actions' as a modality.

Key takeaways

  1. Whole-Body Intelligence 2:10

    Gemini Robotics 2 enables models to understand the entire robot's position in space and reason about complex, multi-step tasks (e.g., cleaning a garage), moving beyond simple object manipulation.

  2. Enhanced Dexterity 4:05

    The models significantly improve dexterity, allowing robots to perform intricate daily tasks such as folding laundry or precisely unscrewing objects using high-DOF hands.

  3. Multi-Robot Collaboration 5:01

    A new capability allows the robot intelligence to understand when and how to call other robots to accelerate tasks or perform actions in parallel.

  4. Availability and Deployment 25:39

    The Embodied Reasoning (ER) model will be available via AI Studio and the Gemini Enterprise Agents Platform. An on-device version is also available through a trusted tester program.

Watch on YouTube Full article

Voice Agent observability with LangSmith thumbnail

· 7:38

Voice Agent observability with LangSmith

This session details how to implement robust observability for voice agents built using the Google ADK and Gemini Live model by integrating LangSmith tracing. The process involves defining a custom plugin that captures not only the conversation transcript but also the full audio stream (user input and agent output). This visibility allows engineers to debug complex interactions, analyze tool usage, track interruption events, and monitor token-level costs for production readiness.

Key takeaways

  1. Gemini Live Model Functionality

    Gemini Live is Google's native audio model that operates in a speech-to-speech manner. It takes audio directly as input and produces audio as output without transcribing to text, resulting in low latency and natural, emotive voice quality.

  2. LangSmith for Observability 2:05

    LangSmith is a platform built by LangChain specifically for AI agent observability and evaluations. It provides visibility into the internal workings of the voice agent, which is crucial for safe production deployment.

  3. Capturing Conversation Audio 4:00

    To ensure the 'source of truth' for a voice interaction is captured, the tracing setup must include functions to record both user audio and agent audio. Recording agent audio requires careful placement (e.g., using a `set play callback` on the audio out class) to capture only what the user actually heard.

Watch on YouTube Full article

Android Studio Quail 2, the Build with Gemini XPRIZE, and more! - Google Developer News July 2026 thumbnail

· 5:24

Android Studio Quail 2, the Build with Gemini XPRIZE, and more! - Google Developer News July 2026

This Google Developer News update details major advancements in Android development tools, including the stable release of Android Studio Quail 2. Key features include parallel agentic task management and enhanced memory leak detection via Leak Canary. Furthermore, the session covers updates to Android Bench for LLM evaluation using the Harbor framework, an inside look at YouTube's AI prototyping stack (Emergent), and details the Build with Gemini XPRIZE competition offering a $2 million prize pool.

Key takeaways

  1. Android Studio Quail 2 Stable Release

    The stable release introduces parallel chats for managing multiple agentic tasks simultaneously, upgrading Leak Canary integration into the profiler for faster heap analysis (up to five times faster), and integrating App Quality Insights with production reports (Firebase/Crashlytics) to automatically suggest or fix crash-causing code.

  2. Android Bench Methodology Upgrade 0:01

    Updates are rolling out to Android Bench, standardizing on the Harbor framework for model evaluation. Cloud fable 5 currently leads the leaderboard with a score of 84.5, and users can now submit unique development tasks to shape the benchmark.

  3. YouTube AI Prototyping Stack (Emergent) 0:02

    The series reveals how YouTube builds flexible, safe prototyping environments that minimize technical debt and system layers for rapid idea testing across Google's product lines.

  4. Build with Gemini XPRIZE Competition 0:02

    A $2 million competition challenges developers to build a real business using AI by solving a real-world problem, utilizing the full Google stack from Gemini app validation to Google Cloud scaling. The deadline is August 17.

Watch on YouTube Full article

Building the ultimate morning dashboard with Gemini 3.6 Flash and Nano Banana thumbnail

· 1:14

Building the ultimate morning dashboard with Gemini 3.6 Flash and Nano Banana

The video details a personal project—an automated, image-based dashboard displayed on an e-ink picture frame—designed to help families manage daily routines. The system leverages Gemini 3.6 Flash and Nano Banana to intelligently generate visual reminders (e.g., suggested clothing based on weather and calendar events), significantly reducing morning friction. The entire process is scheduled nightly using AntiGravity, making the complex AI workflow accessible even to non-professional developers.

Key takeaways

  1. AI-Powered Daily Dashboard

    The system functions as an image-based calendar that suggests appropriate clothing and items for kids based on scheduled events and current weather conditions, displayed on an e-ink screen.

  2. Automated Workflow Design

    The process is automated nightly at 1:00 AM using AntiGravity. A script checks the Google Calendar and weather data, generating a prompt for Nano Banana to create an image.

  3. Model Selection Rationale

    Gemini 3.6 Flash was chosen for its combination of intelligence, speed, and low cost, which is critical for a system running daily.

Watch on YouTube Full article

Expose your site's actions to AI agents using WebMCP thumbnail

· 1:29

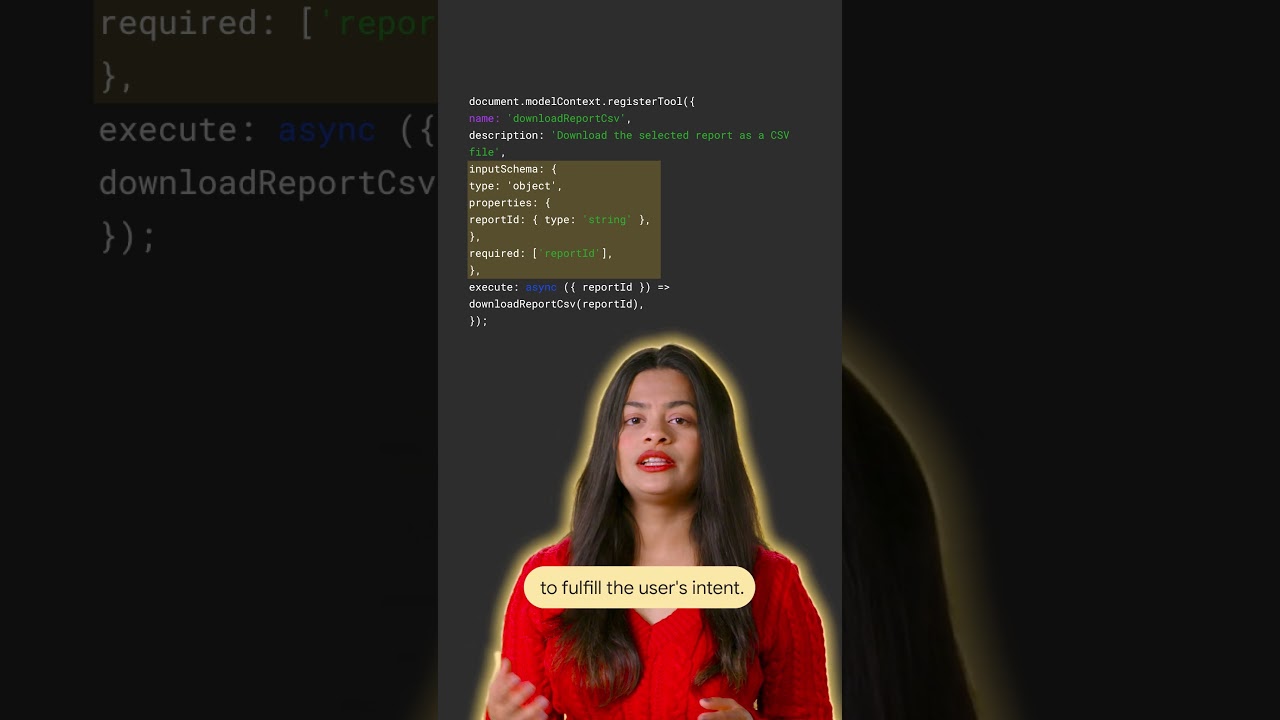
Expose your site's actions to AI agents using WebMCP

This talk introduces WebMCP (Web Manifest Capabilities Protocol), a method for web sites to expose their functional capabilities directly to AI agents. Instead of relying on agents to interpret the UI like a human, developers can register tools using plain JavaScript, defining explicit inputs and outputs via a schema. This allows agents to perform direct tool calls (e.g., 'Download report CSV') rather than attempting button interactions, significantly improving reliability for automated agent workflows.

Key takeaways

  1. Problem with Current AI Agent Interaction

    AI agents often fail or go off course because they misinterpret the visual interface (UI) of a website, forcing them to interact like a human user.

  2. WebMCP Solution: Exposing Capabilities

    WebMCP allows sites to explicitly expose what they can do. Developers register tools using plain JavaScript, providing a name, description, and function that performs the action.

  3. Reliable Agent Interaction via Schema

    By defining explicit inputs and outputs (the schema), agents can bypass guesswork. They discover capabilities and execute direct tool calls, such as calling 'Download report CSV' directly.

  4. Alternative Exposure Methods

    If JavaScript is not used, capabilities can be exposed by annotating supported HTML forms instead.

Watch on YouTube Full article

How are large language models trained? thumbnail

· 10:09

How are large language models trained?

Large Language Models (LLMs) undergo two core training phases: pre-training and post-training. Pre-training uses next token prediction on massive datasets to build foundational language knowledge. Post-training refines this model for safety, helpfulness, and instruction following using techniques like Supervised Fine-Tuning (SFT) and Reinforcement Learning (RL). The process requires complex engineering at scale, including managing petabytes of data and utilizing advanced evaluation methods like auto-raters.

Key takeaways

  1. Pre-training: Foundational Knowledge

    The initial phase trains the model using next token prediction (a self-supervised task). This allows the LLM to implicitly learn language patterns and world knowledge without manual labeling. Scaling this process is a massive engineering challenge, requiring complex parallelism across thousands of interconnected GPUs, automated recovery systems, and pipelines for petabytes of data.

  2. Post-training: Alignment and Refinement 5:40

    This phase focuses on aligning the model to be safe, helpful, and accurate. It primarily involves Supervised Fine-Tuning (SFT) using gold standard examples, or Reinforcement Learning (RL), where a separate Reward Model grades responses for quality, pushing the LLM toward desired behaviors.

  3. Evaluation and Measurement 7:40

    Measuring model success requires defining clear criteria. While pre-training measures next word prediction accuracy, post-training focuses on alignment (e.g., helpfulness). Evaluation is scaled using a second LLM—an auto rater—to score responses against defined criteria.

Watch on YouTube Full article