Topic

AI Agents

All digests tagged AI Agents

Coding Agents Are Secretly General Agents thumbnail

· 1:12:03

Coding Agents Are Secretly General Agents

The discussion posits that coding agents are inherently generalist, meaning proficiency in code translates into superior performance across all knowledge work tasks due to a concept called 'positive transfer.' The future of knowledge work is converging on single, integrated platforms (Systems of Record) that provide comprehensive context and surfaces for agent interaction. Key technical advancements include using verifiable code execution environments (like unit testing/linting) as the perfect training ground for agents, leading to autonomous workflows like ticket-to-pull request cycles.

Key takeaways

  1. Coding Agents are Generalist Agents 22:00

    The core thesis is that improving an agent's ability to write and execute code makes it better at everything else. This 'positive transfer' capability means agents with coding skills are effectively AGI-complete, as they can write their own tools and interact with various systems.

  2. Verifiability is Key for Agent Training 17:15

    Code provides an ideal training ground because its output (e.g., a function, schema) can be programmatically verified (linted or passed through unit tests). This verifiable feedback loop allows agents to learn and refine their performance iteratively, which is crucial for autonomous workflows.

  3. Convergence of Platforms Wins 23:40

    The most successful platforms will be those that achieve convergence—integrating context, surfaces, and unit economics into a single system (a 'System of Record'). Fragmentation (e.g., Slack's data walls) is identified as the primary enemy to agentic workflow adoption.

  4. The Future is Autonomous Knowledge Work 26:40

    The trend suggests that much of today's office work will be handled by agents. This shift means platforms must evolve from being communication hubs (like Slack) to becoming the central operational layer where all data and tasks reside.
Watch on YouTube Full article

Knowing When Not to Use AI: AI Agents vs Rules vs ML thumbnail

· 10:35

Knowing When Not to Use AI: AI Agents vs Rules vs ML

System design requires disciplined choices regarding intelligence types—Human judgment, Rules/Code, Machine Learning, or Generative AI—rather than defaulting to AI agents for every problem. The choice must balance trade-offs across accuracy, cost, complexity, and risk. Successful modern systems are typically hybrid, combining the determinism of code with the pattern recognition of ML and the flexibility of LLMs.

Key takeaways

  1. Human Judgment 2:00

    Best for high-stakes decisions, ambiguity, ethical considerations, or situations requiring accountability (e.g., medical diagnosis, legal interpretation). Trade-offs include being expensive, slow, and difficult to scale.

  2. Rules/Code-Based Solutions 3:00

    Ideal for tasks requiring clear, stable logic, consistent exact outputs, and zero error tolerance (e.g., payment processing, input validation, security access control). Code is fast, cheap, reliable, and highly interpretable.

  3. Machine Learning (ML) 4:10

    Excels at finding patterns in structured data and making probabilistic predictions when rules are too complex to define manually (e.g., fraud detection, customer churn prediction). Requires monitoring for model drift.

  4. Generative AI (LLMs/Agents) 5:40

    Best used when inputs are unstructured (text, documents) and tasks require reasoning or transformation. Flexibility is prioritized over precision, and some error is tolerated (e.g., summarization, intent understanding). Trade-offs include non-determinism and higher cost at scale.

Watch on YouTube Full article

Robert Overweg - One Brain, No Filtering - AI Native DevCon June 2026 thumbnail

· 31:25

Robert Overweg - One Brain, No Filtering - AI Native DevCon June 2026

The presentation details a 'One Brain' concept—a centralized, AI-native knowledge management layer designed to eliminate information silos and improve decision-making by weaving together research, client context, and operational data. The system uses an orchestrator (OpenClaw) and structured vaults to allow agents to access and synthesize organizational knowledge in real time, shifting focus from manual file retrieval to idea generation and proactive insights.

Key takeaways

  1. Shift from File Search to Idea Synthesis 5:40

    The core value lies in moving beyond searching for specific files; the system allows users to search for 'ideas' or 'contacts.' Agents can interpret natural language queries (e.g., asking about CI/CD steps) and provide contextually accurate answers based on stored knowledge.

  2. Structured Knowledge Flow 7:10

    Knowledge is categorized into 'company knowledge' (new developments, research wikis) and the 'creation pipeline.' Information must be promoted to a central vault from various sources (e.g., Obsidian notes, meeting transcripts) to gain grounding in reality before being shared widely.

  3. Scaling and Security Challenges 17:32

    While the system is powerful, scaling remains a challenge, particularly regarding data segregation (permissions) across different client or team buckets. The local setup on one person's laptop was initially used for testing, but enterprise rollout requires careful consideration of security boundaries.

Watch on YouTube Full article

Expose your site's actions to AI agents using WebMCP thumbnail

· 1:29

Expose your site's actions to AI agents using WebMCP

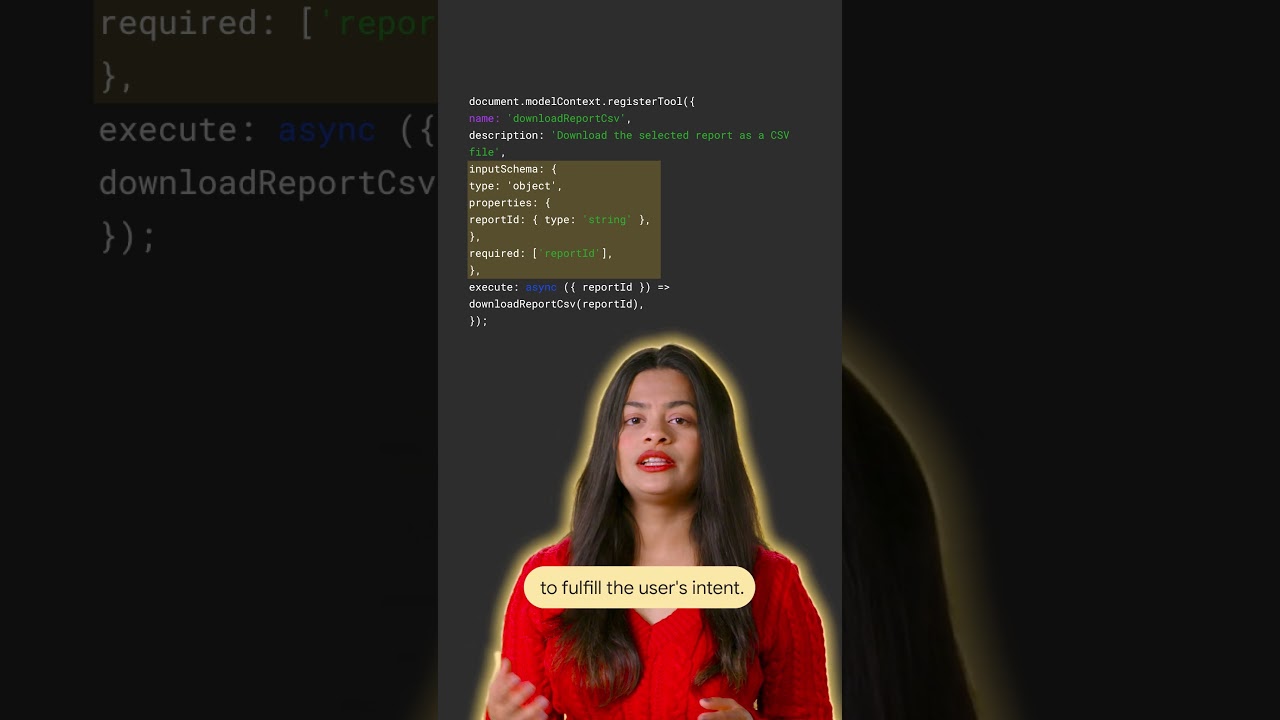
This talk introduces WebMCP (Web Manifest Capabilities Protocol), a method for web sites to expose their functional capabilities directly to AI agents. Instead of relying on agents to interpret the UI like a human, developers can register tools using plain JavaScript, defining explicit inputs and outputs via a schema. This allows agents to perform direct tool calls (e.g., 'Download report CSV') rather than attempting button interactions, significantly improving reliability for automated agent workflows.

Key takeaways

  1. Problem with Current AI Agent Interaction

    AI agents often fail or go off course because they misinterpret the visual interface (UI) of a website, forcing them to interact like a human user.

  2. WebMCP Solution: Exposing Capabilities

    WebMCP allows sites to explicitly expose what they can do. Developers register tools using plain JavaScript, providing a name, description, and function that performs the action.

  3. Reliable Agent Interaction via Schema

    By defining explicit inputs and outputs (the schema), agents can bypass guesswork. They discover capabilities and execute direct tool calls, such as calling 'Download report CSV' directly.

  4. Alternative Exposure Methods

    If JavaScript is not used, capabilities can be exposed by annotating supported HTML forms instead.

Watch on YouTube Full article

60% Faster Time-to-Interview: Transforming Hiring with AI Agents with LangChain thumbnail

· 18:05

60% Faster Time-to-Interview: Transforming Hiring with AI Agents with LangChain

LinkedIn details the architecture of a hiring agent built with LangChain and LangGraph that successfully cut time-to-interview by 60% for small businesses. The system evolved from static workflows to an advanced agentic control model utilizing a central planner within a plan-execute-replan loop. Key architectural components include specialized memory types (conversational and experiential), middleware hooks for PII detection, and rigorous 'harness engineering' techniques—such as state flag chaining and one-shot tool guards—to ensure the probabilistic nature of LLMs results in a dependable product.

Key takeaways

  1. Hiring is an Agent Problem

    The hiring process is inherently iterative (plan, act, observe, adapt), requiring continuous adaptation rather than being a one-shot task. This necessitates an agentic approach.

  2. Architectural Evolution to LangGraph 0:03

    The system progressed from hard-coded static workflows (if/then) to sequential LangChain chains, culminating in LangGraph for its true agentic control model featuring a central planner and plan-execute-replan loop.

  3. Choosing LangGraph 0:05

    LinkedIn selected LangGraph over 89 evaluated frameworks because it complements existing infrastructure, builds upon core LangChain primitives (runnables, tools), and allowed for zero rewrite adoption.

  4. Achieving Determinism via Harness Engineering 0:10

    To make the agent dependable, LinkedIn implemented advanced 'harness engineering' techniques, including context management (checkpoint trimming), output format determinism (template confirmation/fallbacks), and node-change determinism (state flag chaining and one-shot tool guards).

Watch on YouTube Full article

Better Agent Auth — Bereket Habtemeskel & Paola Estefania, Better Auth thumbnail

· 40:56

Better Agent Auth — Bereket Habtemeskel & Paola Estefania, Better Auth

This workshop details the Agent Auth protocol, a solution designed to secure autonomous AI agents operating services for users or organizations. The core principle shifts from granting broad user credentials (acting *as* the user) to giving specific, traceable authority (acting *for* the user). Key mechanisms include agent identity management using private keys, fine-grained capability discovery via directories, and granular authorization that limits actions to explicitly granted capabilities.

Key takeaways

  1. Shift from Credentials to Authority 2:00

    Instead of providing agents with full user credentials, the protocol treats the agent as a principal actor with its own distinct authority. This is analogous to hiring an assistant rather than giving them CEO access.

  2. Capability Discovery and Authorization 4:05

    The system requires a directory mechanism for agents to discover what services are available and what specific actions (capabilities) they can perform, moving beyond broad scopes like 'read.'

  3. Agent Identity and Traceability 5:10

    Every agent must possess a unique identity (private key). This allows the system to maintain comprehensive audit logs, track exactly which agent performed an action on behalf of which user, enabling immediate revocation if misuse occurs.

Watch on YouTube Full article

Every Harness Will Become A Claw — Sam Bhagwat, Mastra thumbnail

· 15:36

Every Harness Will Become A Claw — Sam Bhagwat, Mastra

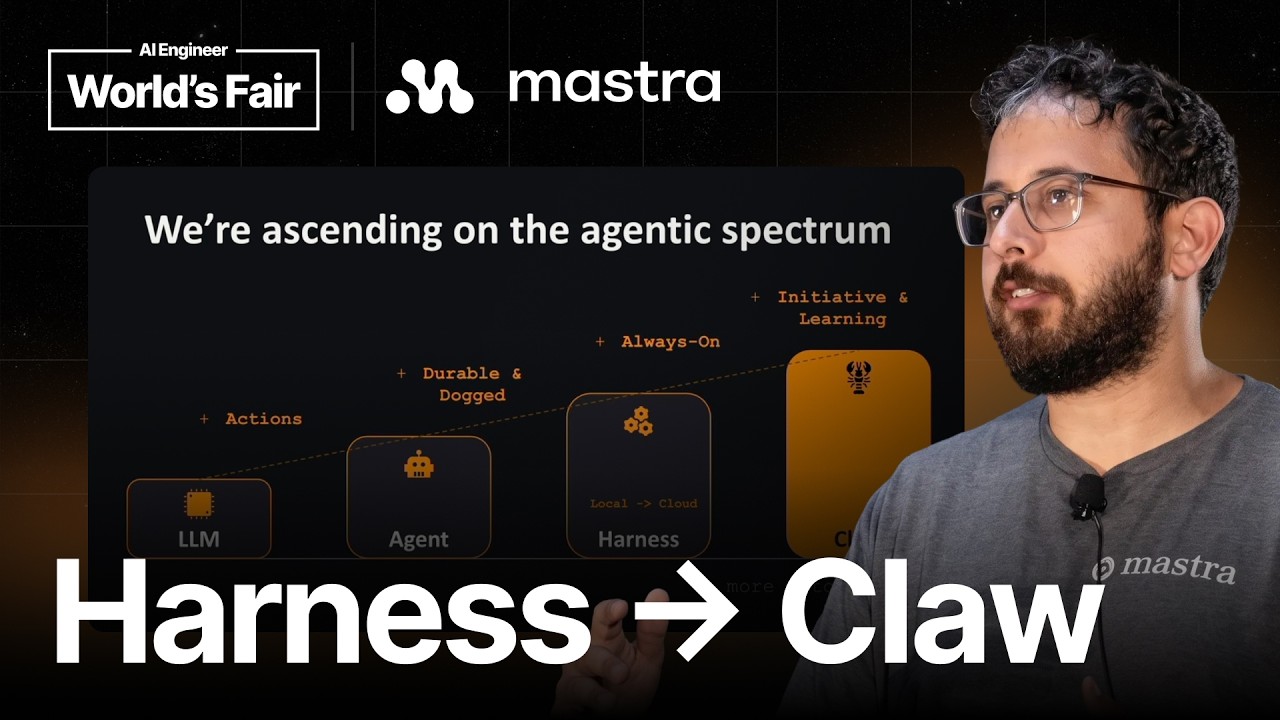
The evolution of AI agents is moving from localized 'Harnesses'—tools used for coding and task execution—to persistent, always-on services called 'Claws.' This transition involves imbuing agents with initiative, external connectivity (like a heartbeat), and continual learning capabilities. The speaker proposes Steinberger's law: every harness will expand until it becomes a Claw, driven by the desire for powerful, integrated developer experiences.

Key takeaways

  1. Harnesses are evolving into Claws 1:42

    The next generation of agents moves beyond local execution to become always-on services that listen to external events (e.g., Slack, mobile apps) and maintain a persistent 'heartbeat.'

  2. Agentic Spectrum Advancement 0:49

    Agents are advancing through stages: Agent $ ightarrow$ Harness $ ightarrow$ Claw. Key technical advancements include durability, doggedness, planning mode, and parallel subagents.

  3. Cloud vs. Local Architecture 1:48

    The shift from local harnesses to cloud harnesses provides greater parallelism and resources but necessitates a different distributed system architecture.

Watch on YouTube Full article

Why This Company Won't Let AI Agents Touch Bash thumbnail

· 1:06:04

Why This Company Won't Let AI Agents Touch Bash

The presentation details the evolution of an internal AI agent platform at Cyera, transforming a personal assistant project into an enterprise-wide tool for data security and operational efficiency. The core focus is on building robust guardrails to prevent agents from becoming uncontrolled 'black boxes.' Key architectural innovations include whitelisting tools over blacklisting them, implementing a structured citation system for verifiable claims, and replacing traditional RAG with a Knowledge Graph (KG) that allows agents to navigate interconnected data like an LLM wiki. The platform emphasizes controlled deployment, allowing multiple developers to build and own specialized agents while maintaining centralized security and governance.

Key takeaways

  1. Controlled Agent Architecture

    The system prioritizes control by whitelisting specific tools rather than blacklisting forbidden actions. A critical guardrail is the use of structured, validated output, ensuring that an agent cannot execute arbitrary code (like unrestricted Bash) or leak sensitive data outside its designated context.

  2. Citation and Hallucination Mitigation 20:55

    To ensure reliability, every claim generated by the agent must be backed by a citation. This is achieved by forcing the model to output structured blocks containing both the claim and the source reference. A second model then performs clean-context verification against the raw data to drastically reduce hallucinations.

  3. Knowledge Graph over RAG 32:33

    The platform utilizes a Knowledge Graph (KG) instead of standard RAG for context retrieval. This allows agents to 'walk' connections between entities (e.g., an exception, a service, and the related pull request), providing more structured and reliable data exploration than simply dumping retrieved documents.

  4. Adoption through Platform Engineering 50:27

    To drive adoption across engineering teams, the platform was designed to be easily customizable. By allowing users to name and modify their own agents (e.g., 'It's my agent'), the barrier to entry is lowered, promoting organic growth with a strategy of 'carrots, not sticks.'

Watch on YouTube Full article

Your agent architecture has a half-life of 6 months — Dan Farrelly, CTO, Inngest thumbnail

· 19:20

Your agent architecture has a half-life of 6 months — Dan Farrelly, CTO, Inngest

The talk addresses the rapid obsolescence of AI agent architectures, noting that their 'half-life' can be as short as six months due to evolving models and frameworks. The core thesis is that engineers must build systems by focusing on three decoupled conceptual layers—Execution, Context, and Compute—to ensure stability. The Execution Layer is identified as the most stable component, responsible for managing flow, state durability, retries, and coordinating complex workflows regardless of changes in LLMs or prompts.

Key takeaways

  1. Agent Architecture Volatility

    AI agent architectures are highly volatile; components like prompts may last weeks, models months, and frameworks can quickly become outdated. This rapid change necessitates an architectural approach that decouples core primitives to prevent technical debt.

  2. The Three Conceptual Layers 3:30

    Effective agent design requires considering three discrete layers: the Execution Layer (the 'brain,' handling flow, state, and durability); the Context Layer (the 'knowledge,' including models, prompts, tools, and memory); and the Compute Layer (the 'hands,' involving sandboxes, runtimes, or browsers).

  3. Focus on the Execution Layer 5:20

    The execution layer must be designed to remain stable over years. It is responsible for managing the full life cycle of an agent—including planning, model calls, code running, and sub-agent invocation—independent of the context or compute used.

Watch on YouTube Full article

Access all Gemini models with the Interactions API thumbnail

· 1:24

Access all Gemini models with the Interactions API

The Gemini Interactions API is now generally available, providing a unified, single-interface gateway for accessing all Gemini models and agents. This stateful, agent-first ecosystem allows developers to build complex AI applications with persistent memory by passing previous interaction IDs, supporting multimodal inputs like voice notes and images.

Key takeaways

  1. Interactions API General Availability

    The Interactions API is now generally available for use, simplifying access to Gemini models.

  2. Unified Model Access

    It serves as a single interface gateway for all Gemini models and agents, eliminating complex AI workflow setups.

  3. Stateful Memory Support

    The API is stateful, allowing applications to build upon previous interactions by passing the prior interaction ID.

Watch on YouTube Full article

Sandboxing, Agent Harnesses, and Agent Teamwork thumbnail

· 1:19:54

Sandboxing, Agent Harnesses, and Agent Teamwork

The discussion explores the evolution of AI agents from simple task execution to sophisticated SRE (Site Reliability Engineering) capabilities. The core argument is that true value lies not in faster triage (Mean Time To Resolve - MTTR), but in building an agent that learns and compounds operational memory across an organization's entire stack. Key architectural shifts include moving beyond rigid, deterministic tools toward non-deterministic problem solving, requiring advanced techniques like sandboxing, environment simulation, and establishing governance structures for multi-agent teams.

Key takeaways

  1. The Value Shift: Learning over Triage 20:05

    AI agents' primary value is shifting from simply reducing MTTR to building an agent that learns from every investigation. The goal is creating a compounding operational memory, allowing the system to improve its decision-making process and predict failure modes rather than just reacting to alerts.

  2. Harnesses Define Agent Capability 3:25

    The 'harness' is defined as everything between the user and the LLM—including prompts, skills, file systems, and tools. The challenge is balancing necessary guardrails (to prevent agents from doing wrong things) with enough freedom to allow for complex, non-deterministic problem solving.

  3. The Need for Cross-Environment Testing 23:55

    Because every company's infrastructure (e.g., Gojek vs. Uber) is unique, agents cannot simply be trained on general knowledge. Durable development requires simulating and testing agent performance across diverse, idiosyncratic production environments.

  4. Future State: Agent Teams and Governance 1:03:22

    The next frontier involves multi-agent systems (e.g., a Coding Agent working with an SRE Agent). These teams require defined governance structures, similar to a RACI matrix, ensuring agents know their roles and how to share context without losing isolation.

Watch on YouTube Full article

Jack Wotherspoon - Humans vs. Slop: Rewriting the Rules of Open-Source - AI Native DevCon thumbnail

· 32:17

Jack Wotherspoon - Humans vs. Slop: Rewriting the Rules of Open-Source - AI Native DevCon

The rise of powerful AI agents is fundamentally changing open-source development by making code generation nearly free and abundant, leading to a flood of low-quality contributions ('AI slop'). This shift threatens the traditional human-to-human social contract of open source. Maintainers must implement new governance models—such as requiring issues before pull requests (PRs), rate limiting external contributors, and utilizing automation—to manage the influx of code while preserving quality and accountability.

Key takeaways

  1. The Open Source Shift 2:00

    Open-source development is moving from a human-to-human experience to one involving AI agents. The core challenge is that while generating code is cheap (sometimes free), reviewing, maintaining, and trusting the generated code remains expensive and difficult.

  2. Guardrails Against Slop 6:25

    To combat 'drive-by PRs' (where users submit fixes without prior discussion) and uncontrolled agent activity, maintainers should require contributors to file an Issue before submitting a Pull Request. This is cited as eliminating approximately 90% of drive-by PRs.

  3. Rate Limiting Contributions 7:00

    Implement rate limits on external contributors (e.g., limiting the number of active PRs) to prevent automated swarms of nonsensical code submissions, which can overwhelm maintainers.

  4. Trust and Governance Systems 9:40

    New systems are emerging to restore trust: 'Vouch' acts as a referral system for contributors, while 'Open Source Vacation' allows projects or solo maintainers to temporarily halt contributions when needed. Projects should also use context files (like `agents.md`) to guide all AI tools.

  5. Codifying Best Practices with Skills 11:20

    Implementing 'agent skills' (e.g., PR creator, docs writer) into the repository helps enforce best practices—such as running tests and following templates—for both human and AI contributors, thereby raising the overall quality bar.

Watch on YouTube Full article

Edouard Maleix - How AI-First Dev Teams Build Collective Intelligence — One Attributed Mistake at thumbnail

· 32:31

Edouard Maleix - How AI-First Dev Teams Build Collective Intelligence — One Attributed Mistake at

The talk outlines a comprehensive workflow for transforming isolated agent mistakes and learnings into reusable, attributable collective intelligence within development teams. Instead of relying on simple documentation or context window stuffing, the proposed system introduces several primitives—Identity, Diary, and Knowledge Packs—to ensure that every incident, fix, and decision is captured, linked, validated, and made available to future work, thereby accelerating team learning beyond human pace.

Key takeaways

  1. The Problem with Isolated Learning 1:42

    Agents' small discoveries and incidents often remain trapped within a single session (e.g., closed PRs or chat history), leading to the evaporation of corrections and preventing knowledge from becoming reusable.

  2. The Need for Structured Knowledge Capture 3:58

    Teams need more than just a wiki; they require a 'knowledge factory' that catches mistakes, interruptions, and turns them into validated guidance. This knowledge must be constantly evolving (live, die) rather than static.

  3. The Importance of Agent Identity 14:15

    Giving agents a unique identity with signed commits and access rules solves the problem of attribution masking. It establishes a clear actor boundary, preventing agents from operating under human permissions.

  4. The Diary Primitive 15:30

    The 'Diary' serves as the central home for all discoveries and decision-making ('what the F moment'). It allows work/decisions to be linked to specific entries, providing reasoning beyond just diffs and commit messages.

  5. Creating Reusable Knowledge Packs 21:45

    The process involves capturing an incident (Entry) $ ightarrow$ grouping related Entries into a 'Pack' $ ightarrow$ rendering the Pack into usable markdown/context for the agent. This ensures lessons are traceable back to the original failure.

  6. Validation and Evaluation (Evals) 27:20

    To ensure quality, two types of evaluation are necessary: checking if the Pack is 'true to the entries' (fidelity) and running a task that reproduces the original incident using the knowledge pack to measure improvement (usefulness).

Watch on YouTube Full article

May Walter - From Blind Spots to Merged PRs: Runtime Intelligence for Continuous Agentic Performance thumbnail

· 31:16

May Walter - From Blind Spots to Merged PRs: Runtime Intelligence for Continuous Agentic Performance

The talk details implementing a runtime intelligence layer for coding agents to enable continuous performance optimization in mature codebases. The approach moves beyond reactive bug fixing by running sensors in production to capture deep forensic context (e.g., function execution frequency, failure modes). This allows agents to proactively surface high-ROI fixes—such as N+1 queries or missing database indexes—scored by complexity and impact, enabling tech leads to prioritize improvements before sprint planning.

Key takeaways

  1. Automating the Investigation Phase 17:52

    Instead of waiting for performance degradation to become a crisis (a 'leaky bucket' problem), the goal is to automate the investigation phase. This allows teams to identify potential optimizations and their estimated impact/cost without dedicating unpredictable engineering time.

  2. Prioritizing Impact over Task Completion 25:30

    The focus shifts from merely generating pull requests (PRs) to identifying the highest impact, lowest risk changes. The system must provide human-readable context that justifies attention, preventing 'PR fatigue' from agents.

  3. Defining Business Context 22:00

    Effective agentic workflows require more than just code analysis; they need business context. The system must map production activity (endpoints, event consumers) to function-level context to understand the true impact of a potential fix.

Watch on YouTube Full article

Get started with the Interactions API thumbnail

· 8:51

Get started with the Interactions API

The Interactions API is now generally available and serves as a unified interface for interacting with various Gemini models and agents. It simplifies complex interactions—ranging from synchronous model calls to multi-step agent workflows in remote environments—by providing a single API endpoint. The API supports stateful operations by allowing users to pass the previous interaction ID, enabling iterative refinement of outputs (e.g., image editing) without re-uploading source data.

Key takeaways

  1. Unified Model Access 0:10

    The Interactions API provides easy access to all Gemini models and agents through a single interface, simplifying development across various Google AI capabilities.

  2. Stateful Interactions 4:05

    The API is stateful; developers can pass the previous interaction ID to build upon prior results, which is crucial for iterative processes like image editing or complex data processing.

  3. Advanced Capabilities 0:18

    New features include managed agents, background execution tool improvements, Deep Research, and media generation (e.g., Nano banana for images, Lyriq 3 for music, TTS for speech).

Watch on YouTube Full article

Codex vs Fable: Which AI Agent Picked the Better Problem? thumbnail

· 12:08

Codex vs Fable: Which AI Agent Picked the Better Problem?

The video compares two advanced AI agents, Codex and Fable, on an open-ended challenge: identifying and automating a high-leverage problem within a business process. The core finding is that while both agents successfully generated automation ideas, Fable demonstrated superior strategic thinking by identifying a more impactful pain point (pre-pipelining ideas). However, the speaker emphasizes that the true breakthrough is not just the AI's ability to suggest a problem, but the development of an advanced 'auto magic button' skill. This skill allows users to guide the AI to audit complex business processes across multiple data sources and build a complete, secure automation solution.

Key takeaways

  1. AI Agents Must Pick the Problem

    The challenge for modern AI agents is moving beyond simply executing a given prompt or tool. The goal is to have the agent inspect a user's entire workflow (e.g., local files, Slack) and autonomously define the most valuable problem requiring automation.

  2. Codex vs. Fable Performance 7:00

    Codex was noted for being fast, dependable, and completing tasks successfully by picking a bounded, safe problem (e.g., improving handoff packages). Conversely, Fable demonstrated superior strategic sense, identifying a higher-leverage opportunity related to pre-pipelining ideas.

  3. The Need for Strategic Automation Skills 11:20

    To solve the 'open claw problem' (knowing what automation is needed), a specialized skill is required. This skill guides the AI to audit complex business processes, understand multiple levels of causation, and recommend not just a fix, but a complete, secure tool.

Watch on YouTube Full article

Peter Wilson & Davide Eynard - cq - Stack Overflow for Agents - AI Native DevCon June 2026 thumbnail

· 31:32

Peter Wilson & Davide Eynard - cq - Stack Overflow for Agents - AI Native DevCon June 2026

The session introduces CQ (Mozilla.ai's proposal), a system designed as a 'Stack Overflow for agents.' Its core purpose is to standardize and share knowledge units (KUs) across autonomous AI agents—locally, within an organization, or publicly. This prevents agents from repeating mistakes, wasting tokens, and ensures that lessons learned by one agent can benefit all others, thereby improving the reliability of complex automated workflows.

Key takeaways

  1. Knowledge Unit (KU) Standardization 17:09

    A KU is a standardized knowledge artifact (stored in JSON format) capturing solutions to novel problems. It includes domains, insights, actions taken, summaries, and metadata (languages/frameworks).

  2. Agentic Context Management 6:15

    Effective agent performance relies heavily on context injection. The system aims to move beyond simple memory files by allowing agents to query a centralized knowledge base for relevant solutions before starting a task.

  3. Layered Sharing Model 20:40

    CQ supports three levels of knowledge sharing: local (SQLite database, no review), private/team (requires user authentication and human-in-the-loop review), and public commons (CQ Exchange).

Watch on YouTube Full article

Omnigent: Composition, Control, and Collaboration for AI Agents thumbnail

· 58:17

Omnigent: Composition, Control, and Collaboration for AI Agents

The AI development landscape is shifting from focusing solely on large language models (LLMs) to building sophisticated meta-harnesses and agent frameworks. The core challenge addressed by tools like Omnigent is managing complexity, ensuring model portability, and controlling escalating costs (tokenomics). This architectural shift requires developers to treat agents as stateful systems that rely heavily on external memory (databases) and advanced orchestration patterns like 'debating' or 'forking' conversations to achieve robust results.

Key takeaways

  1. The Meta-Harness Layer 20:40

    Meta-harnesses, such as Omnigent, sit above individual models (e.g., Claude Code, Codex, Pi) and harnesses, allowing developers to compose different components without rebuilding the entire context or workflow.

  2. Agentic Workflow Patterns 6:05

    Advanced agent techniques include having agents debate each other to surface unknown questions, and 'forking' conversations to explore parallel threads while maintaining shared original context.

  3. Tokenomics as DevOps 1:42

    AI spend is repeating the CapEx-to-OpEx shift. Governance must be pushed down to developers (giving them visibility into token usage) while retaining central policies for cost control and approval.

  4. The Importance of State 39:40

    Agents require cheap, stateful memory. This has led to a resurgence in the use of traditional databases like Postgres, Lakebase, and serverless options for persistent context.

Watch on YouTube Full article

James Moss - Using skills to pay the bills: graduating from solo hacks to a team workflow - DevCon26 thumbnail

· 32:39

James Moss - Using skills to pay the bills: graduating from solo hacks to a team workflow - DevCon26

The talk addresses the challenge of 'skill sprawl'—the uncontrolled proliferation and management of AI coding agent skills within large organizations. While skills are powerful because they encode domain-specific logic into an agent's context, their current lack of standardized versioning, review, and centralized governance creates significant technical debt. The speaker advocates for treating skills as first-class software assets, requiring dedicated practices like decomposition, mandatory registries, automated reviews, and formal lifecycle management (CDLC) to ensure reliability and scalability.

Key takeaways

  1. Manage Skill Sprawl with a Centralized Registry 17:33

    Due to the low barrier to entry for creating skills, organizations face an 'insane amount' of them (2 million+ on GitHub alone). A centralized registry is crucial for visibility, preventing overlap, and ensuring all teams use approved versions. This also helps mitigate non-technical users needing access without requiring full developer seats.

  2. Adopt the Context Development Life Cycle (CDLC) 27:50

    Just as code requires a Software Development Lifecycle (SDLC), skills and context require their own CDLC. Practices like skill reviews, automated testing, and version control must be applied to maintain quality and prevent 'rot' (skills going out of sync with the codebase).

  3. Decompose Skills for Modularity 20:40

    Instead of creating monolithic skills, break complex functionality into smaller, interconnected plugins. This allows agents to activate specific components and makes the skill set easier to maintain and debug.

  4. Enforce Governance via Registries 22:30

    Using a registry provides a single source of truth, allowing organizations to enforce policies (e.g., 'approved skills only,' minimum release age) and integrate security scanning tools like Snyk.

Watch on YouTube Full article

Put an Agent Inside Your App in 10 Minutes or Less with the GitHub Copilot SDK - Daniel Ward thumbnail

· 57:28

Put an Agent Inside Your App in 10 Minutes or Less with the GitHub Copilot SDK - Daniel Ward

This talk demonstrates how to rapidly embed custom AI agents into existing applications using the GitHub Copilot SDK. The session covers agent architecture—defining an agent as an LLM augmented with tools and a looping mechanism—and provides two coding demos (in C#) showing basic functionality like weather queries, streaming responses, and creating custom tools. For build engineers, the focus is on advanced use cases such as automated incident response (generating suggested fixes and opening Pull Requests from production logs) and building comprehensive daily briefing systems that integrate multiple enterprise services (Jira, Teams, GitHub).

Key takeaways

  1. Agent Architecture 17:53

    An AI agent is fundamentally an LLM combined with external tools and a looping mechanism. The LLM handles the creative analysis, while the tools allow it to perform deterministic actions (e.g., fetching web data or querying APIs).

  2. Copilot SDK Functionality 3:35

    The Copilot SDK is an open-source library that allows calling GitHub Copilot (or other LLMs like Anthropic/OpenAI) from code. It supports multiple languages (TypeScript, Python, Go, C#, etc.) and provides granular control over sessions, including event handling (`onEvent`) for streaming responses.

  3. Automated Incident Response 51:01

    A powerful use case is connecting production errors to automated fixes. The process involves the SDK collecting logs, using Copilot to suggest a fix based on stack traces, and then programmatically opening a draft Pull Request (PR).

  4. Reliability vs. Prompting 53:21

    For repeatable, mission-critical workflows (like daily reports), using deterministic code with the SDK is significantly more reliable than relying solely on prompt chaining, as failures in a chain compound exponentially.

Watch on YouTube Full article