Topic

GitHub Repository

All digests tagged GitHub Repository

From Video to Voice: Build Faster with TensorRT Model Connect thumbnail

· 32:38

From Video to Voice: Build Faster with TensorRT Model Connect

TensorRT Model Connect (TRT MC) is a feature designed to drastically simplify the deployment of open-source AI models into production applications. It provides a consistent, low-overhead workflow that allows developers to convert models (e.g., PyTorch checkpoints) into optimized, deployable 'bundles.' This process handles model analysis, optimization (including graph fusion and tactic selections), and runtime generation, enabling fast, end-to-end inference across diverse model types and hardware configurations, including multi-device scaling.

Key takeaways

  1. Simplified Model Deployment Pipeline 2:00

    TRT MC streamlines the process from open-source model to deployable application. Developers use a simple Python command to convert a model checkpoint into a deployable bundle, abstracting away complex pipeline plumbing (e.g., auto-regressive loops).

  2. Support for Diverse AI Workloads 5:40

    The tool supports a wide range of model architectures beyond LLMs, including audio generation (Bark, Nvidia's audio model), traditional CNNs, feature extraction (DINO v3), image generation (Flux), object detection, and video generation (Minimax H3 LTX).

  3. Multi-Device and Scaling Capabilities 25:50

    TRT MC supports multi-device setups, allowing large models to run in parallel across multiple GPUs (e.g., two or four Jetson/DGX Spark units) for accelerated inference, which is crucial for large-scale production systems.

  4. Full-Duplex and Complex Inference 19:10

    The platform supports complex, low-latency use cases, such as full-duplex voice chat (Nemotron Voice), which eliminates the need for separate ASR, LLM, and TTS pipelines, and advanced image understanding tasks like depth mapping and point cloud generation.

Watch on YouTube Full article

Agents & Arbiters - An Adventurer’s Guide to Multi-Agent Collaboration with LangGraph.js - Guy Royse thumbnail

· 59:56

Agents & Arbiters - An Adventurer’s Guide to Multi-Agent Collaboration with LangGraph.js - Guy Royse

The talk introduces multi-agent collaboration using LangGraph.js as an advanced pattern for building complex, interactive systems that move beyond fragile, scripted logic. Instead of anticipating every user action with nested `if` statements, the system uses autonomous agents (LLMs) to contribute perspectives and make decisions. The architecture is built around a graph structure that orchestrates specialized nodes—including routers, experts, arbiters, and committers—to manage state changes and generate coherent responses.

Key takeaways

  1. Agent Definition 24:28

    An agent is defined as an LLM with a system prompt defining its purpose, coupled with a collection of tools that allow it to interact with the world. These agents are composable within a graph structure.

  2. Graph Workflow Components 34:05

    The system uses an orchestration workflow (router, classifier, agents, arbiter, committer) to manage complex interactions. The router determines which specialized nodes are relevant for a given input, and the arbiter reconciles conflicting suggestions from multiple agents.

  3. Conditional Edges 38:38

    Conditional edges allow the graph's flow to be determined by an LLM's reasoning over the current state, enabling patterns like the Supervisor pattern and the ReAct (Reasoning and Acting) cycle. This is crucial for dynamic decision-making.

  4. State Persistence and Memory 48:50

    To solve context loss, the architecture utilizes a dedicated Agent Memory Server (a library/Docker image) that automatically compacts message history and extracts long-term facts asynchronously, providing continuous memory across sessions.

Watch on YouTube Full article

The Agentic Commerce Stack — Ahnaf Prio, Best Buy thumbnail

· 20:38

The Agentic Commerce Stack — Ahnaf Prio, Best Buy

The talk outlines the architectural shift required for 'Agentic Commerce,' moving beyond brittle browser automation (like DOM reading or screenshotting) toward standardized protocols. The core solution involves defining specific primitives—such as MCP, A2A, ACP, UCP, and AP2—that allow AI agents to interact directly with merchant APIs without triggering fraud alarms. Successful implementation requires rigorous testing using behavioral and protocol compliance 'evals.'

Key takeaways

  1. Agentic Commerce Scope 2:08

    Approximately 45% of all agent sessions on major platforms (e.g., ChatGPT, Google Gemini) are related to shopping, indicating a massive market opportunity ($7B to $65B by 2030).

  2. Failure of Early Agents 5:08

    Early attempts using screenshots and reading the DOM were slow, clunky, and brittle. Furthermore, automated browser actions often trigger fraud alarms at the payment stage.

  3. The Need for Standardization 7:36

    To scale, commerce must standardize its primitives. Instead of relying on search catalogs, merchants should provide structured product feeds to protocols like ACP and UCP. The process involves the agent calling a merchant checkout API directly (no browser needed).

  4. Payment Mandates with AP2 16:41

    Autonomous payments require more than just tokens. AP2 (Agentic Payment Protocol) is an extension that mandates defining the authorizing party, a spend ceiling, and a revocation URL.

  5. Testing with Evals

    Building agentic commerce requires intense testing (evals) focused on behavior, protocol compliance, and latency benchmarks. Failure to test can lead to agents being misused in production (e.g., asking programming questions).

Watch on YouTube Full article

Managed Deep Agents explained in 20 minutes thumbnail

· 18:17

Managed Deep Agents explained in 20 minutes

Managed Deep Agents provides an integrated framework to simplify the entire lifecycle of building, running, and deploying AI agents into production. It addresses the complexity of agent infrastructure by bundling the open-source Deep Agents harness with necessary components like durable execution, context management (via Context Hub), sandboxes, and scheduling capabilities, allowing developers to move from local business logic directly to a scalable, managed deployment on LangSmith.

Key takeaways

  1. Agent Architecture Components

    An agent requires three layers: 1) Business Logic (provided by the user, e.g., prompts/tools); 2) Harness (orchestrates context and passes data to the model); and 3) Infrastructure (runtime, sandboxes, etc.). Managed Deep Agents bundles these into a seamless package.

  2. Production Readiness 2:05

    The framework handles complex production requirements such as durable execution, fault tolerance, streaming, queueing, run cancellation, and rollbacks, which are necessary when moving agents from local development to cloud serving.

  3. Decoupled Context Management 5:05

    Context (instructions and skills) is stored in the dedicated Context Hub. This allows non-developers to edit and maintain agent context via a UI without requiring code changes or redeployments, significantly improving collaboration.

  4. Deployment Workflow 10:30

    The process involves initializing the project using `MDA innit research assistant`, defining components (e.g., tools in `tools/search.py`), and deploying via `MDA deploy`. This pushes context to Context Hub and creates a deployment on LangSmith.

Watch on YouTube Full article

Build a Full-Stack GenAI Project in 4 Hours (FastAPI, React, Supabase) thumbnail

· 3:51:50

Build a Full-Stack GenAI Project in 4 Hours (FastAPI, React, Supabase)

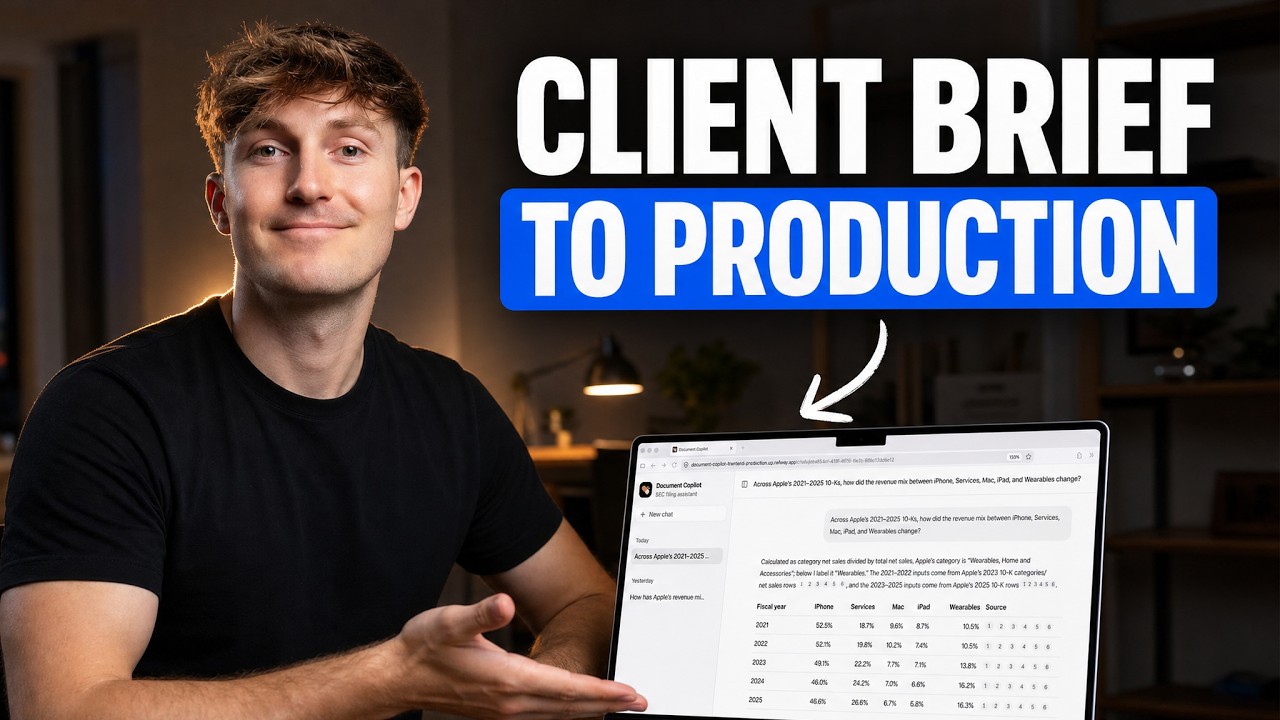
This tutorial provides an end-to-end guide for building a production-grade Retrieval Augmented Generation (RAG) application—a Document Copilot. The project uses SEC filings data and demonstrates the complete AI engineering workflow: from initial client brief analysis to setting up the full stack (FastAPI, React/TypeScript, Supabase Postgres with pgvector). Key phases covered include database schema design using SQLAlchemy/Alembic, implementing user authentication via Supabase Auth, building a front-end chat interface, and establishing a robust document ingestion pipeline that converts messy HTM files into structured Markdown chunks for vector embedding.

Key takeaways

  1. Full Stack GenAI Architecture 30:45

    The system is designed as a mono repo using FastAPI (backend) and React/TypeScript (frontend), connected via Supabase Postgres, which utilizes the pgvector extension for efficient vector storage and retrieval.

  2. Data Ingestion Pipeline 3:44:09

    Raw SEC filings (HTM format) are processed using Dockling to convert them into clean Markdown. This structured data is then chunked, embedded via OpenAI, and stored in the database for RAG retrieval.

  3. Database Management

    The project utilizes SQLAlchemy and Alembic for defining models (Users, Documents, Chunks, Messages) and managing schema migrations, ensuring a structured development process.

Watch on YouTube Full article