Topic

Exa

All digests tagged Exa

Your Coding Agent Is 6 Months Out of Date — Jakub Hojsan, Exa thumbnail

· 12:23

Your Coding Agent Is 6 Months Out of Date — Jakub Hojsan, Exa

Jakub Hojsan of Exa details how they built specialized search capabilities for coding and code-review agents, addressing the critical issue of Large Language Model (LLM) knowledge cutoffs. Exa's solution provides context-rich, token-efficient highlights by distilling massive documents (e.g., 100,000 characters) down to only the necessary snippets (e.g., 500 characters) for the LLM. The talk emphasizes that simply adding a web search tool is insufficient; agents require explicit rules for when and how to search. Exa's platform offers transparency (full search trace), cost efficiency, and model-provider independence, allowing integration across various LLMs and tools via the Exa MCP.

Key takeaways

  1. The Knowledge-Cutoff Gap in Code Review

    LLMs suffer from a knowledge cutoff, meaning they cannot review changes (like PRs) made after their training date. This gap is critical in code review, where reviewing recent changes requires access to current repository information.

  2. Context-Rich, Token-Efficient Highlights 0:02

    Instead of returning entire web pages, Exa's search engine uses an interpretation step to distill large documents into small, highly relevant snippets (e.g., 500 characters) for the LLM, significantly improving context quality and efficiency.

  3. Agents Need Explicit Search Rules 0:04

    Bolting on a web search tool is not enough. Agents must be provided with explicit rules (e.g., 'When a diff bumps a dependency, look at the upstream source') to guide when and how to use the search tool.

  4. Exa's Technical Advantages 0:04

    Exa provides transparency by giving the full search trace (exact queries, sources, and highlights), offering cost-effective pricing compared to native web search APIs, and ensuring model-provider independence.

Watch on YouTube Full article

The Search Engine for the Agentic Web — Will Bryk, Exa thumbnail

· 17:49

The Search Engine for the Agentic Web — Will Bryk, Exa

The talk introduces Exa, a search engine designed specifically for AI agents, arguing that traditional search engines (like Google) are fundamentally flawed because they are built for human recommendation rather than precise information retrieval. The core premise is that as AI systems become ubiquitous, the volume of searches issued by machines will surpass human searches by a thousandfold by 2026. Exa addresses this by providing a high-quality, customizable search API that enables agents to perform complex, database-like queries over the world's information, moving beyond simple keyword matching.

Key takeaways

  1. AI Search Volume Prediction

    The speaker predicts that in 2026, the number of searches issued by AI systems will exceed those issued by humans. This volume is expected to increase by a thousandfold in the following years, necessitating a specialized search infrastructure.

  2. The Flaw of Recommendation Engines 5:10

    Mainstream search engines are designed as recommendation engines, meaning they prioritize suggesting related content (e.g., 'shirts with stripes' when 'shirts without stripes' is queried) rather than providing exact, database-level answers. AI agents require the opposite: perfect retrieval.

  3. The Perfect Search Thought Experiment 10:05

    The ideal search involves running a Language Model (LLM) over a complex query and a document pair to determine a match. While this is highly accurate, scaling it to a trillion documents costs millions per query, making cost-optimization the primary engineering challenge.

  4. The Business Catalyst 13:45

    The company's business model was catalyzed when external users requested programmatic API access to their search engine, proving the need for an AI-focused search API, rather than just a consumer product.

Watch on YouTube Full article

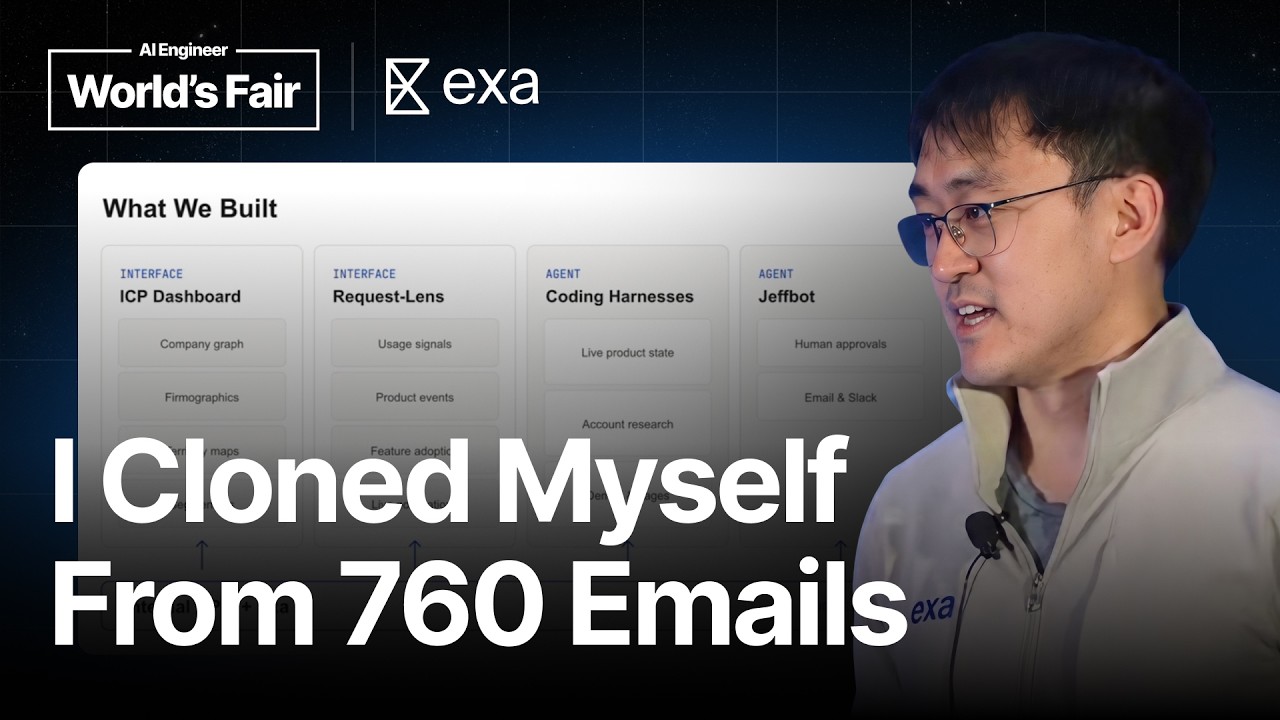
Knowledge Systems: The New GTM Stack — Jeffrey Wang, Exa thumbnail

· 18:49

Knowledge Systems: The New GTM Stack — Jeffrey Wang, Exa

Jeffrey Wang argues that Go-To-Market (GTM) strategy must be treated as an AI engineering problem. The core thesis is that GTM is fundamentally a data problem, requiring the creation of a 'live model of your world' that autonomous agents can act upon. He details systems like Exa (a search engine for agents), the ICP dashboard for classifying the Total Addressable Market (TAM), and Request Lens for real-time customer signal detection. Key architectural principles include making the system API-first, recognizing that consistent UIs still complement flexible chatbots, and prioritizing arbitrary customizability over rigid build vs. buy decisions.

Key takeaways

  1. GTM as a Data Problem 4:56

    The goal is to build a live model of the world—combining internal data (customer usage) with external data (web activity, company information)—that agents can programmatically act on. This shifts GTM from a purely sales function to an engineering challenge.

  2. Agent-First Requires API-First 16:59

    For any agent system (whether it's a GUI or a chatbot) to access data, the underlying systems must expose robust programmatic interfaces (APIs). This is critical for enabling agents to function.

  3. System Components: ICP Dashboard & Request Lens 8:38

    The ICP dashboard uses Exa's embeddings over the internet to classify every company in the TAM and estimate anticipated spend. Request Lens provides real-time alerts when significant customer signals occur (e.g., signups, search surges).

  4. The Value of AI Cloning (Jeffbot) 13:42

    An agent can be trained on historical data to mimic a user's professional style and decision-making. Jeffbot was built by analyzing 760 emails and hundreds of past decisions, creating 'evals' to calibrate its judgment against the founder’s own behavior.

Watch on YouTube Full article