Voice Agents Can Just Do Things — Charlie Guo, OpenAI
Summary
The presentation challenges the common misconception that voice agents must respond using speech. Instead, the speaker argues that voice models can utilize three distinct, non-mutually exclusive modes: Speech-to-Speech, Speech-to-Action, and Event-to-Speech. For developers, the key takeaway is that building voice agents is simplified by recognizing that existing application verbs (API endpoints, React hooks) can be directly exposed as tools for the model to call. Furthermore, the talk details the technical shift toward native audio processing (audio in, audio out) and introduces advanced models like GPT-realtime 2, which adds reasoning and structured tool calling capabilities.
Key takeaways
-
The Three Modes of Voice Interaction
0:12
Voice interaction is categorized into three modes: Speech-to-Speech (e.g., coaching, translation), Speech-to-Action (user talks, model uses tools, e.g., form filling), and Event-to-Speech (model reacts to an event, e.g., proactive alerts).
-
Developer Focus: Exposing Verbs as Tools
10:58
Developers can integrate voice by treating existing application verbs (API endpoints, React hooks) as callable tools, allowing the model to drive the existing software rather than just generating text.
-
The Shift to Native Audio Processing
Modern voice models are moving away from the chained approach (transcribe speech -> LLM -> text -> audio) to native audio tokens, which preserves critical context like tone, cadence, and emotional impact.
-
GPT-realtime 2 Capabilities
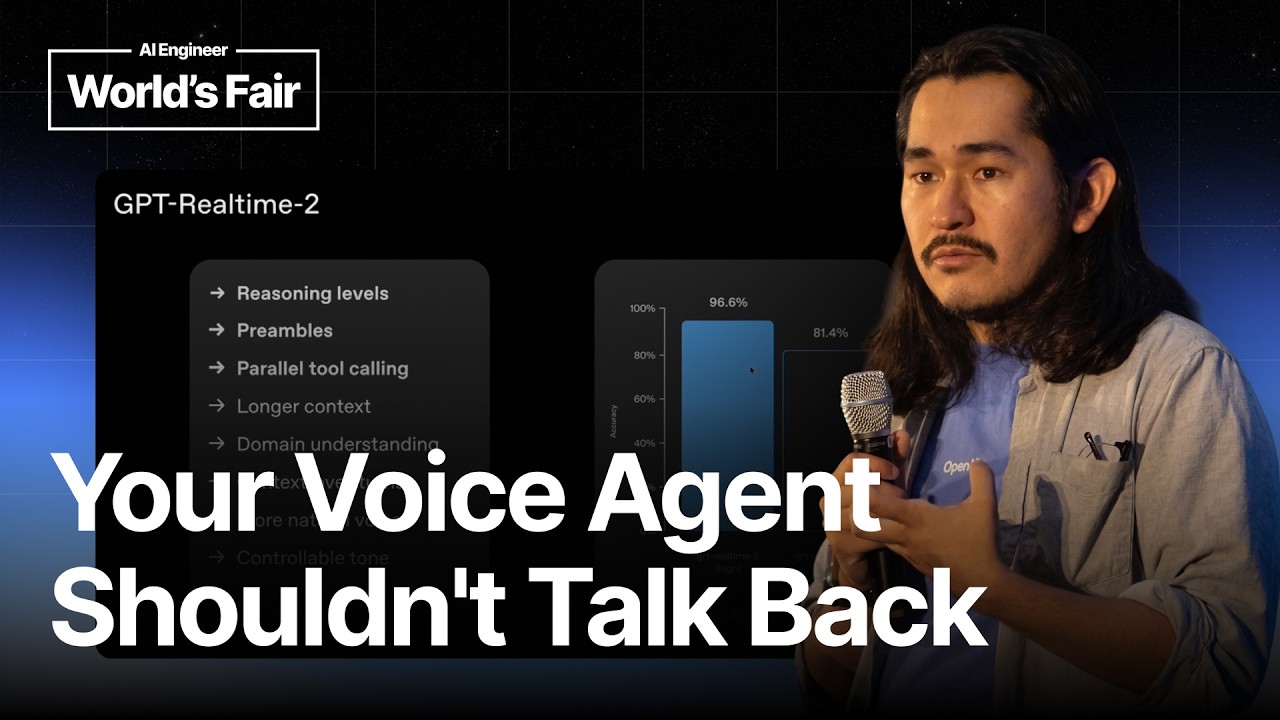
The latest model in the real-time family offers reasoning capabilities, parallel tool calling, and 'preambles' to manage user expectations while actions are performed in the background.
Technical details
-
Speech-to-Action Use Cases
350s
Applications include automating complex tasks like filling out government forms (talking for minutes vs. hours of typing) and guiding creative processes (e.g., composing music or painting) when the user's taste exceeds their operational ability.
-
System Architecture
The ideal system combines all three modes. The underlying technical shift involves moving from turn-based abstraction to continuous streaming audio in and out.
-
Model Enhancements
GPT-realtime 2 provides reasoning to the audio medium, allowing the model to 'think' before speaking. It also supports parallel tool calling and 'preambles' to communicate background processing to the user.
Mentioned resources
- OpenAI
- GPT-realtime 2
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.