Processing Documents: Jev vs OSS Models
Summary
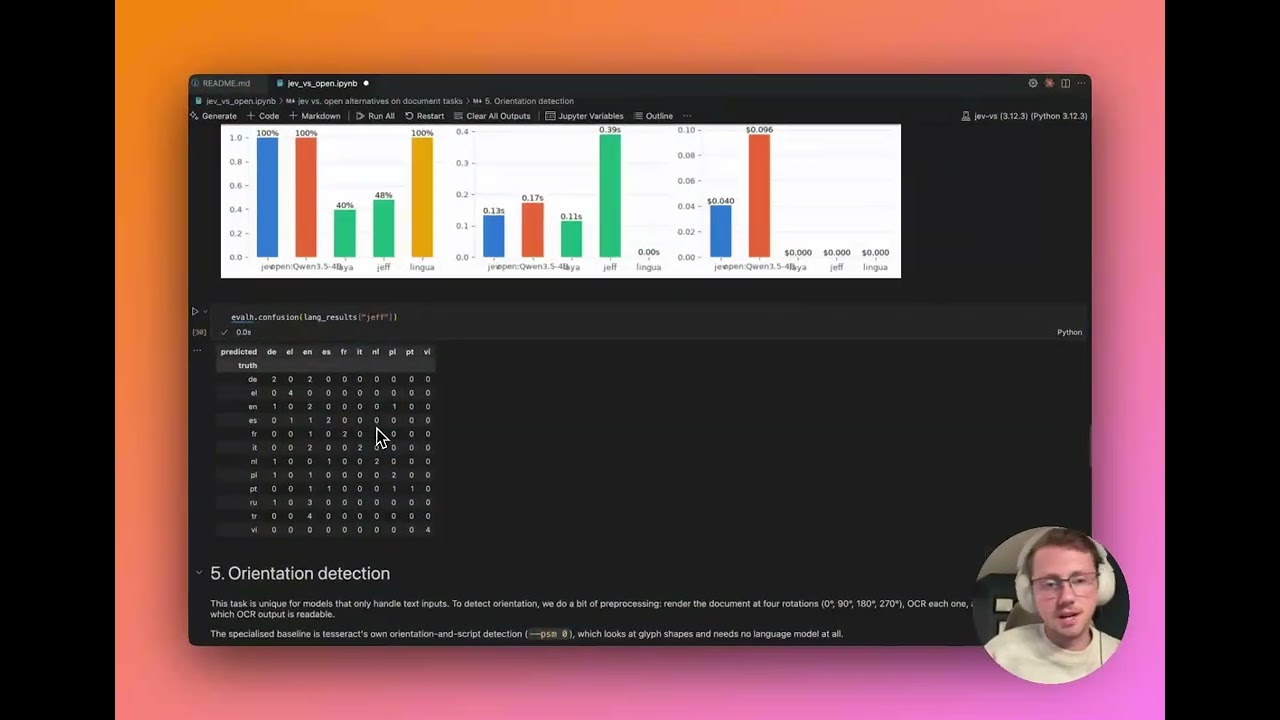
This video compares several model architectures (Jev, Quen, Leia, Jeff) for automating decision-making and classification tasks within document processing pipelines. The core finding is that the open decoder model, Quen, performs remarkably close to the generalized classifier, Jev, across various tasks (language detection, document classification, document routing). The approach demonstrates that robust classification can be achieved without requiring pre-training on specific labels, making it highly valuable for building flexible, automated document pipelines.
Key takeaways
-
Quen's Performance in Classification
The Quen decoder model, which is a standard Language Model (LM) and not specifically trained for classification, showed accuracy very close to Jev in tasks like language detection and document routing, suggesting its utility for general document understanding.
-
Model Architecture Comparison
7:16
Jev is a generalized classifier trained with reinforcement learning, optimized for confidence scoring. Quen is a decoder LM. Leia and Jeff are encoder models (Leia predicts a mask token; Jeff is good for entity/relation extraction). While encoders are smaller and easier to fine-tune, they were less accurate than the decoders in this demonstration.
-
Document Processing Tasks Covered
The models were tested on five key document pipeline tasks: Language Detection (using Lingua as baseline), Orientation Detection (using Tesseract as baseline), Document Classification, Document Splitting, and Document Routing/Triage.
Technical details
-
Input Preparation (LightParse)
143s
The open-source parser, LightParse, is used to gather necessary inputs for classification, including detecting document complexity, text coverage, running OCR, and generating per-page screenshots for orientation detection.
-
Classification Input Format
220s
All models are normalized to accept a 'state' (the input text) and a set of 'questions' (the possible choices/labels), allowing for generalized classification.
-
Document Routing/Triage
This task uses metadata (e.g., OCR confidence, text length, complexity stats) as input to classify whether a page requires an upgrade to a more advanced pipeline (e.g., LlamaParse).
Mentioned resources
- LlamaIndex
- jev_vs_oss
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.