The AI Bill Is Too Damn High: Tokenomics 101 — Eugene Cheah, Featherless AI
Summary
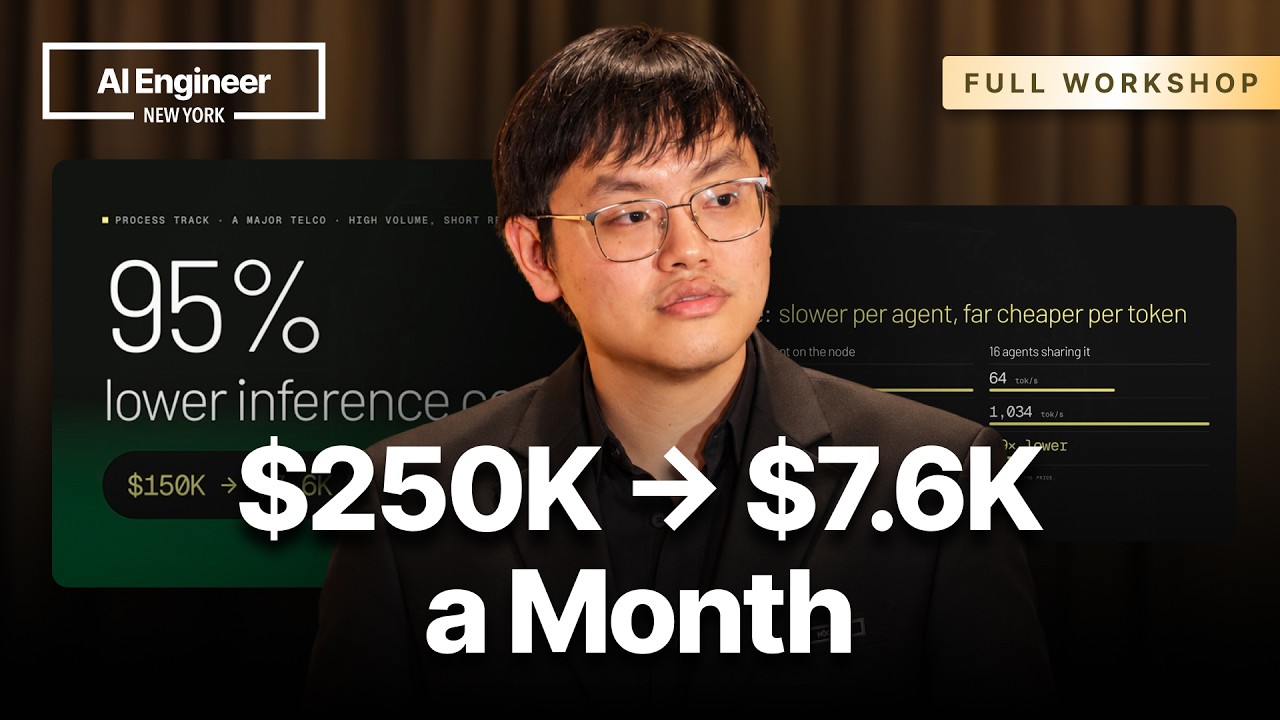
This talk provides a comprehensive guide to optimizing and controlling massive AI inference costs (tokenomics) at scale. The speaker outlines four critical moves—Measure, Right-size, Buy Capacity Well, and Check Processes—to prevent runaway spending. Key strategies include splitting API keys by department/use case, utilizing specialized models like classifiers (JAF), optimizing agentic vs. process workloads, and ensuring that infrastructure scaling (e.g., dedicated GPU capacity) is based on actual traffic patterns, not just speed.
Key takeaways
-
Measure Token Usage Granularly
0:03
Do not use a single shared API key. Start by splitting keys by department, then by major use case, to accurately track where tokens are being spent. This measurement is the foundation for all subsequent cost-saving efforts. (3:23)
-
Right-size Models and Workloads
0:09
Identify the workload type: Agentic (long-running, high context, input-heavy) versus Process Automation (short context, volume-game). Use specialized, cheaper models (e.g., classifiers) as drop-in replacements for expensive frontier models (e.g., Opus 4.8). (9:27, 12:42)
-
Optimize Capacity Buying
0:30
Understand the cost trade-off: increasing tokens per second (speed) does not scale linearly with cost. For background or non-user-facing tasks (like CI/CD), run at a much slower, cheaper tokens per second rate. (30:07)
-
Review Processes and Governance
0:19
The biggest cost savings often come from process improvements, not just model changes. Implement governance by giving teams model *labels* (e.g., 'Finance Agent') rather than specific model names to maintain control and flexibility. (19:27)
Technical details
-
Workload Types
5s
AI workloads fall into two major tracks: Agentic (long-running, multi-turn, high input/context usage) and Process Automation (short context, high volume/task-isolated, e.g., call center filtering). (5:12)
-
Model Optimization
12s
Classifiers (e.g., JAF) are a new class of cheap models focused solely on making decisions and classification, offering a significant cost advantage over general-purpose models. (12:42)
-
Model Deployment Strategy
15s
For optimal cost, use a tiered approach: deploy the best frontier model (e.g., for planning/review) and pair it with a faster, cheaper model (e.g., for implementation/workers). (15:47)
-
Data and Fine-Tuning
48s
To fine-tune a model, the ideal process is to generate a 'golden trace' dataset (high-quality, successful examples) rather than using all raw traces. This allows for targeted, high-impact training. (48:02)
-
Infrastructure Scaling
32s
When deploying at scale, the goal is to match the target tokens per second (T/s) to the task priority. Background or non-user-facing tasks should run at a much lower T/s rate to save costs. (32:22)
Mentioned resources
- Felis AI
- PicoCreator
- Tokenomics Tracking Tool
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.