Agent Memory Is Solved. Agent Learning Isn't. — Karthik Ranganathan, Yugabyte
Summary
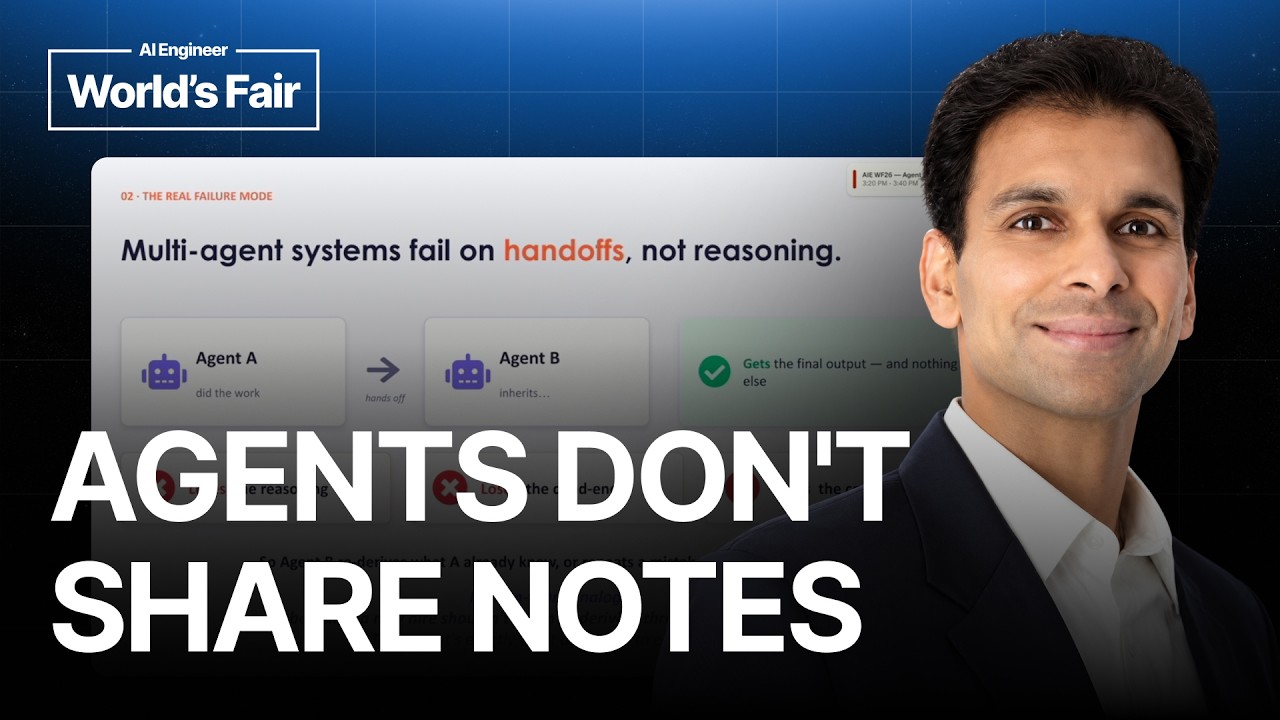
The talk addresses the critical distinction between per-agent memory (which is considered solved) and shared, collective learning across multiple agents (which remains an unsolved problem). The core challenge is that when an agent passes work to another, it loses the reasoning, dead ends, and full context, forcing the receiving agent to re-derive information and burn tokens. Yugabyte introduces Meko, an agent-native persistence layer designed to solve this by enabling agents to promote private memories into a governed, shared data pack, thus creating durable, traceable, and reusable collective knowledge.
Key takeaways
-
Agent Memory vs. Agent Learning
Agent memory is solved (per-agent context extraction and reuse). However, true learning happens when a group of agents collaborate, requiring infrastructure that supports shared, governed context, which is currently lacking.
-
The Lost Context Problem
3:57
When Agent A hands off work to Agent B, it typically only passes the output (e.g., an MD file) but loses the reasoning, dead ends, and full context. This forces Agent B to re-derive the information, wasting tokens and resources.
-
Misconceptions in AI Memory
5:57
The speaker debunks five common misconceptions: more memory does not equal learning; shared state is not shared knowledge; running RAG on everything is not equal to quality learning; fine-tuning is not scalable for persistent lessons; and bigger context windows are often an expensive failure.
-
Meko's Solution: Shared, Governed Context
12:07
Meko is an agent-native persistence layer that allows agents to push private context into a shared space (a data pack). This context can be promoted, ensuring it is governed, traceable to its source, and available to multiple agents or humans.
Technical details
-
RAG Pipeline Improvement
637s
By tuning a distributed RAG pipeline, the speaker achieved a significant jump in faithfulness from 14% to 82% using an MD benchmark, while simultaneously reducing the context chunk size from over 7,000 chunks to about 1,000 chunks (a 1/7 reduction).
-
Meko Data Pack Structure
727s
Meko exposes a data pack that is not limited to a single database type but integrates multiple types (Vector, Graph, Relational, NoSQL) to store aspects of context, knowledge base, memory, and conversations.
-
Resumability and Sharing
1020s
The system demonstrates resumability by allowing a session to be killed and restarted with the same agent, even if the context was stored in a shared data pack, proving that the context is decoupled from the specific IDE or agent instance.
-
Cost Efficiency
1020s
By retrieving context from the Meko memory instead of forcing the LLM to re-derive it, the system significantly reduces token burn, saving costs compared to constantly traversing empty files or relying solely on the LLM's internal reasoning.
Mentioned resources
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.