Stop Renting Intelligence: The Train-to-Deploy Loop for Specialized AI — Fireworks AI
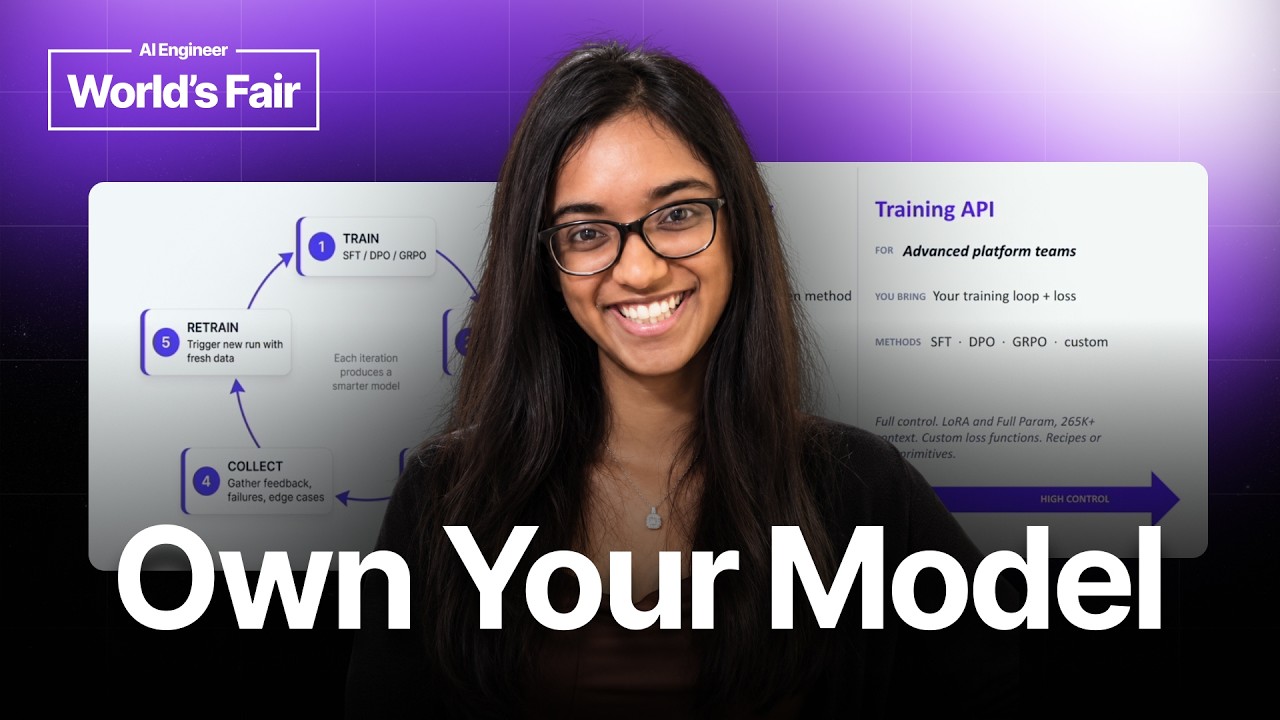
The talk details the shift from expensive closed-source AI models to open-source alternatives, emphasizing that performance parity can be achieved through continuous customization and fine-tuning. Fireworks AI facilitates this transition by providing a comprehensive 'train-to-deploy' loop. Key technical advancements include the FireAttention inference engine, custom CUDA kernels, and specialized training products (Training Agent, Managed Training, Training API) that ensure high quality, low latency, and seamless deployment with features like hot-loading and numerical fidelity.
Key takeaways
-
Open Models are Production-Ready
0:01
Open-source models are largely production-ready, exemplified by models like GLM 5.2, especially for coding use cases. The quality gap with closed models is closed through customization and continuous improvement.
-
The AI Stack is a Continuous Loop
0:01
The industry is moving from single-serve model deployment to a continuous loop that improves the model through iterative training and inference using the same open-source model.
-
Proven Performance Gains
0:03
Customer case studies demonstrate significant performance improvements: Cursor's Composer 2 achieved 13x faster inference, Vercel saw a 40x latency improvement, and Genspark achieved a 12% quality improvement using Reinforcement Fine-Tuning (RFT).