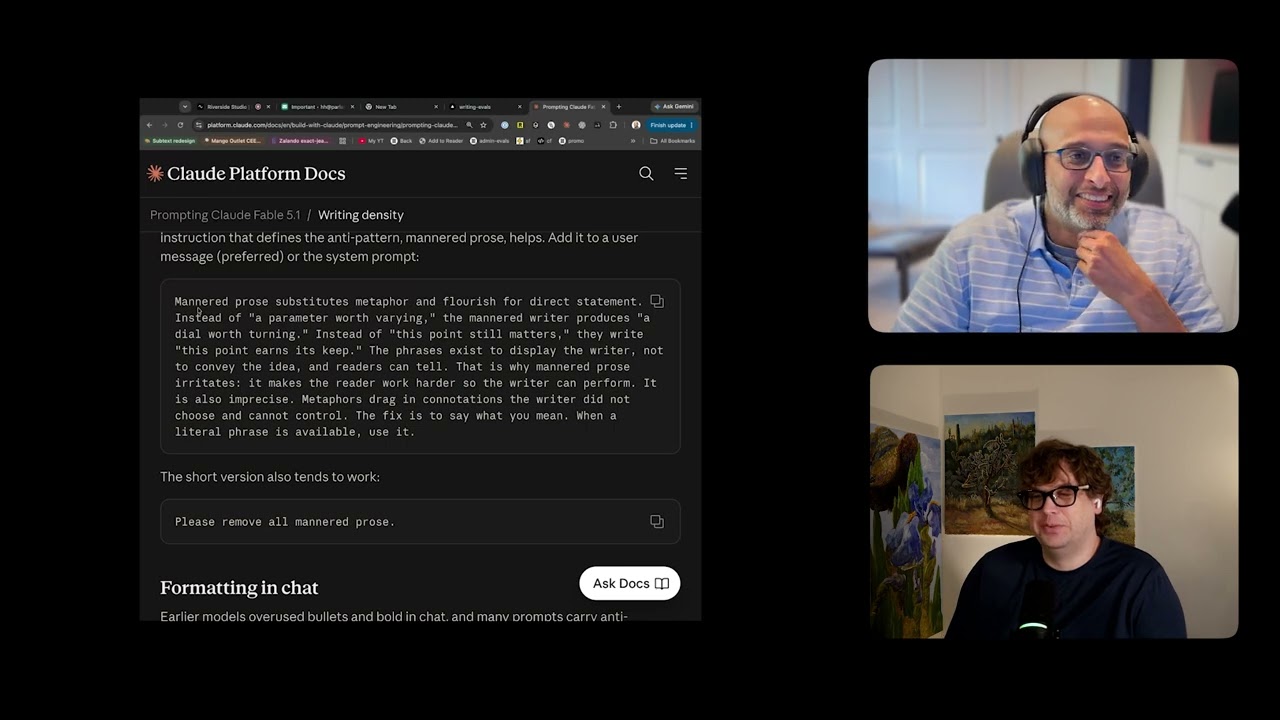
Why The Prompt Matters Less Than The Context
The discussion analyzes the effectiveness of various system prompts for Large Language Models (LLMs), concluding that the surrounding context is often more influential than the specific, highly structured wording of the prompt itself. The speaker argues that overly elaborate or 'mannered' prompts (which use phrases like 'parameter worth varying' or 'dial worth turning') are often imprecise and detrimental. Instead, the focus should be on providing clear, literal context and examples to guide the model's output.
Key takeaways
-
Context Over Prompt Wording
2:20
The performance of the LLM was found to be highly dependent on the context provided, suggesting that the prompt itself may not be the primary determinant of quality. The speaker notes that the 'unmannered' prompt performed surprisingly well, challenging the assumption that complex, handcrafted rules are always superior.
-
Critique of 'Mannered' Prompts
0:10
The speaker criticizes overly formal or 'mannered' prompts, arguing that they are often imprecise, use unnecessary jargon, and force the reader to work harder for the writer's performance. The fix suggested is to use literal phrases when available.
-
Inconclusive Findings
3:30
The analysis of prompt effectiveness was deemed inconclusive due to limited data (e.g., 'only looked at five examples'), indicating that there is no single 'winner' prompt structure.