Why AI Writing Still Reads Like Slop — Louis-François Bouchard, Towards AI
Summary
Louis-François Bouchard introduces 'slop,' defining it as the common flaws in AI-generated writing (e.g., overused words, vagueness, repetition, hallucination, and lack of unique tone). To address this, he details the creation of a new benchmark, Tone-Bench, designed to measure a model's ability to write in a specific, consistent voice. The benchmark involves generating 10 scripts, five drafts per model, and utilizing four LLM judges across nine detailed metrics. He discusses the high cost and complexity of building such an evaluation pipeline and provides practical strategies for improving AI output, such as using extremely long prompts and merging drafts from cheaper models.
Key takeaways
-
Defining 'Slop' in AI Writing
Slop is characterized by overused words, excessive generality, saying nothing specific, repetition, hallucination, and a generic, non-unique tone (00:00).
-
The Tone-Bench Methodology
9:04
The new benchmark measures creative writing quality by assessing if a model can replicate a specific voice. The process involves sending a detailed prompt (including examples and style guides) to generate 10 scripts, with 5 drafts generated per model (05:44).
-
Evaluation Metrics and Judges
18:30
The quality is measured using nine metrics, including tone, pure writing quality, adherence to instructions, research accuracy, and a custom 'slop' score. Evaluation relies on four LLM judges, who score the output using a detailed categorization and justification system (09:14).
-
Cost and Variability in Evaluation
Building the benchmark is highly expensive, costing thousands of dollars, especially when adjusting rubrics or input prompts. The process is designed to check for intra-model variability by generating multiple drafts (14:15).
Technical details
-
Benchmark Structure
719s
Tone-Bench uses 10 different scripts, 5 drafts per model, and 4 LLM judges. The evaluation pipeline analyzes the generated script against detailed rubrics and a comprehensive prompt (07:19).
-
Evaluation Metrics
1110s
Nine metrics are measured, including tone (adaptability to a specific voice), pure writing quality, instruction adherence, research accuracy, and a custom slop score (11:10).
-
Model Performance Observations
The speaker notes that while Opus 5.5 is highly rated, GLM 5.3 flash is extremely good and significantly cheaper (50 times cheaper) for scale, suggesting a balance between quality and cost (16:21).
-
LLM Judge Bias
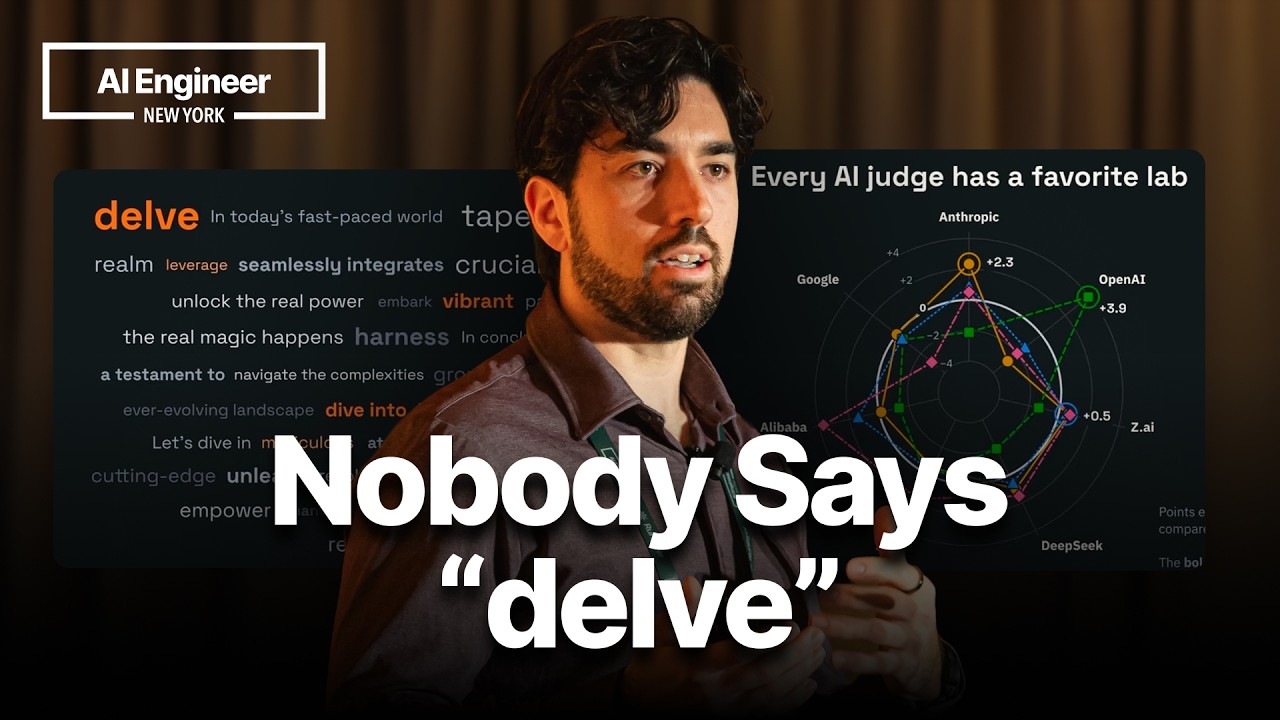
A key finding is that LLM judges exhibit strong preferences, with models showing a tendency to favor their own family (e.g., OpenAI models preferring other OpenAI models). Using diverse model families is recommended to mitigate this bias (12:38).
Mentioned resources
- Tone-Bench
- Towards AI
Channel & topics
Watch on YouTube · Back to latest
This independent, AI-assisted summary is provided for commentary and informational purposes. It may contain errors or omit important context. Please watch the original video for the creator's complete presentation. Video, thumbnail, and related copyrights belong to their respective owners.